@f
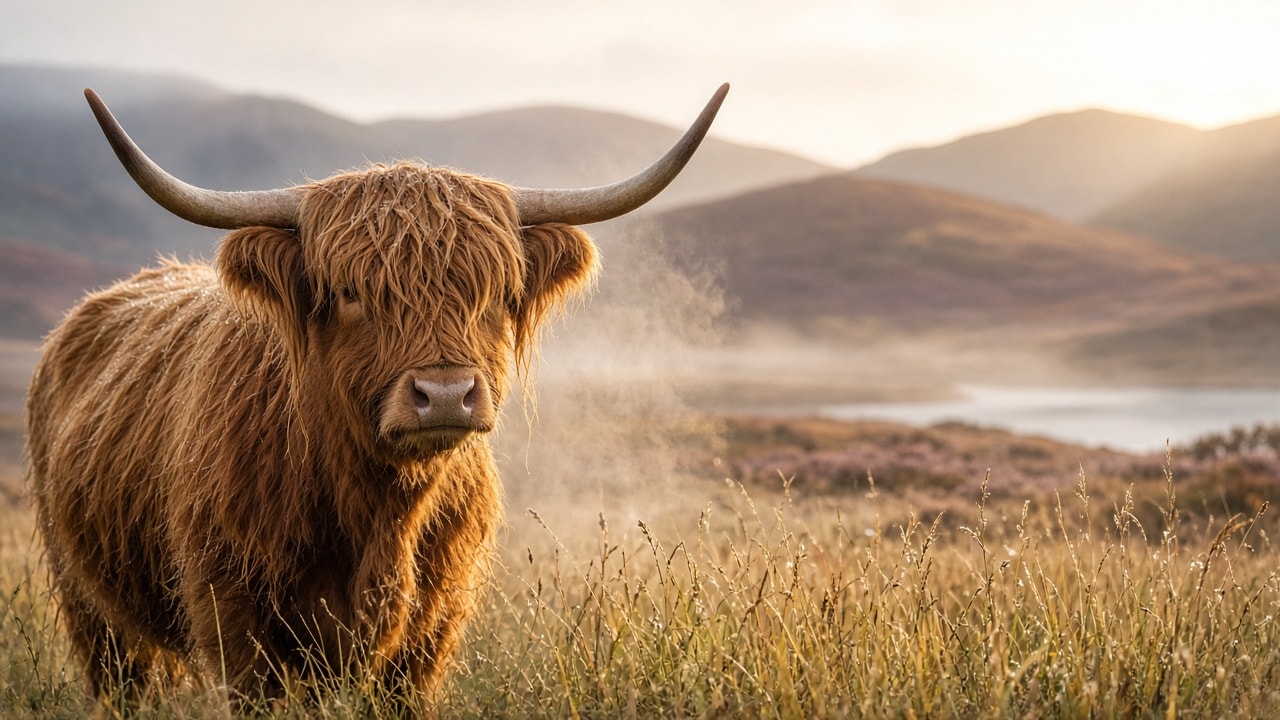
Photoreal telephoto shot of a shaggy ginger Highland cow with long upswept horns and a fringe over its eyes, standing in tall dewy golden grass with its breath steaming in the cold air, golden backlight from the upper right, misty brown and purple hills, pink heather, and a pale loch behind.
A photoreal wildlife photograph of a shaggy ginger Highland cow standing in tall golden grass in a misty Scottish glen at sunrise, in a wide landscape 16:9 frame. The cow stands in the left half of the frame facing the camera, its long rust-orange and copper coat thick and wavy, with tiny dew drops caught in the hair. A heavy fringe of hair hangs over its eyes, its broad pink-brown nose and muzzle are sharp and detailed, and a pair of long, pale, upswept horns curve outward and up from its head. A cloud of warm breath and mist drifts to the right of its head in the cold morning air. In the foreground, tall dry golden grass and dewy seed heads are softly out of focus. Soft golden backlight from a low sun in the upper right makes the edges of the coat glow and fills the glen with warm haze. In the background, blurred rolling hills in muted brown, mauve, and purple tones fade into the mist, with patches of pink heather and a pale silver loch in the right middle distance. Shallow depth of field, 200mm telephoto compression, natural colors, calm, quiet mood. No people, no fences, no text, no watermark.
Build an image-ready and motion-ready brief for one hero shot of an old stone farmhouse at the end of purple lavender rows in Provence at sunrise: farmhouse and trees, lavender rows, landscape depth, light, fixed details, a motion map, and two prompt seeds: a 16:9 still image and an image-to-video animation.
Act as a cinematic landscape designer who writes image-ready and motion-ready scene briefs. Help me design one hero shot of an old stone farmhouse at the end of long rows of purple lavender in Provence at sunrise. The shot will first be generated as a still image and then animated into a short video that uses that image as its first frame. Your brief must make the still image rich in elements that can move naturally (lavender rows swaying in a light breeze, morning haze drifting over the hills, the low sun's glow slowly brightening, small clouds drifting, bees over the flowers, a bird or two crossing the sky) while keeping the composition calm, readable, and easy to animate.

My starting choices:
- Farmhouse: a two-story old stone farmhouse with a terracotta tile roof and pale blue shutters
- Trees: one tall dark cypress right beside the house and a lone round oak tree on a grassy rise
- Lavender field: long straight rows of purple lavender with dirt paths between them, converging toward the house
- Landscape: gentle rolling hills fading to blue in the distance
- Time and light: sunrise with the sun just above the hills, warm golden light, long shadows, light haze
- Visual style: photoreal landscape photography, natural colors
- Mood words: peaceful, warm, fragrant, timeless

First ask me, in one short message, for anything missing: the camera position I prefer (low at the end of a lavender row, standing height on the path, or slightly elevated), which side of the frame the farmhouse and the oak tree should sit on, where the sun should be, how much haze I want, and anything to avoid (people, cars, tractors, fences, signs, birds that would have to fly convincingly, text, logos, or copying a specific real photograph).

Then produce the brief with these sections:

1. **Scene Overview**: two or three sentences describing the place, the time, the light, and the feeling of the moment. Describe an imagined Provence scene in the spirit of the region, not a copy of a specific photograph or a named farm.

2. **Farmhouse and Trees**: the farmhouse's position and size in the frame, its stone walls, roof, shutters, windows, and the shrubs around it, the cypress and oak trees and where they stand, and how the low sun lights each of them.

3. **Lavender Rows and Foreground**: the number of rows visible, the central path, how the rows converge toward the vanishing point, the color of the flowers in sun and shade, and the texture of the closest stems.

4. **Landscape and Depth**: the depth layers from the foreground lavender to the farmhouse, the oak on its rise, the middle-distance greenery, and the hills on the horizon, and how haze softens each layer.

5. **Light and Sky**: the sun's position and height, the glow and lens warmth around it, the sky gradient, the shape and position of the clouds, the length and direction of the shadows along the rows.

6. **Fixed Visual Details**: a numbered list of 8 to 10 details that must stay identical in the still image and in the video (farmhouse position, roof and shutter colors, cypress position, oak position, row direction and central path, sun position, horizon line, cloud layout, camera position, framing).

7. **Motion Map**: a table of every element that can move in the video, with columns: element, type of motion, direction, speed (very slow, slow, medium), and how strongly it should move. Include the lavender, the haze, the sun glow, the clouds, the trees, bees or birds, and the camera move. Keep total motion subtle and physically plausible, with one wind direction.

8. **Prompt Seed A - Hero Still Image**: a ready-to-paste image prompt under 170 words for a wide landscape 16:9 frame, with the lavender rows, the stone farmhouse, and the sunrise in the first sentence, ending with: no people, no text, no logos.

9. **Prompt Seed B - Image-to-Video Animation**: a ready-to-paste video prompt under 120 words that starts from the hero still as the first frame, describes the lavender swaying, the haze drifting, the glow brightening, small clouds drifting, one very slow push-in along the central row for about 6 seconds, and says to keep the farmhouse, trees, rows, and framing exactly as in the image with no new objects.

Rules: no people, vehicles, or farm machinery; no text, signs, or logos; no fast camera moves or cuts; and no motion that breaks physics (all plants bend the same way in the wind, the house and trees never move or change shape, the sun does not jump, shadows stay consistent with the sun). Use short paragraphs and lists.
Animate the step 2 lavender farmhouse image as the first frame into a calm 6-second shot: the lavender sways in a light breeze, the camera pushes slowly down the central row toward the stone farmhouse, the sun glow brightens, haze drifts, small birds cross the sky, and bees hover over the rows. Step 3 of the Provence Lavender Farmhouse workflow.
Start from the step 2 image "Stone Farmhouse at the End of Lavender Rows in Provence at Sunrise" as the exact first frame, and animate it into a calm 6-second cinematic shot. Keep the stone farmhouse with its terracotta roof and pale blue shutters in the right third, the tall cypress beside it, the lone oak tree on the left, the converging lavender rows and central path, the low sun at the far left, the horizon line, and the composition exactly as in the image. A gentle breeze makes the lavender rows sway softly, all in the same direction. The camera makes a very slow, steady push-in along the central row toward the farmhouse. The sun's golden glow slowly brightens and thin morning haze drifts across the hills on the left. A couple of small birds fly across the sky from right to left above the house, a few bees drift over the lavender in the foreground, and the small white clouds drift slightly. Natural, realistic motion, no cuts, no people, no new buildings or objects, no text. Soft sound of a light breeze, distant birdsong, and buzzing bees.Explains every line of a .gitignore, tests it against paths that must be ignored or must stay committable, names the rule that decides each path, and flags mistakes such as negations blocked by an excluded parent folder, inline comments, leading spaces, backslashes, stray **, secrets not covered and .env.example ignored. Returns a fixed file. Includes a stdlib Python checker with --self-test, matched against real git.
---
name: gitignore-pattern-tester-and-reviewer
description: Explains every line of a .gitignore, tests it against paths that must be ignored or must stay committable, names the rule that decides each path, and flags mistakes such as negations blocked by an excluded parent folder, inline comments, leading spaces, backslashes, stray **, secrets not covered and .env.example ignored. Returns a fixed file. Includes a stdlib Python checker with --self-test, matched against real git.
---

# Gitignore Pattern Tester and Reviewer

You help developers understand and fix `.gitignore` files. You explain what each pattern really matches, prove it with path tests, and find the mistakes that make git ignore source files or commit secrets and build output. You return a corrected file with tests that pass, not just advice.

## Files in this skill

- `scripts/gitignore_check.py` - explains each rule, runs "+ path" (must be ignored) and "- path" (must be kept) tests, names the deciding line for each path, and reports HIGH, MEDIUM, LOW and INFO findings (Python 3 standard library only)
- `references/gitignore-rules.md` - how git reads ignore files: sources and priority, line syntax, anchoring, wildcards, the parent-directory rule, tracked files and commands to confirm
- `references/common-pitfalls.md` - every finding code with its fix, pitfalls the script cannot see (broad names, tracked files, nested files, case sensitivity, lock files, .dockerignore differences) and good starting blocks
- `templates/gitignore-review.md` - the review to hand back
- `examples/webapp.gitignore` - a web app ignore file with six real bugs
- `examples/webapp-fixed.gitignore` - the corrected file (all tests pass)
- `examples/webapp-paths.txt` - 19 path tests used with both files

## Workflow

### 1. Collect the inputs
Ask for the `.gitignore` (and any nested ones), the stack, and the paths that matter: what must be ignored (build output, dependencies, logs, secrets) and what must stay committable (source folders with common names like `build/` or `lib/`, `.gitkeep` files, `.env.example`, lock files). If the user only asks "why is X ignored?" ask for the path and use `git check-ignore -v X` output if they have it.

### 2. Run the checker
```
python3 scripts/gitignore_check.py examples/webapp.gitignore --test examples/webapp-paths.txt
python3 scripts/gitignore_check.py .gitignore --test paths.txt --json
python3 scripts/gitignore_check.py --self-test
```
Paths file: `+ path` must be ignored, `- path` must be kept, end directories with `/`. Exit 1 means a HIGH finding or a failed test, 2 means unreadable input. The checker models one ignore file at the repo root; for a nested file, give paths relative to its folder.

### 3. Explain and fix
- Walk through the Rules table in plain words, especially anchoring (slash at start or middle = relative to the .gitignore folder) and the parent-directory rule (see `references/gitignore-rules.md`).
- For each FAIL, quote the deciding line from the "Decided by" column and give the smallest change that fixes it.
- Fix every HIGH and MEDIUM finding; explain any INFO you leave in place.
- Add `- path` tests for source folders with common names so over-broad rules show up.
- Re-run the checker on the fixed file until all tests pass, and show the diff.

### 4. Deliver
Fill `templates/gitignore-review.md`: what the current file does, the test table, findings, the full fixed file, a diff, and the commands to confirm (`git check-ignore -v`, `git status --ignored`) and to untrack files that were already committed (`git rm --cached`).

## Example result
For `examples/webapp.gitignore` with `examples/webapp-paths.txt`: 13/19 tests pass, 1 HIGH, 4 MEDIUM, 2 LOW, 1 INFO. HIGH NEGATION_BLOCKED: `logs/` excludes the folder, so `!logs/.gitkeep` can never apply (fix: `logs/*`). MEDIUM: `config/secrets.yml # never commit` is one pattern, so the secrets file would be committed; ` Thumbs.db` has a leading space; `src\generated` is read as `srcgenerated`; and `*.key`, `*.pem` and `id_rsa` files are not covered. LOW: `.env*` hides `.env.example`; `*.log` is listed twice. The unanchored `build` also hides `src/build/README.md` (fix: `/build/`). `examples/webapp-fixed.gitignore` passes 19/19 with no HIGH, MEDIUM or LOW findings.

## Rules

- Last matching line wins; a file inside an excluded folder can never be re-included. Say this whenever a `!` line is involved.
- Never suggest ignoring lock files (`package-lock.json`, `poetry.lock`, `go.sum`, app `Cargo.lock`) or shared config the team commits on purpose.
- If a secret was already committed, say that ignoring it is not enough: rotate it and consider rewriting history.
- Prefer anchored root patterns (`/dist/`, `/build/`) for output folders, and put personal editor and OS files in the global ignore file when the team agrees.
- Confirm on the real repository with `git check-ignore -v`: the script follows git's documented rules for one file, but nested files, `.git/info/exclude`, the global file and `core.ignorecase` can change the result.
FILE:references/gitignore-rules.md
# How git reads .gitignore

Source: the gitignore(5) manual (`git help gitignore`). The checker implements these rules and was compared with real git 2.47 on 6,956 path checks with no differences.

## Where rules come from (highest priority first)
1. Command-line `--exclude` options (rare; used by some tools).
2. `.gitignore` files: the one in the same folder as the path wins over the ones above it. Patterns are relative to the folder that holds that `.gitignore`.
3. `.git/info/exclude` - local to one clone, never committed. Good for personal scratch files.
4. The global file in `core.excludesFile` (default `~/.config/git/ignore`) - good for editor and OS files such as `.DS_Store` and `*.swp`.

Inside one file, the LAST matching line decides.

## Line syntax
| Line | Meaning |
|---|---|
| empty | ignored, use as a separator |
| `# text` | comment; only at the very start of a line. `foo # bar` is the pattern `foo # bar` |
| `\#file` | a name that starts with `#` |
| `!pattern` | re-include something an earlier line excluded |
| `\!file` | a name that starts with `!` |
| `name   ` | trailing spaces are dropped unless escaped (`name\ `) |
| `  name` | leading spaces are KEPT and become part of the name |
| `\` | escapes the next character; it is never a path separator |

## Slashes decide where a pattern matches
| Pattern | Matches | Does not match |
|---|---|---|
| `build` | `build`, `src/build`, `a/b/build/x.js` (any file or folder named build) | `build.sh` |
| `build/` | folders named build at any depth | a FILE named build |
| `/build` | `build` next to the .gitignore only | `src/build` |
| `doc/frotz` | `doc/frotz` next to the .gitignore (a slash in the middle anchors like a leading slash) | `a/doc/frotz` |
| `**/doc/frotz` | `doc/frotz` at any depth | |

Rule of thumb: no slash (or only a trailing one) = any depth; a slash at the start or middle = relative to the .gitignore folder.

## Wildcards
| Wildcard | Meaning |
|---|---|
| `*` | any characters except `/` (`*.log`, `/a*z` does not match `ab/cz`) |
| `?` | exactly one character except `/` |
| `[abc]`, `[a-z]`, `[!0-9]`, `[^0-9]` | one character from (or not from) the set; `[[:digit:]]` style classes work |
| `**/name` | `name` in any folder, including the top |
| `dir/**` | everything inside `dir`, but not `dir` itself |
| `a/**/b` | `a/b`, `a/x/b`, `a/x/y/b` |
| `foo**`, `**bar` | `**` not next to slashes acts like a single `*` |

## The parent-directory rule (the most common surprise)
"It is not possible to re-include a file if a parent directory of that file is excluded." Git does not even list the contents of an excluded folder, so a later `!` line never gets a chance.

```gitignore
# does NOT work: logs/ is excluded as a folder
logs/
!logs/.gitkeep

# works: exclude the folder's contents, keep the folder visible
logs/*
!logs/.gitkeep

# works for deeper files: re-include each folder level
/assets/*
!/assets/icons/
/assets/icons/*
!/assets/icons/app.svg
```

## Whitelist style
Ignore everything, then allow what you want:
```gitignore
*
!*/
!*.md
!src/**
```
`!*/` re-includes every folder so the later `!` lines can reach files inside them.

## Already tracked files
.gitignore only affects untracked files. A file that is already committed stays tracked:
```
git rm --cached path/to/file        # keep it on disk, stop tracking it
git rm -r --cached build/           # same for a folder
```
If it was a secret, removing it from tracking is not enough: rotate the secret, because it is still in history.

## Commands to confirm
```
git check-ignore -v path/to/file          # prints the file, line and pattern that ignores it (nothing = not ignored)
git check-ignore -v --no-index path       # also for files that are tracked
git status --ignored --short              # lists ignored files as "!!"
git ls-files --others --ignored --exclude-standard   # every ignored untracked file
```
FILE:references/common-pitfalls.md
# Common .gitignore pitfalls and the checker's codes

| Code | Severity | What goes wrong | Fix |
|---|---|---|---|
| NEGATION_BLOCKED | HIGH | `!path/file` after a rule that excludes a parent folder (`logs/`, `dist`, `a/*` for `a/b/c`) never takes effect, so the file you meant to commit stays ignored | Exclude contents (`logs/*` or `logs/**`) instead of the folder, or re-include each folder level (`!a/b/`) |
| SECRETS_NOT_COVERED | MEDIUM | typical secret files (`.env`, `*.pem`, `*.key`, `id_rsa`) would be committed by `git add .` | Add `.env`, `.env.*`, `*.pem`, `*.key`, `id_rsa*`; also use a secret scanner in CI |
| INLINE_COMMENT | MEDIUM | `secrets.yml # never commit` is one pattern including the comment text, so `secrets.yml` is NOT ignored | Put comments on their own line |
| LEADING_SPACE | MEDIUM | ` Thumbs.db` matches only a name that starts with a space | Remove the space |
| BACKSLASH_SEPARATOR | MEDIUM | `src\generated` means "src" + escaped "g" + "enerated" = `srcgenerated` | Always use `/`, also on Windows |
| ENV_EXAMPLE_IGNORED | LOW | `.env*` also hides `.env.example`, the template other developers need | Add `!.env.example` after it |
| DUPLICATE | LOW | the same line twice; harmless but a sign of copy-paste merges | Delete one |
| DOUBLE_STAR | LOW | `foo**` is just `foo*`; the author probably meant `foo/**` | Use `**` only as `**/x`, `x/**` or `a/**/b` |
| TRAILING_SPACE | LOW | trailing spaces are silently dropped; if they were meant, the file will not match | Remove or escape them |
| CRLF | LOW | Windows line endings in .gitignore | Save as LF; add `* text=auto` to .gitattributes |
| ANCHORED_BY_SLASH | INFO | `src/gen` only matches next to the .gitignore, not `packages/a/src/gen` | Add `/` to show intent or `**/` to match at any depth |

## Pitfalls the script cannot see (check them by hand)
- **Unanchored names that are too broad.** `build` also hides `src/build/` and `docs/build/`; `lib` hides every `lib` folder including source code. Use `/build/` for the root output folder. Write a `- path` test for any source folder with a common name.
- **Tracked files.** Adding a rule does not untrack files already committed. Run `git ls-files -ci --exclude-standard` to list tracked files that match the ignore rules, then `git rm --cached`.
- **Nested .gitignore files.** A `.gitignore` in a subfolder adds rules relative to that subfolder and can re-include what the root file excluded (unless a parent folder is excluded). Run the checker on each file with paths relative to its folder, or confirm with `git check-ignore -v`.
- **Case sensitivity.** On macOS and Windows `core.ignorecase=true` makes `*.JPG` match `photo.jpg`; on Linux CI it does not. Write both cases or use `*.[jJ][pP][gG]`.
- **Personal files in the shared file.** `.idea/`, `.vscode/`, `*.swp`, `.DS_Store` belong in the global ignore file (`core.excludesFile`), though many teams keep them in the repo file for convenience. Do not ignore `.vscode/settings.json` if the team shares it on purpose.
- **Lock files.** Do not ignore `package-lock.json`, `yarn.lock`, `pnpm-lock.yaml`, `poetry.lock`, `Cargo.lock` (for applications) or `go.sum`: they make builds reproducible.
- **Ignoring then committing anyway.** `git add -f` overrides ignore rules; reviewers should check for force-added build output or secrets.
- **Other ignore files use different rules.** `.dockerignore` uses Go filepath.Match plus `**` and is always anchored at the build context root (no "any depth" for plain names). `.npmignore`, `.eslintignore` and `.prettierignore` follow gitignore-like rules but not always every detail. Test them with their own tools.

## Good starting blocks
```gitignore
# Node
node_modules/
/dist/
/build/
npm-debug.log*
.npm/

# Python
__pycache__/
*.py[cod]
.venv/
.pytest_cache/
/dist/
*.egg-info/

# Secrets
.env
.env.*
!.env.example
*.pem
*.key
id_rsa*

# Logs that keep their folder
logs/*
!logs/.gitkeep
```
FILE:templates/gitignore-review.md
# .gitignore review: <repository or folder>

**Stack:** <Node 20 + Vite / Python 3.12 / monorepo with pnpm workspaces>
**Files reviewed:** <.gitignore at root, packages/api/.gitignore>
**Summary:** <one sentence: the most important problem and what the fix changes>

## What the current file does
| Line | Pattern | Meaning |
|---|---|---|
| <9> | <`logs/`> | <ignores every folder named logs, at any depth, and everything in it> |

## Path tests
| Result | Path | Expected | Actual | Decided by |
|---|---|---|---|---|
| <FAIL> | <`logs/.gitkeep`> | <kept> | <ignored> | <parent logs/ excluded by L9; L10 cannot re-include it> |

## Findings
| # | Severity | Code | Line | Problem | Fix |
|---|---|---|---|---|---|
| 1 | <HIGH> | <NEGATION_BLOCKED> | <10> | <...> | <use logs/* instead of logs/> |

## Proposed .gitignore
```gitignore
<full fixed file, with comments on their own lines>
```

## Changes
```diff
- logs/
+ logs/*
```

## Apply and confirm
1. Replace the file, then run: `git check-ignore -v <each path from the tests>`
2. `git status --ignored --short` and check nothing important shows as `!!`
3. Untrack files that are now ignored but were committed: `git rm --cached <path>` (rotate any secret that was committed)
4. Commit: `chore: fix .gitignore (<short reason>)`

## Follow-ups
- <move editor files to the global ignore file>
- <add a secret scanner (gitleaks, trufflehog) to CI>
FILE:examples/webapp.gitignore
# Dependencies
node_modules
/vendor/

# Build output
dist/
build
*.log
logs/
!logs/.gitkeep

# Environment
.env*
config/secrets.yml # never commit

# OS and editor files
.DS_Store
.idea/
*.swp
 Thumbs.db

# Test coverage
coverage/**
!coverage/README.md

# Generated code
src\generated
*.log
FILE:examples/webapp-fixed.gitignore
# Dependencies
node_modules/
/vendor/

# Build output (root only, so src/build/ stays tracked)
/dist/
/build/
*.log
# ignore the contents of logs/, not the folder, so the negation can work
logs/*
!logs/.gitkeep

# Environment and secrets
.env
.env.*
!.env.example
*.pem
*.key
id_rsa*
# never commit
config/secrets.yml

# OS and editor files
.DS_Store
Thumbs.db
.idea/
*.swp

# Test coverage
coverage/**
!coverage/README.md

# Generated code
/src/generated/
FILE:examples/webapp-paths.txt
# Paths for examples/webapp.gitignore and webapp-fixed.gitignore
# "+ path" = must be ignored, "- path" = must stay committable
+ node_modules/react/index.js
+ packages/api/node_modules/lodash/lodash.js
+ vendor/autoload.php
- packages/vendor/README.md
+ dist/app.js
+ build/output.js
- src/build/README.md
+ logs/app.log
- logs/.gitkeep
+ .env
+ .env.local
- .env.example
+ config/secrets.yml
+ .DS_Store
+ Thumbs.db
+ coverage/lcov.info
- coverage/README.md
+ src/generated/types.ts
- src/index.ts
FILE:scripts/gitignore_check.py
#!/usr/bin/env python3
"""Gitignore pattern tester and reviewer (Python 3 standard library only).

Explains every rule in a .gitignore file, tests the file against paths that must be
ignored ("+ path") or must stay committable ("- path"), names the rule that decides
each path, and flags common mistakes: negations that cannot work because a parent
directory is excluded, inline comments, leading spaces, Windows backslashes, stray
"**", duplicates, secrets that are not covered and .env.example being ignored.

Matching follows git's documented gitignore rules for a single .gitignore at the
repository root: last matching rule wins, "!" re-includes, a trailing "/" matches
directories only, a "/" at the start or in the middle anchors the pattern to the
.gitignore's directory, "*" "?" "[...]" never match "/", "**" spans directories,
and a file can never be re-included if a parent directory is excluded.

Usage:
  python3 gitignore_check.py .gitignore [--test paths.txt] [--json]
  python3 gitignore_check.py --self-test
Paths file: one path per line, "+ path" = must be ignored, "- path" = must NOT be
ignored, end a path with "/" if it is a directory, "#" starts a comment.
Exit codes: 0 = no HIGH findings and all tests pass, 1 = HIGH finding or failed test,
2 = unreadable input.
"""
import argparse, json, re, sys

SEV_ORDER = {"HIGH": 0, "MEDIUM": 1, "LOW": 2, "INFO": 3}
SECRET_PROBES = [".env", "config/.env.production", "certs/server.key", "deploy/id_rsa",
                 "secrets/service-account.pem"]
POSIX_CLASSES = {"alnum": "a-zA-Z0-9", "alpha": "a-zA-Z", "digit": "0-9", "lower": "a-z",
                 "upper": "A-Z", "space": " \\t\\n\\r\\f\\v", "xdigit": "0-9A-Fa-f",
                 "punct": re.escape("!\"#$%&'()*+,-./:;<=>?@[\\]^_`{|}~"), "blank": " \\t"}


class Rule:
    def __init__(self, line_no, raw, negate, dir_only, anchored, body, regex):
        self.line_no, self.raw, self.negate, self.dir_only = line_no, raw, negate, dir_only
        self.anchored, self.body, self.regex = anchored, body, regex

    def matches(self, rel_path, is_dir):
        if self.dir_only and not is_dir:
            return False
        target = rel_path if self.anchored else rel_path.rsplit("/", 1)[-1]
        return self.regex.fullmatch(target) is not None

    def label(self):
        return f"L{self.line_no} `{self.raw}`"


def strip_trailing_spaces(s):
    """git drops trailing spaces unless the last one is escaped with a backslash."""
    end = len(s)
    while end > 0 and s[end - 1] == " ":
        bs, k = 0, end - 2
        while k >= 0 and s[k] == "\\":
            bs += 1; k -= 1
        if bs % 2 == 1:
            break
        end -= 1
    return s[:end]


def class_to_regex(body):
    out, m = "", 0
    while m < len(body):
        ch = body[m]
        if ch == "[" and body.startswith("[:", m):
            end = body.find(":]", m + 2)
            if end != -1 and body[m + 2:end] in POSIX_CLASSES:
                out += POSIX_CLASSES[body[m + 2:end]]; m = end + 2; continue
        if ch == "\\" and m + 1 < len(body):
            out += re.escape(body[m + 1]); m += 2; continue
        if ch == "-" and 0 < m < len(body) - 1:
            out += "-"; m += 1; continue
        out += re.escape(ch); m += 1
    return out


def glob_to_regex(p):
    out, i, n = "", 0, len(p)
    while i < n:
        c = p[i]
        if c == "\\":
            if i + 1 < n:
                out += re.escape(p[i + 1]); i += 2
            else:
                i += 1  # a lone trailing backslash matches nothing extra
            continue
        if c == "*":
            j = i
            while j < n and p[j] == "*":
                j += 1
            if j - i >= 2 and (i == 0 or p[i - 1] == "/") and (j == n or p[j] == "/"):
                if j == n:
                    out += ".*"; i = j
                else:
                    out += "(?:.*/)?"; i = j + 1
                continue
            out += "[^/]*"; i = j; continue
        if c == "?":
            out += "[^/]"; i += 1; continue
        if c == "[":
            j = i + 1
            neg = j < n and p[j] in "!^"
            if neg:
                j += 1
            k = j + 1 if j < n and p[j] == "]" else j
            while k < n and p[k] != "]":
                if p[k] == "[" and p.startswith("[:", k):
                    end = p.find(":]", k + 2)
                    if end != -1:
                        k = end + 2; continue
                k += 2 if p[k] == "\\" else 1
            if k >= n:
                out += re.escape("["); i += 1; continue
            cls = class_to_regex(p[j:k])
            out += ("[^/" + cls + "]") if neg else ("(?!/)[" + cls + "]")
            i = k + 1; continue
        out += re.escape(c); i += 1
    return out


def parse_rules(text):
    rules, findings, seen = [], [], {}
    for no, raw in enumerate(text.split("\n"), 1):
        if raw.endswith("\r"):
            findings.append(("LOW", "CRLF", no, "line ends with CR (Windows line ending)",
                             "Save the file with LF line endings; set `* text=auto` in .gitattributes."))
            raw = raw[:-1]
        if not raw.strip() or raw.startswith("#"):
            continue
        line = strip_trailing_spaces(raw)
        if line != raw:
            findings.append(("LOW", "TRAILING_SPACE", no, f"`{raw}` has trailing spaces, which git drops",
                             "Delete them; escape a real trailing space as `\\ `."))
        if raw[0] in " \t":
            findings.append(("MEDIUM", "LEADING_SPACE", no, f"`{raw}` starts with whitespace, which git keeps as part of the name, so it matches nothing useful",
                             "Remove the leading whitespace."))
        m = re.search(r"\s#", line)
        if m:
            findings.append(("MEDIUM", "INLINE_COMMENT", no, f"`{line}`: git has no inline comments, so `{line[m.start():].strip()}` becomes part of the pattern",
                             "Move the comment to its own line starting with #."))
        if re.search(r"\\[A-Za-z0-9_]", line):
            findings.append(("MEDIUM", "BACKSLASH_SEPARATOR", no, f"`{line}` uses a backslash, which escapes the next character instead of separating directories",
                             "Use forward slashes: `" + line.replace("\\", "/") + "`."))
        key = line.strip()
        if key in seen:
            findings.append(("LOW", "DUPLICATE", no, f"`{key}` repeats line {seen[key]}", "Delete the duplicate."))
        else:
            seen[key] = no
        negate = line.startswith("!")
        body = line[1:] if negate else line
        if body.startswith("\\!") or body.startswith("\\#"):
            body = body[1:]
        if negate and not body:
            findings.append(("LOW", "EMPTY_NEGATION", no, "`!` alone does nothing", "Delete the line."))
            continue
        dir_only = body.endswith("/") and not body.endswith("\\/")
        if dir_only:
            body = body.rstrip("/")
        if not body:
            continue
        anchored = "/" in body
        if body.startswith("/"):
            body = body[1:]
        if any((m.start() > 0 and body[m.start() - 1] != "/") or (m.end() < len(body) and body[m.end()] != "/")
               for m in re.finditer(r"\*{2,}", body)):
            findings.append(("LOW", "DOUBLE_STAR", no, f"`{line}`: `**` not between slashes acts like a single `*`",
                             "Use `**/name`, `dir/**` or `a/**/b`, or a single `*`."))
        rules.append(Rule(no, line, negate, dir_only, anchored, body, re.compile(glob_to_regex(body), re.S)))
    return rules, findings


def last_match(rules, rel_path, is_dir):
    hit = None
    for r in rules:
        if r.matches(rel_path, is_dir):
            hit = r
    return hit


def check_path(rules, path):
    """Return (ignored, reason, blocked_rule) following git's parent-directory rule."""
    is_dir = path.endswith("/")
    parts = [p for p in path.strip("/").split("/") if p]
    for k in range(1, len(parts) + 1):
        sub = "/".join(parts[:k])
        sub_is_dir = k < len(parts) or is_dir
        hit = last_match(rules, sub, sub_is_dir)
        if k < len(parts):
            if hit and not hit.negate:
                own = last_match(rules, "/".join(parts), is_dir)
                blocked = own if own and own.negate else None
                return True, f"parent `{sub}/` excluded by {hit.label()}", blocked
        else:
            if hit is None:
                return False, "no rule matches", None
            if hit.negate:
                return False, f"re-included by {hit.label()}", None
            return True, f"ignored by {hit.label()}", None
    return False, "empty path", None


def literal_dirs(body):
    parts = body.split("/")[:-1]
    out = []
    for p in parts:
        if any(ch in p for ch in "*?[\\"):
            break
        out.append(p)
    return out


def lint_negations(rules):
    findings = []
    for idx, r in enumerate(rules):
        if not r.negate or not r.anchored:
            continue
        before = rules[:idx]
        dirs = literal_dirs(r.body)
        for k in range(1, len(dirs) + 1):
            sub = "/".join(dirs[:k])
            hit = last_match(before, sub, True)
            if hit and not hit.negate:
                findings.append(("HIGH", "NEGATION_BLOCKED", r.line_no,
                                 f"`{r.raw.strip()}` can never apply: its parent directory `{sub}/` is excluded by {hit.label()} and git does not look inside excluded directories",
                                 f"Exclude the contents instead of the directory (`{sub}/*` or `{sub}/**`), then keep the `!` rule; or re-include `!{sub}/` first."))
                break
    return findings


def lint_secrets(rules):
    findings = []
    missing = [p for p in SECRET_PROBES if not check_path(rules, p)[0]]
    if missing:
        findings.append(("MEDIUM", "SECRETS_NOT_COVERED", 0, "these typical secret files would NOT be ignored: " + ", ".join(missing),
                         "Add `.env`, `.env.*` (with `!.env.example`), `*.pem`, `*.key`, `id_rsa*` if the project could ever contain them."))
    if check_path(rules, ".env.example")[0]:
        findings.append(("LOW", "ENV_EXAMPLE_IGNORED", 0, "`.env.example` is ignored, so the documented template cannot be committed",
                         "Add `!.env.example` after the .env rule."))
    return findings


def explain(rule):
    body = rule.body
    kind = "directories" if rule.dir_only else "files or directories"
    verb = "Re-includes" if rule.negate else "Ignores"
    wild = any(ch in body for ch in "*?[")
    if rule.anchored and body.endswith("/**") and "*" not in body[:-3]:
        text = f"{verb} everything inside `{body[:-3]}/` (but not the folder itself), relative to the .gitignore folder"
    elif rule.anchored and body.startswith("**/") and "/" not in body[3:]:
        text = f"{verb} {kind} {'matching' if wild else 'named'} `{body[3:]}` at any depth"
    elif rule.anchored:
        text = f"{verb} {kind} {'matching' if wild else 'at'} `{body}` relative to the .gitignore folder only"
    else:
        text = f"{verb} {kind} {'matching' if wild else 'named'} `{body}` at any depth"
    if not rule.negate and not body.endswith("/**"):
        text += "; a matched directory hides everything inside it"
    if rule.negate:
        text += " (only works if no parent directory is excluded)"
    return text + "."


def read_tests(text):
    tests = []
    for no, line in enumerate(text.splitlines(), 1):
        s = line.strip()
        if not s or s.startswith("#"):
            continue
        if s[0] not in "+-" or len(s) < 3:
            raise ValueError(f"paths file line {no}: expected '+ path' or '- path', got {line!r}")
        tests.append((s[0] == "+", s[1:].strip()))
    return tests


def review(gi_text, tests_text=None):
    rules, findings = parse_rules(gi_text)
    findings += lint_negations(rules)
    findings += lint_secrets(rules)
    anchored = [r.line_no for r in rules if r.anchored and not r.negate and "/" in r.body
                and not r.raw.startswith(("/", "**/")) and not r.body.endswith("/**")]
    if anchored:
        findings.append(("INFO", "ANCHORED_BY_SLASH", anchored[0],
                         "lines " + ", ".join(map(str, anchored)) + " contain a slash, so they only match relative to the .gitignore folder, not deeper copies",
                         "Fine if intended; add a leading `/` to make that explicit, or prefix `**/` to match at any depth."))
    results = []
    if tests_text:
        for want, path in read_tests(tests_text):
            got, reason, blocked = check_path(rules, path)
            note = reason
            if blocked:
                note += f"; {blocked.label()} cannot re-include it"
            results.append({"path": path, "expect": "ignored" if want else "kept",
                            "actual": "ignored" if got else "kept", "pass": got == want, "why": note})
    findings.sort(key=lambda f: (SEV_ORDER[f[0]], f[2]))
    return {"rules": [{"line": r.line_no, "pattern": r.raw, "meaning": explain(r)} for r in rules],
            "findings": [dict(zip(("severity", "code", "line", "problem", "fix"), f)) for f in findings],
            "tests": results}


def render(name, rep):
    out = [f"# .gitignore review: {name}", ""]
    counts = {s: sum(1 for f in rep["findings"] if f["severity"] == s) for s in SEV_ORDER}
    failed = sum(1 for t in rep["tests"] if not t["pass"])
    out.append(f"Findings: {counts['HIGH']} HIGH, {counts['MEDIUM']} MEDIUM, {counts['LOW']} LOW, {counts['INFO']} INFO")
    if rep["tests"]:
        out.append(f"Tests: {len(rep['tests']) - failed}/{len(rep['tests'])} passed")
    out += ["", "## Rules", "", "| Line | Pattern | Meaning |", "|---|---|---|"]
    for r in rep["rules"]:
        out.append(f"| {r['line']} | `{r['pattern']}` | {r['meaning']} |")
    if rep["tests"]:
        out += ["", "## Path tests", "", "| Result | Path | Expected | Actual | Decided by |", "|---|---|---|---|---|"]
        for t in rep["tests"]:
            out.append(f"| {'PASS' if t['pass'] else 'FAIL'} | `{t['path']}` | {t['expect']} | {t['actual']} | {t['why']} |")
    out += ["", "## Findings", ""]
    if rep["findings"]:
        out += ["| Severity | Code | Line | Problem | Fix |", "|---|---|---|---|---|"]
        for f in rep["findings"]:
            out.append(f"| {f['severity']} | {f['code']} | {f['line'] or '-'} | {f['problem']} | {f['fix']} |")
    else:
        out.append("No findings.")
    out += ["", "Confirm on the real repo with `git check-ignore -v <path>` and `git status --ignored`; files that are already tracked stay tracked until `git rm --cached <path>`."]
    return "\n".join(out)


def self_test():
    cases = []
    def t(name, cond):
        cases.append((name, bool(cond)))
    R = lambda s: parse_rules(s)[0]
    ign = lambda s, p: check_path(R(s), p)[0]
    t("*.log matches at any depth", ign("*.log", "a/b/c.log") and ign("*.log", "x.log"))
    t("* does not cross /", not ign("/a*z", "ab/cz") and ign("/a*z", "abcz"))
    t("name without slash matches basename anywhere", ign("build", "src/build/x.js"))
    t("leading slash anchors", ign("/vendor", "vendor/a") and not ign("/vendor", "lib/vendor/a"))
    t("middle slash anchors", ign("doc/frotz", "doc/frotz") and not ign("doc/frotz", "a/doc/frotz"))
    t("trailing slash = directory only", ign("logs/", "logs/x") and not ign("logs/", "logs"))
    t("dir-only rule ignores a dir path", ign("logs/", "logs/"))
    t("**/ prefix matches any depth", ign("**/foo", "foo") and ign("**/foo", "a/b/foo"))
    t("**/foo/bar", ign("**/foo/bar", "x/foo/bar") and not ign("**/foo/bar", "x/foo/baz"))
    t("trailing /** matches contents only", ign("abc/**", "abc/x/y") and not ign("abc/**", "abc"))
    t("a/**/b zero or more dirs", ign("a/**/b", "a/b") and ign("a/**/b", "a/x/y/b") and not ign("a/**/b", "ab"))
    t("? matches one char not /", ign("/a?c", "abc") and not ign("/a?c", "a/c"))
    t("[abc] class", ign("file[12].txt", "file1.txt") and not ign("file[12].txt", "file3.txt"))
    t("[!x] negated class", ign("f[!0-9]", "fa") and not ign("f[!0-9]", "f5"))
    t("[[:digit:]] posix class", ign("v[[:digit:]]", "v7") and not ign("v[[:digit:]]", "vx"))
    t("last match wins with negation", not ign("*.txt\n!keep.txt", "keep.txt") and ign("*.txt\n!keep.txt", "a.txt"))
    t("order matters", ign("!keep.txt\n*.txt", "keep.txt"))
    t("parent dir excluded blocks negation", ign("logs/\n!logs/.gitkeep", "logs/.gitkeep"))
    t("dir/* allows negation", not ign("logs/*\n!logs/.gitkeep", "logs/.gitkeep"))
    t("dir/** allows negation", not ign("coverage/**\n!coverage/README.md", "coverage/README.md"))
    t("re-include dir then file", not ign("/a/*\n!/a/b/\n/a/b/*\n!/a/b/c", "a/b/c"))
    t("escaped # and !", ign("\\#notes", "#notes") and ign("\\!bang", "!bang"))
    t("comment lines skipped", not ign("# *.log", "a.log"))
    t("trailing spaces stripped", ign("foo   ", "foo"))
    t("escaped trailing space kept", ign("foo\\ ", "foo ") and not ign("foo\\ ", "foo"))
    t("leading space kept as part of name", not ign(" Thumbs.db", "Thumbs.db"))
    t("inline comment becomes pattern", not ign("secrets.yml # x", "secrets.yml"))
    t("backslash escapes, not a separator", not ign("src\\gen", "src/gen/a.ts"))
    def codes(s):
        return {f[1] for f in parse_rules(s)[1]} | {f[1] for f in lint_negations(parse_rules(s)[0])} | {f[1] for f in lint_secrets(parse_rules(s)[0])}
    t("NEGATION_BLOCKED found", "NEGATION_BLOCKED" in codes("logs/\n!logs/.gitkeep"))
    t("NEGATION_BLOCKED not for dir/*", "NEGATION_BLOCKED" not in codes("logs/*\n!logs/.gitkeep"))
    t("NEGATION_BLOCKED via dir/* deeper", "NEGATION_BLOCKED" in codes("a/*\n!a/b/c.txt"))
    t("INLINE_COMMENT found", "INLINE_COMMENT" in codes("x.yml # c"))
    t("LEADING_SPACE found", "LEADING_SPACE" in codes(" x"))
    t("BACKSLASH_SEPARATOR found", "BACKSLASH_SEPARATOR" in codes("a\\b"))
    t("DUPLICATE found", "DUPLICATE" in codes("*.log\n*.log"))
    t("DOUBLE_STAR found", "DOUBLE_STAR" in codes("foo**") and "DOUBLE_STAR" not in codes("**/foo\nfoo/**"))
    t("CRLF found", "CRLF" in codes("a\r\nb"))
    t("SECRETS_NOT_COVERED found", "SECRETS_NOT_COVERED" in codes("*.log"))
    t("secrets covered", "SECRETS_NOT_COVERED" not in codes(".env\n.env.*\n!.env.example\n*.key\n*.pem\nid_rsa*"))
    t("ENV_EXAMPLE_IGNORED found", "ENV_EXAMPLE_IGNORED" in codes(".env*"))
    acodes = lambda s: {f["code"] for f in review(s)["findings"]}
    t("ANCHORED_BY_SLASH info", "ANCHORED_BY_SLASH" in acodes("src/gen") and "ANCHORED_BY_SLASH" not in acodes("/src/gen\nlogs/**\n**/x/y"))
    rep = review("logs/\n!logs/.gitkeep\n", "+ logs/a.log\n- logs/.gitkeep\n")
    t("test table marks blocked negation FAIL", rep["tests"][0]["pass"] and not rep["tests"][1]["pass"] and "cannot re-include" in rep["tests"][1]["why"])
    try:
        read_tests("? bad")
        t("bad paths line rejected", False)
    except ValueError:
        t("bad paths line rejected", True)
    t("findings sorted HIGH first", review("x # c\nlogs/\n!logs/a\n")["findings"][0]["severity"] == "HIGH")
    passed = sum(ok for _, ok in cases)
    for name, ok in cases:
        print(("PASS " if ok else "FAIL ") + name)
    print(f"{passed}/{len(cases)} passed")
    return 0 if passed == len(cases) else 1


def main():
    ap = argparse.ArgumentParser(description=__doc__, formatter_class=argparse.RawDescriptionHelpFormatter)
    ap.add_argument("gitignore", nargs="?")
    ap.add_argument("--test", help="paths file with '+ path' (must be ignored) and '- path' (must be kept)")
    ap.add_argument("--json", action="store_true")
    ap.add_argument("--self-test", action="store_true")
    a = ap.parse_args()
    if a.self_test:
        return self_test()
    if not a.gitignore:
        ap.print_usage(sys.stderr); return 2
    try:
        gi = open(a.gitignore, encoding="utf-8", newline="").read()
        tests = open(a.test, encoding="utf-8").read() if a.test else None
        rep = review(gi, tests)
    except (OSError, UnicodeDecodeError, ValueError) as e:
        print(f"error: {e}", file=sys.stderr); return 2
    print(json.dumps(rep, indent=2) if a.json else render(a.gitignore, rep))
    bad = any(f["severity"] == "HIGH" for f in rep["findings"]) or any(not t["pass"] for t in rep["tests"])
    return 1 if bad else 0


if __name__ == "__main__":
sys.exit(main())Scales a recipe by servings, a factor, or pan size (square, rectangle, round, loaf), converts between US cups and spoons, metric volume and grams with an ingredient density table, rounds to measurable amounts, and flags baking caveats such as fractional eggs, leavening at large factors, batter depth and bake time when the pan changes, tiny amounts, seasoning and cooking time. Includes a stdlib Python scaler with --self-test.
---
name: recipe-scaling-and-unit-converter
description: Scales a recipe by servings, a factor, or pan size (square, rectangle, round, loaf), converts between US cups and spoons, metric volume and grams with an ingredient density table, rounds to measurable amounts, and flags baking caveats such as fractional eggs, leavening at large factors, batter depth and bake time when the pan changes, tiny amounts, seasoning and cooking time. Includes a stdlib Python scaler with --self-test.
---

# Recipe Scaling and Unit Converter

You help home cooks and bakers make a recipe bigger, smaller or fit a different pan, in the units they actually use. You give amounts they can measure, show the factor and the conversions behind them, and warn about the things that do not scale in a straight line: eggs, leavening, pan depth, bake time, seasoning and cooking time.

## Files in this skill

- `scripts/scale_recipe.py` - reads an ingredients CSV, scales by servings, factor or pan area, converts to US, metric or grams, rounds to kitchen measures and lists caveats (Python 3 standard library only)
- `references/conversions-and-densities.md` - US/metric volume and weight, grams per cup for about 30 common ingredients, egg sizes, oven temperatures with fan and gas mark, and pan areas
- `references/baking-scaling-caveats.md` - what scales linearly, eggs, leavening, pan size and bake time, cooking (non-baking) caveats and rounding rules
- `templates/scaled-recipe.md` - the scaled recipe to hand back
- `examples/fudgy-brownies-8x8.csv` - brownies for an 8x8 pan (16 pieces), used in the example

## Workflow

### 1. Get the recipe and the goal
Ask for the ingredient list with amounts and units, the original yield or pan, and the target: servings, a factor, or a different pan. Ask whether it is baking, which units they want (cups, grams, or as written), and where the recipe is from if cup, tablespoon or egg sizes could differ (US, UK, Australia). Put the ingredients in a CSV with columns `quantity,unit,ingredient,note`.

### 2. Run the scaler
```
python3 scripts/scale_recipe.py examples/fudgy-brownies-8x8.csv --from-pan 8x8 --to-pan 9x13 --to weight --baking --oven 350F --time 20-25
python3 scripts/scale_recipe.py stew.csv --servings 4 10 --to metric
python3 scripts/scale_recipe.py cake.csv --factor 2 --from-pan round8 --to-pan round9 --baking
python3 scripts/scale_recipe.py --self-test
```
Pans: `8x8`, `9x13`, `20x30cm`, `round9`, `round23cm`, `loaf9x5`. With only pans, the factor is the area ratio. With a factor or servings plus pans, the script checks how the batter depth changes. Exit 1 means a HIGH caveat (batter depth changes by more than 1.5x), 2 means bad input.

### 3. Check and adjust
- Read every caveat and turn it into a concrete instruction (see `references/baking-scaling-caveats.md`): weigh the partial egg, bake in batches, change the pan, lower the oven, taste before adding all the salt.
- For ingredients without a density (NO_DENSITY), keep the volume or look the weight up; never guess for salt brands or leavening.
- Sanity-check the result: does the pan hold it (2/3 full for cakes)? Did rounding move a key ingredient by more than 5 %? If yes, give grams.

### 4. Deliver
Fill `templates/scaled-recipe.md`: factor, yield, pan, oven in °F and °C (fan), ingredients in the cook's units with the alternative in brackets, method changes, caveats and a doneness test instead of a fixed time.

## Example result
`examples/fudgy-brownies-8x8.csv` moved from an 8x8 to a 9x13 pan: factor x1.83 (64 to 117 sq in), same batter depth, so bake 350°F / 180°C (fan 160°C) and start checking at 20 minutes. In grams: butter 205 g, sugar 365 g, cocoa 52 g, flour 115 g, chocolate chips 235 g, salt 2.5 g, baking powder 2 g, vanilla 7.5 g. Eggs scale to 3.66 (MEDIUM EGG_FRACTION): use 3 eggs plus 33 g beaten egg. Doubling the recipe but baking it in a 9 in round pan (about the same area as 8x8) doubles the batter depth (HIGH DEPTH_CHANGE, exit 1).

## Rules

- Show the factor and how you got it (servings ratio or pan areas) before the amounts.
- Never multiply bake or cooking times by the factor; give a doneness test and an early check time.
- Keep salt and leavening ratios in baking; in cooking add about three quarters of scaled strong seasonings and taste.
- Prefer grams for baking and say that densities are averages; trust the author's grams when they exist.
- Ask before assuming US cups or egg sizes for recipes from other countries.
- Mention food safety for large batches (cool quickly in shallow containers) when scaling cooked dishes up a lot.
FILE:references/conversions-and-densities.md
# Conversions and densities

## Volume (US customary)
| Unit | ml | Also |
|---|---|---|
| 1 tsp | 4.93 | 1/3 tbsp |
| 1 tbsp | 14.79 | 3 tsp |
| 1 fl oz | 29.57 | 2 tbsp |
| 1 cup | 236.59 | 16 tbsp, 8 fl oz |
| 1 pint | 473.18 | 2 cups |
| 1 quart | 946.35 | 4 cups |

Other cups: metric cup (Australia, NZ, Canada recipes) = 250 ml; UK imperial pint = 568 ml; Australian tablespoon = 20 ml (4 tsp). Ask where a recipe is from when the cup or tablespoon size matters (baking, salt, leavening).

## Weight
| Unit | g |
|---|---|
| 1 oz | 28.35 |
| 1 lb | 453.6 (16 oz) |
| 1 stick butter (US) | 113 (1/2 cup, 8 tbsp) |

"oz" in a recipe is weight unless it says "fl oz". For water and milk 8 fl oz weighs about 8 oz; for flour it is about 4.4 oz.

## Grams per US cup (spoon-and-level, used by the script)
| Ingredient | g/cup | g/tbsp | g/tsp |
|---|---|---|---|
| All-purpose (plain) flour | 125 | 7.8 | 2.6 |
| Bread flour | 127 | 7.9 | |
| Cake flour | 114 | 7.1 | |
| Whole wheat flour | 113 | 7.1 | |
| Almond flour | 96 | 6 | |
| Cornstarch (cornflour) | 112 | 7 | |
| Granulated or caster sugar | 200 | 12.5 | 4.2 |
| Brown sugar, packed | 213 | 13.3 | |
| Powdered (icing) sugar | 120 | 7.5 | |
| Butter | 227 | 14.2 | |
| Water | 237 | 14.8 | 4.9 |
| Milk, buttermilk, sour cream | 242 | 15.1 | |
| Heavy cream | 238 | 14.9 | |
| Yogurt | 245 | 15.3 | |
| Vegetable or canola oil | 218 | 13.6 | |
| Olive oil | 216 | 13.5 | |
| Honey, golden syrup | 340 | 21 | 7 |
| Maple syrup | 322 | 20 | |
| Cocoa powder | 85 | 5.3 | |
| Rolled oats | 90 | | |
| Chocolate chips | 170 | | |
| Raw white rice | 185 | | |
| Chopped nuts / walnuts | 120 | | |
| Pecans | 110 | | |
| Raisins | 150 | | |
| Peanut butter | 270 | 17 | |
| Table (fine) salt | 288 | 18 | 6 |
| Baking soda | 230 | | 4.8 |
| Baking powder | 192 | | 4 |
| Instant or active dry yeast | 149 | | 3.1 |
| Vanilla extract | 202 | | 4.2 |
| Ground cinnamon | 125 | | 2.6 |

Notes:
- Flour scooped straight from the bag can weigh 140 to 150 g per cup. If a recipe author gives grams, trust the grams.
- Kosher salt depends on the brand: Diamond Crystal about 2.8 g/tsp, Morton about 5 g/tsp, table salt about 6 g/tsp. Swapping brands by volume can double the salt. The script leaves "kosher salt" in volume and says so.
- The table is a practical average; published tables differ by about 5 %. That is fine for cooking and most baking; for macarons, bread and candy, weigh.

## Eggs
| Size (US) | Out of shell |
|---|---|
| Large | 50 g (yolk 18 g, white 32 g), about 3 tbsp beaten |
| Medium | 44 g |
| Extra large | 56 g |
| Jumbo | 63 g |
UK/EU "large" (63 to 73 g in shell) is about 58 g out of the shell: a UK large is closer to a US extra large.

## Oven temperatures
| °F | °C | Fan °C | Gas mark |
|---|---|---|---|
| 300 | 150 | 130 | 2 |
| 325 | 160 | 140 | 3 |
| 350 | 180 | 160 | 4 |
| 375 | 190 | 170 | 5 |
| 400 | 200 | 180 | 6 |
| 425 | 220 | 200 | 7 |
| 450 | 230 | 210 | 8 |
Fan (convection) ovens: lower about 20 °C / 25 °F, or keep the temperature and check earlier.

## Pan areas
| Pan | Area (sq in) | Area (cm²) |
|---|---|---|
| 8x8 square | 64 | 413 |
| 9x9 square | 81 | 523 |
| 9x13 rectangle | 117 | 755 |
| 10x15 jelly roll | 150 | 968 |
| 8 in round | 50 | 324 |
| 9 in round | 64 | 410 |
| 10 in round | 79 | 507 |
| 9x5 loaf | 45 | 290 |
| 20 cm round | 49 | 314 |
| 23 cm round | 64 | 415 |
| 20x20 cm square | 62 | 400 |
Area of a round pan = 3.14 x radius². An 8x8 square and a 9 in round hold almost the same batter.
FILE:references/baking-scaling-caveats.md
# Scaling caveats

## What scales linearly
Flour, sugar, fat, liquids, chocolate, nuts, fruit and (by weight) eggs scale with the factor. In baking, salt and leavening also start at the linear amount: the chemistry depends on the ratio to flour, so keep the ratio.

## Eggs
- Fractions of an egg: beat the eggs, weigh, and use the needed grams (large egg = 50 g out of the shell). 3.66 eggs = 3 eggs + 33 g beaten egg (about 2 tbsp).
- If you round instead: more egg makes cakes and brownies firmer, cakier or richer; less egg makes them denser and more fragile. Round up for cakes, down for fudgy brownies and cookies when in doubt.
- Recipes written in another country may use a different egg size (see conversions).

## Leavening (baking powder, baking soda, yeast)
- Start linear and measure precisely; at small factors 1/8 tsp errors are large, so weigh on a 0.1 g scale.
- For factors above 2, mixing and oven heat do not scale: big batters are harder to mix evenly and the centre heats slowly. Make separate batches of the original size when you can.
- If the batter ends up deeper than the original (same pan, more batter), it rises more slowly in the centre. Do not "fix" this with more leavening; use a wider pan or lower the oven and bake longer.
- Bread: yeast scales linearly with flour; rising time depends on dough temperature, not quantity.

## Pan size and bake time
- Scaling by pan area keeps the batter depth the same, so the bake time stays about the same. Start checking 5 minutes early.
- Same recipe in a different pan: depth ratio = old area / new area. Deeper batter needs a longer bake at a lower temperature (about 25 °F / 15 °C lower); thinner batter bakes faster.
- Fill cake pans at most 2/3 full, brownie pans about halfway.
- Glass and dark metal pans bake faster at the edges: lower 25 °F / 15 °C.
- Cupcakes from a cake recipe: 18 to 22 minutes at the same temperature; a 9x13 cake recipe makes about 24 cupcakes.
- Never multiply the bake time by the factor. Use the doneness test from the recipe (toothpick with moist crumbs for brownies, clean for cake, 93 to 99 °C / 200 to 210 °F inside for bread).

## Cooking (not baking)
- Seasonings: add about three quarters of the scaled salt, chilli and strong spices, then taste. A bigger pot evaporates differently.
- Liquids in braises and soups: evaporation depends on the pot's surface, not the volume, so a doubled stew in a wider pot may need less extra liquid than 2x.
- Searing and frying: do it in batches; a crowded pan steams instead of browning.
- Time: a doubled pot takes longer to come to a boil and to cool, but simmering time is about the same once it is hot. Roasts depend on thickness, not weight: use a thermometer.
- Food safety: cool large batches quickly (split into shallow containers) and reheat to 74 °C / 165 °F.

## Rounding for real kitchens
- US measures: cups in 1/4 and 1/3 steps, then tbsp in halves, tsp down to 1/8. Below 1/8 tsp = a pinch.
- Metric: grams to 0.5 g below 10 g, 1 g below 100 g, 5 g below 1 kg.
- Keep the original unit system unless the cook asks; offer grams for baking.
- Check the result against the original ratios (for example flour to butter) after rounding; if rounding moved a key ingredient by more than 5 %, give the exact gram amount.
FILE:templates/scaled-recipe.md
# <Recipe name>, scaled <from 8x8 pan to 9x13 pan / from 4 to 10 servings>

**Factor:** x<1.83>   **Makes:** <24 brownies / 10 servings>   **Units:** <grams with US measures in brackets>
**Pan:** <9x13 in (23x33 cm), lined>   **Oven:** <350°F / 180°C (fan 160°C)>   **Bake:** <start checking at 20 min; usually 20-25>

## Ingredients
| Ingredient | Amount | US measure |
|---|---|---|
| <unsalted butter, melted> | <205 g> | <3/4 cup + 2 1/2 tbsp> |
| <large eggs> | <3 + 33 g beaten (about 2 tbsp)> | |

## Method changes from the original
- <Beat 4 eggs, weigh out 183 g, keep the rest for an egg wash>
- <Mix in a bigger bowl; fold flour in two additions>
- <Same bake time because the batter depth is the same; test at 20 min>

## Caveats
- <EGG_FRACTION: ...>
- <Kosher salt brand: ...>

## Doneness check
<Toothpick 2 cm from the centre comes out with moist crumbs, not wet batter.>
FILE:examples/fudgy-brownies-8x8.csv
quantity,unit,ingredient,note
1/2,cup,unsalted butter,melted
1,cup,granulated sugar,
2,each,large eggs,room temperature
1,tsp,vanilla extract,
1/3,cup,cocoa powder,unsweetened
1/2,cup,all-purpose flour,spoon and level
1/4,tsp,salt,
1/4,tsp,baking powder,
3/4,cup,chocolate chips,semisweet
FILE:scripts/scale_recipe.py
#!/usr/bin/env python3
"""Recipe scaling and unit converter (Python 3 standard library only).

Scales a recipe by servings, by a factor, or from one pan size to another, converts
between US volume, metric volume and weight (grams, using an ingredient density table),
rounds to amounts you can measure, and flags baking caveats: fractional eggs, leavening
at large factors, batter depth changes when the pan does not scale with the recipe,
tiny amounts, seasoning and cooking time.

Input CSV columns: quantity,unit,ingredient,note
  quantity: 2 | 1.5 | 3/4 | 1 1/2 | ½   unit: tsp tbsp cup fl oz pint quart ml l g kg oz lb stick
  each (or empty) for counted items such as eggs.
Usage:
  python3 scale_recipe.py recipe.csv --servings 4 10 [--to us|metric|weight|keep]
  python3 scale_recipe.py recipe.csv --from-pan 8x8 --to-pan 9x13 --baking --oven 350F --time 20-25
  python3 scale_recipe.py recipe.csv --factor 0.5 --to weight --json
  python3 scale_recipe.py --self-test
Pans: WxL (inches, add cm for centimetres: 20x30cm), round9 / round23cm, loaf9x5.
Exit codes: 0 = no HIGH findings, 1 = HIGH findings, 2 = bad input.
"""
import argparse, csv, io, json, math, re, sys

ML = {"tsp": 4.92892, "tbsp": 14.7868, "cup": 236.588, "fl oz": 29.5735, "pint": 473.176,
      "quart": 946.353, "ml": 1.0, "l": 1000.0}
G = {"g": 1.0, "kg": 1000.0, "oz": 28.3495, "lb": 453.592, "stick": 113.4}
UNIT_ALIASES = {"teaspoon": "tsp", "teaspoons": "tsp", "t": "tsp", "tablespoon": "tbsp", "tablespoons": "tbsp",
                "tbs": "tbsp", "tbl": "tbsp", "T": "tbsp", "cups": "cup", "c": "cup", "floz": "fl oz",
                "fl. oz": "fl oz", "fluid ounce": "fl oz", "fluid ounces": "fl oz", "pints": "pint", "pt": "pint",
                "quarts": "quart", "qt": "quart", "milliliter": "ml", "milliliters": "ml", "mL": "ml",
                "liter": "l", "liters": "l", "litre": "l", "litres": "l", "L": "l", "gram": "g", "grams": "g",
                "kilogram": "kg", "kilograms": "kg", "ounce": "oz", "ounces": "oz", "pound": "lb", "pounds": "lb",
                "lbs": "lb", "sticks": "stick", "": "each", "x": "each", "whole": "each", "pc": "each",
                "pcs": "each", "piece": "each", "pieces": "each", "clove": "each", "cloves": "each",
                "large": "each", "medium": "each", "small": "each", "pinch": "pinch", "pinches": "pinch",
                "dash": "pinch"}
# grams per US cup (spoon-and-level). Longest matching name wins.
DENSITY = {
    "all-purpose flour": 125, "plain flour": 125, "flour": 125, "bread flour": 127, "cake flour": 114,
    "whole wheat flour": 113, "almond flour": 96, "cornstarch": 112, "cornflour": 112,
    "granulated sugar": 200, "caster sugar": 200, "sugar": 200, "brown sugar": 213,
    "powdered sugar": 120, "icing sugar": 120, "confectioners sugar": 120,
    "butter": 227, "water": 237, "milk": 242, "buttermilk": 242, "heavy cream": 238, "cream": 238,
    "sour cream": 242, "yogurt": 245, "vegetable oil": 218, "canola oil": 218, "olive oil": 216, "oil": 218,
    "honey": 340, "maple syrup": 322, "golden syrup": 340, "cocoa powder": 85, "cocoa": 85,
    "rolled oats": 90, "oats": 90, "chocolate chips": 170, "rice": 185, "chopped nuts": 120,
    "walnuts": 120, "pecans": 110, "raisins": 150, "peanut butter": 270,
    "table salt": 288, "fine salt": 288, "salt": 288, "kosher salt": None,
    "baking soda": 230, "bicarbonate of soda": 230, "baking powder": 192, "instant yeast": 149,
    "active dry yeast": 149, "yeast": 149, "vanilla extract": 202, "vanilla": 202,
    "ground cinnamon": 125, "cinnamon": 125,
}
LEAVENERS = ("baking soda", "bicarbonate", "baking powder", "yeast", "cream of tartar")
SEASONINGS = ("salt", "pepper", "chili", "chilli", "cayenne", "pepper flakes", "garlic powder", "curry", "cumin", "paprika")
EGG_G = {"egg": 50.0, "yolk": 18.0, "white": 32.0}  # US large egg out of shell
UNICODE_FRAC = {"½": .5, "¼": .25, "¾": .75, "⅓": 1 / 3, "⅔": 2 / 3, "⅛": .125, "⅜": .375, "⅝": .625, "⅞": .875}
SEV_ORDER = {"HIGH": 0, "MEDIUM": 1, "LOW": 2, "INFO": 3}


def parse_qty(s):
    s = s.strip()
    for ch, v in UNICODE_FRAC.items():
        if ch in s:
            rest = s.replace(ch, "").strip()
            return (float(rest) if rest else 0.0) + v
    m = re.fullmatch(r"(\d+)\s+(\d+)/(\d+)", s)
    if m:
        return int(m[1]) + int(m[2]) / int(m[3])
    m = re.fullmatch(r"(\d+)/(\d+)", s)
    if m:
        return int(m[1]) / int(m[2])
    m = re.fullmatch(r"\d+(?:\.\d+)?|\.\d+", s)
    if m:
        return float(s)
    raise ValueError(f"cannot read quantity {s!r}")


def norm_unit(u):
    u = u.strip()
    if u in UNIT_ALIASES:
        return UNIT_ALIASES[u]
    low = u.lower().rstrip(".")
    if low in ML or low in G or low in ("each", "pinch"):
        return low
    if low in UNIT_ALIASES:
        return UNIT_ALIASES[low]
    raise ValueError(f"unknown unit {u!r}")


def density_for(name):
    low = name.lower()
    best = None
    for key in DENSITY:
        if re.search(r"\b" + re.escape(key) + r"\b", low) and (best is None or len(key) > len(best)):
            best = key
    return (best, DENSITY[best]) if best else (None, None)


def egg_kind(name):
    low = name.lower()
    if "yolk" in low:
        return "yolk"
    if "white" in low and "egg" in low:
        return "white"
    if re.search(r"\beggs?\b", low):
        return "egg"
    return None


def parse_pan(spec):
    s = spec.strip().lower().replace(" ", "").replace("inch", "").replace("in", "").replace('"', "")
    cm = s.endswith("cm")
    if cm:
        s = s[:-2]
    k = 1 / 2.54 if cm else 1.0
    m = re.fullmatch(r"(?:round)?(\d+(?:\.\d+)?)(?:round)?", s)
    if m and "round" in s:
        d = float(m[1]) * k
        return math.pi * (d / 2) ** 2, f"{spec} round ({d:.1f} in)"
    m = re.fullmatch(r"(?:loaf|square|rect)?(\d+(?:\.\d+)?)x(\d+(?:\.\d+)?)", s)
    if m:
        a, b = float(m[1]) * k, float(m[2]) * k
        return a * b, f"{spec} ({a:.1f} x {b:.1f} in)"
    raise ValueError(f"cannot read pan size {spec!r} (use 9x13, 20x30cm, round9, round23cm, loaf9x5)")


def frac_str(x, denoms=(2, 3, 4, 8)):
    whole = int(x)
    rest = x - whole
    best = (abs(rest), 0, 1)
    for d in denoms:
        n = round(rest * d)
        if 0 < n < d and abs(rest - n / d) < best[0] - 1e-9:
            best = (abs(rest - n / d), n, d)
    if abs(rest - 1) < best[0]:
        return str(whole + 1)
    _, n, d = best
    if n == 0:
        return str(whole)
    g = math.gcd(n, d)
    return (f"{whole} " if whole else "") + f"{n // g}/{d // g}"


def frac_val(s):
    return parse_qty(s)


def cup_word(x):
    return "cups" if x > 1 + 1e-9 else "cup"


def fmt_us_volume(ml):
    cups = ml / ML["cup"]
    if cups >= 0.25 - 1e-9:
        s = frac_str(cups, (2, 3, 4))
        err = abs(frac_val(s) - cups) * ML["cup"]
        if err >= ML["tbsp"] * 0.75:
            base = math.floor(cups * 4) / 4
            tb = (cups - base) * ML["cup"] / ML["tbsp"]
            bs = frac_str(base, (4,))
            return (f"{bs} {cup_word(base)} + " if base else "") + f"{frac_str(tb, (2,))} tbsp"
        return f"{s} {cup_word(frac_val(s))}"
    tbsp = ml / ML["tbsp"]
    if tbsp >= 1 - 1e-9:
        return f"{frac_str(tbsp, (2,))} tbsp"
    tsp = ml / ML["tsp"]
    if tsp < 1 / 16:
        return "pinch"
    return f"{frac_str(tsp, (2, 4, 8))} tsp"


def round_metric(x):
    if x < 10:
        return round(x * 2) / 2
    if x < 100:
        return round(x)
    if x < 1000:
        return round(x / 5) * 5
    return round(x / 10) * 10


def fmt_num(x):
    return f"{x:g}"


def fmt_metric(amount, unit):
    v = round_metric(amount)
    if v >= 2000:
        return f"{fmt_num(v / 1000)} {'kg' if unit == 'g' else 'l'}"
    return f"{fmt_num(v)} {unit}"


def fmt_us_weight(g):
    oz = g / G["oz"]
    if oz >= 16:
        lb = oz / 16
        return f"{frac_str(lb, (4,))} lb"
    return f"{frac_str(oz, (2, 4))} oz" if oz >= 1 else f"{fmt_num(round(oz, 2))} oz"


def convert(row, factor, target):
    """Return dict with scaled display and notes for one ingredient row."""
    qty, unit, name = row["qty"] * factor, row["unit"], row["ingredient"]
    key, dens = density_for(name)
    egg = egg_kind(name)
    out = {"ingredient": name, "original": row["original"], "scaled_qty": qty, "unit": unit, "notes": []}
    if unit == "each":
        if egg:
            g = qty * EGG_G[egg]
            out["display"] = f"{fmt_num(round(qty, 2))} ({fmt_metric(g, 'g')} beaten)"
        else:
            out["display"] = fmt_num(round(qty, 2))
        return out
    if unit == "pinch":
        out["display"] = f"{fmt_num(round(qty, 2))} pinch"
        return out
    if unit in ML:
        ml = qty * ML[unit]
        out["ml"] = ml
        if target == "weight":
            if dens:
                out["display"] = fmt_metric(ml / ML["cup"] * dens, "g")
                out["also"] = fmt_us_volume(ml)
            else:
                out["display"] = fmt_metric(ml, "ml")
                out["also"] = fmt_us_volume(ml)
                out["notes"].append("NO_DENSITY")
        elif target == "metric" or (target == "keep" and unit in ("ml", "l")):
            out["display"] = fmt_metric(ml, "ml")
            out["also"] = fmt_us_volume(ml)
        else:
            out["display"] = fmt_us_volume(ml)
            out["also"] = fmt_metric(ml, "ml") if not dens else fmt_metric(ml / ML["cup"] * dens, "g")
        return out
    g = qty * G[unit]
    out["g"] = g
    if target == "us" or (target == "keep" and unit in ("oz", "lb", "stick")):
        if unit == "stick" and target == "keep":
            out["display"] = f"{frac_str(qty, (2, 4))} stick ({fmt_metric(g, 'g')})"
        else:
            out["display"] = fmt_us_weight(g)
        out["also"] = fmt_metric(g, "g")
    else:
        out["display"] = fmt_metric(g, "g")
        if dens:
            out["also"] = fmt_us_volume(g / dens * ML["cup"])
    return out


def read_recipe(text):
    rows = []
    reader = csv.DictReader(io.StringIO(text.lstrip("\ufeff")))
    need = {"quantity", "unit", "ingredient"}
    if not reader.fieldnames or not need <= {f.strip().lower() for f in reader.fieldnames}:
        raise ValueError("CSV header must include quantity,unit,ingredient (note optional)")
    for i, r in enumerate(reader, 2):
        r = {k.strip().lower(): (v or "").strip() for k, v in r.items() if k}
        if not r.get("ingredient"):
            continue
        try:
            qty = parse_qty(r["quantity"])
            unit = norm_unit(r.get("unit", ""))
        except ValueError as e:
            raise ValueError(f"line {i}: {e}")
        orig = f"{r['quantity']} {r.get('unit', '')}".strip()
        rows.append({"qty": qty, "unit": unit, "ingredient": r["ingredient"], "note": r.get("note", ""), "original": orig})
    if not rows:
        raise ValueError("no ingredient rows")
    return rows


def oven(temp):
    m = re.fullmatch(r"\s*(\d+(?:\.\d+)?)\s*°?\s*([CcFf])\s*", temp)
    if not m:
        raise ValueError(f"cannot read oven temperature {temp!r} (use 350F or 180C)")
    v, u = float(m[1]), m[2].upper()
    if u == "F":
        c = (v - 32) * 5 / 9
        return f"{v:g}°F = {round(c / 10) * 10:g}°C (fan oven {round(c / 10) * 10 - 20:g}°C)"
    f = v * 9 / 5 + 32
    return f"{v:g}°C = {round(f / 25) * 25:g}°F"


def scale(rows, factor, target="keep", baking=False, depth_ratio=None, pan_change=None, bake_time=None):
    items = [convert(r, factor, target) for r in rows]
    findings = []
    for it, r in zip(items, rows):
        name = r["ingredient"].lower()
        egg = egg_kind(name)
        if egg and r["unit"] == "each":
            q = it["scaled_qty"]
            whole = math.floor(q + 1e-9)
            if abs(q - round(q)) > 0.15:
                extra = (q - whole) * EGG_G[egg]
                findings.append(("MEDIUM", "EGG_FRACTION", r["ingredient"],
                                 f"scales to {q:.2f} {egg}s",
                                 f"Use {whole} whole {egg}{'s' if whole != 1 else ''} plus {round(extra):g} g beaten {egg} (a large {egg} is about {EGG_G[egg]:g} g out of the shell), or round to {round(q)} and expect a {'richer' if round(q) > q else 'drier'} result."))
        if "NO_DENSITY" in it["notes"]:
            findings.append(("LOW", "NO_DENSITY", r["ingredient"], "no density in the table, so it stays in volume",
                             "Weigh it once, or look up grams per cup; for kosher salt the brand matters (Diamond Crystal about 136 g/cup, Morton about 240 g/cup)."))
        ml = it.get("ml")
        if ml is not None and ml / ML["tsp"] < 1 / 8 and r["unit"] in ML:
            findings.append(("LOW", "TINY_AMOUNT", r["ingredient"], f"scales to {ml / ML['tsp']:.2f} tsp",
                             "Use a pinch or a 1/8 tsp measure; for leavening weigh on a 0.1 g scale."))
        if baking and any(w in name for w in LEAVENERS) and (factor > 2 or factor < 0.5):
            findings.append(("LOW", "LEAVENING", r["ingredient"], f"leavening scaled x{factor:.2f}",
                             "Linear scaling is the starting point; measure exactly (weigh), and for factors above 2 consider separate batches because mixing and oven heat do not scale."))
        if not baking and factor > 2 and any(w in name for w in SEASONINGS):
            findings.append(("INFO", "SEASONING", r["ingredient"], f"seasoning scaled x{factor:.2f}",
                             "Add about three quarters, then taste and adjust; evaporation and pot size change how salty or hot it ends up."))
    if baking and (factor > 3 or factor < 1 / 3):
        findings.append(("MEDIUM", "BIG_FACTOR", "-", f"baking recipe scaled x{factor:.2f}",
                         "Bake in several batches of the original size, or check mixer bowl capacity; never multiply the bake time."))
    if depth_ratio is not None:
        sev = "HIGH" if (depth_ratio > 1.5 or depth_ratio < 0.67) else ("MEDIUM" if (depth_ratio > 1.25 or depth_ratio < 0.8) else None)
        if sev and baking:
            if depth_ratio > 1:
                fix = "Batter will be deeper: lower the oven by 25°F/15°C, bake longer and test the centre, keep the pan at most 2/3 full, or use a bigger pan."
            else:
                fix = "Batter will be thinner: start checking 25 to 40 % earlier, or use a smaller pan."
            findings.append((sev, "DEPTH_CHANGE", "-", f"batter depth changes x{depth_ratio:.2f} versus the original pan", fix))
    if baking and pan_change:
        if depth_ratio is None or 0.9 <= depth_ratio <= 1.1:
            tip = "Batter depth stays about the same, so the bake time stays about the same; start checking 5 minutes early. Glass or dark pans bake faster: lower 25°F/15°C."
        elif 0.8 <= depth_ratio <= 1.25:
            tip = f"Batter depth changes slightly (x{depth_ratio:.2f}); {'bake a few minutes longer' if depth_ratio > 1 else 'start checking a few minutes early'} and test the centre."
        else:
            tip = "See DEPTH_CHANGE for time and temperature."
        if bake_time:
            tip = f"Original {bake_time} min. " + tip
        findings.append(("INFO", "PAN_TIME", "-", pan_change, tip))
    if not baking and factor > 1.5:
        findings.append(("INFO", "COOK_TIME", "-", f"scaled x{factor:.2f}",
                         "Cooking time does not scale with quantity: brown meat in batches, allow longer to come to a boil, and use a pot that keeps the depth similar."))
    findings.sort(key=lambda f: SEV_ORDER[f[0]])
    return items, [dict(zip(("severity", "code", "ingredient", "problem", "fix"), f)) for f in findings]


def render(path, factor, how, target, items, findings, oven_line=None):
    out = [f"# Scaled recipe: {path}", "", f"Scale: {how} -> factor x{factor:.3f}   Units: {target}", ""]
    out += ["| Ingredient | Original | Scaled | Also |", "|---|---|---|---|"]
    for it in items:
        out.append(f"| {it['ingredient']} | {it['original']} | {it['display']} | {it.get('also', '')} |")
    if oven_line:
        out += ["", f"Oven: {oven_line}"]
    out += ["", "## Notes", ""]
    if findings:
        out += ["| Severity | Code | Ingredient | Problem | Advice |", "|---|---|---|---|---|"]
        for f in findings:
            out.append(f"| {f['severity']} | {f['code']} | {f['ingredient']} | {f['problem']} | {f['fix']} |")
    else:
        out.append("No caveats.")
    out += ["", "Weights for volume ingredients use spoon-and-level densities; weigh flour if you can."]
    return "\n".join(out)


def self_test():
    cases = []
    def t(name, cond):
        cases.append((name, bool(cond)))
    close = lambda a, b, tol=1e-6: abs(a - b) <= tol
    t("parse 1 1/2", close(parse_qty("1 1/2"), 1.5))
    t("parse 3/4 and .5 and ½", close(parse_qty("3/4"), .75) and close(parse_qty(".5"), .5) and close(parse_qty("1½"), 1.5))
    t("bad quantity rejected", raises(lambda: parse_qty("some")))
    t("unit aliases", norm_unit("Tablespoons") == "tbsp" and norm_unit("T") == "tbsp" and norm_unit("t") == "tsp" and norm_unit("") == "each")
    t("unknown unit rejected", raises(lambda: norm_unit("handful")))
    t("longest density match", density_for("light brown sugar")[0] == "brown sugar" and density_for("all-purpose flour")[1] == 125)
    t("salt vs kosher salt", density_for("salt")[1] == 288 and density_for("kosher salt")[1] is None)
    t("eggs detected", egg_kind("large eggs") == "egg" and egg_kind("egg yolks") == "yolk" and egg_kind("eggplant") is None)
    a8 = parse_pan("8x8")[0]; a913 = parse_pan("9x13")[0]
    t("rect pan area", close(a8, 64) and close(a913, 117))
    t("round pan area", close(parse_pan("round9")[0], math.pi * 20.25))
    t("cm pan", close(parse_pan("20x20cm")[0], (20 / 2.54) ** 2))
    t("bad pan rejected", raises(lambda: parse_pan("big")))
    t("us volume 1 cup", fmt_us_volume(236.588) == "1 cup")
    t("us volume 3/4 cup", fmt_us_volume(ML["cup"] * .75) == "3/4 cup")
    t("us volume 2/3 cup", fmt_us_volume(ML["cup"] * 2 / 3) == "2/3 cup")
    t("us volume cup + tbsp", fmt_us_volume(ML["cup"] * 1.125) == "1 cup + 2 tbsp")
    t("fractions reduced, cups plural", fmt_us_volume(ML["cup"] * 0.61) == "1/2 cup + 2 tbsp" and fmt_us_volume(ML["cup"] * 2) == "2 cups")
    t("us volume tbsp", fmt_us_volume(ML["tbsp"] * 1.5) == "1 1/2 tbsp")
    t("us volume tsp", fmt_us_volume(ML["tsp"] * .5) == "1/2 tsp")
    t("us volume pinch", fmt_us_volume(ML["tsp"] * .05) == "pinch")
    t("metric rounding", round_metric(7.3) == 7.5 and round_metric(57.4) == 57 and round_metric(228) == 230 and round_metric(1234) == 1230)
    t("1 cup flour = 125 g", convert({"qty": 1, "unit": "cup", "ingredient": "all-purpose flour", "original": ""}, 1, "weight")["display"] == "125 g")
    t("1 stick butter in us/keep", "1 stick" in convert({"qty": 1, "unit": "stick", "ingredient": "butter", "original": ""}, 1, "keep")["display"])
    t("8 oz to grams", convert({"qty": 8, "unit": "oz", "ingredient": "cheese", "original": ""}, 1, "metric")["display"] == "225 g")
    t("500 g to us lb", convert({"qty": 500, "unit": "g", "ingredient": "pasta", "original": ""}, 1, "us")["display"] == "1 lb")
    t("metric volume", convert({"qty": 1, "unit": "cup", "ingredient": "milk", "original": ""}, 2, "metric")["display"] == "475 ml")
    t("no density keeps ml", "NO_DENSITY" in convert({"qty": 1, "unit": "tbsp", "ingredient": "fish sauce", "original": ""}, 1, "weight")["notes"])
    rows = read_recipe("quantity,unit,ingredient,note\n2,each,large eggs,\n1/4,tsp,baking soda,\n1,cup,sugar,\n")
    t("csv read", len(rows) == 3 and rows[0]["unit"] == "each")
    t("csv bad header rejected", raises(lambda: read_recipe("a,b\n1,2\n")))
    t("csv bad unit names line", "line 2" in err_of(lambda: read_recipe("quantity,unit,ingredient\n1,handful,x\n")))
    _, f = scale(rows, 1.828, baking=True)
    t("EGG_FRACTION at x1.83", any(x["code"] == "EGG_FRACTION" and "3 whole eggs plus 33 g" in x["fix"] for x in f))
    _, f = scale(rows, 2.0, baking=True)
    t("no EGG_FRACTION when whole", not any(x["code"] == "EGG_FRACTION" for x in f))
    _, f = scale(rows, 0.1, baking=True)
    t("TINY_AMOUNT and BIG_FACTOR", {"TINY_AMOUNT", "BIG_FACTOR", "LEAVENING"} <= {x["code"] for x in f})
    _, f = scale(rows, 1.0, baking=True, depth_ratio=1.83)
    t("DEPTH_CHANGE HIGH", any(x["code"] == "DEPTH_CHANGE" and x["severity"] == "HIGH" for x in f))
    _, f = scale(rows, 1.0, baking=True, depth_ratio=1.3)
    t("DEPTH_CHANGE MEDIUM", any(x["code"] == "DEPTH_CHANGE" and x["severity"] == "MEDIUM" for x in f))
    _, f = scale(read_recipe("quantity,unit,ingredient\n1,tsp,salt\n"), 3, baking=False)
    t("SEASONING and COOK_TIME for cooking", {"SEASONING", "COOK_TIME"} <= {x["code"] for x in f})
    t("oven F to C", oven("350F") == "350°F = 180°C (fan oven 160°C)" and oven("200C") == "200°C = 400°F")
    t("findings sorted HIGH first", scale(rows, 1.83, baking=True, depth_ratio=2)[1][0]["severity"] == "HIGH")
    passed = sum(ok for _, ok in cases)
    for name, ok in cases:
        print(("PASS " if ok else "FAIL ") + name)
    print(f"{passed}/{len(cases)} passed")
    return 0 if passed == len(cases) else 1


def raises(fn):
    try:
        fn()
    except ValueError:
        return True
    return False


def err_of(fn):
    try:
        fn()
    except ValueError as e:
        return str(e)
    return ""


def main():
    ap = argparse.ArgumentParser(description=__doc__, formatter_class=argparse.RawDescriptionHelpFormatter)
    ap.add_argument("recipe", nargs="?")
    g = ap.add_mutually_exclusive_group()
    g.add_argument("--servings", nargs=2, type=float, metavar=("FROM", "TO"))
    g.add_argument("--factor", type=float)
    ap.add_argument("--from-pan")
    ap.add_argument("--to-pan")
    ap.add_argument("--to", default="keep", choices=["keep", "us", "metric", "weight"])
    ap.add_argument("--baking", action="store_true", help="apply baking caveats (eggs, leavening, pan depth)")
    ap.add_argument("--oven", help="original oven temperature, e.g. 350F or 180C")
    ap.add_argument("--time", help="original bake time in minutes, e.g. 20-25")
    ap.add_argument("--json", action="store_true")
    ap.add_argument("--self-test", action="store_true")
    a = ap.parse_args()
    if a.self_test:
        return self_test()
    if not a.recipe:
        ap.print_usage(sys.stderr); return 2
    try:
        rows = read_recipe(open(a.recipe, encoding="utf-8").read())
        depth_ratio = pan_change = None
        if bool(a.from_pan) != bool(a.to_pan):
            raise ValueError("give both --from-pan and --to-pan")
        if a.from_pan:
            fa, fd = parse_pan(a.from_pan)
            ta, td = parse_pan(a.to_pan)
            pan_change = f"{fd} -> {td}, area x{ta / fa:.2f}"
        if a.servings:
            if a.servings[0] <= 0 or a.servings[1] <= 0:
                raise ValueError("servings must be positive")
            factor, how = a.servings[1] / a.servings[0], f"{a.servings[0]:g} -> {a.servings[1]:g} servings"
        elif a.factor is not None:
            if a.factor <= 0:
                raise ValueError("factor must be positive")
            factor, how = a.factor, f"factor {a.factor:g}"
        elif a.from_pan:
            factor, how = ta / fa, f"pan {a.from_pan} -> {a.to_pan}"
        else:
            raise ValueError("give --servings FROM TO, --factor F or --from-pan/--to-pan")
        if a.from_pan:
            depth_ratio = factor * fa / ta
            if abs(depth_ratio - 1) < 0.01:
                depth_ratio = None
        items, findings = scale(rows, factor, a.to, a.baking, depth_ratio, pan_change, a.time)
        oven_line = oven(a.oven) if a.oven else None
    except (OSError, UnicodeDecodeError, ValueError) as e:
        print(f"error: {e}", file=sys.stderr); return 2
    if a.json:
        print(json.dumps({"factor": factor, "how": how, "units": a.to, "oven": oven_line,
                          "items": [{k: v for k, v in it.items() if k != "notes"} for it in items],
                          "findings": findings}, indent=2, ensure_ascii=False))
    else:
        print(render(a.recipe, factor, how, a.to, items, findings, oven_line))
    return 1 if any(f["severity"] == "HIGH" for f in findings) else 0


if __name__ == "__main__":
sys.exit(main())Reviews terraform plan and show -json output before apply. Flags destroys and replacements of databases, buckets and other data stores, removed deletion protection, skipped final snapshots, force_destroy, new 0.0.0.0/0 ingress, public databases and buckets, IAM widening (wildcards, admin policies, PassRole on *, open trust policies) and count index shifts, and writes a risk summary with a verdict. Includes a stdlib Python checker with --self-test.
---
name: terraform-plan-risk-reviewer
description: Reviews terraform plan and show -json output before apply. Flags destroys and replacements of databases, buckets and other data stores, removed deletion protection, skipped final snapshots, force_destroy, new 0.0.0.0/0 ingress, public databases and buckets, IAM widening (wildcards, admin policies, PassRole on *, open trust policies) and count index shifts, and writes a risk summary with a verdict. Includes a stdlib Python checker with --self-test.
---
# Terraform Plan Risk Reviewer
You review Terraform (or OpenTofu) plans the way a careful platform engineer does before approving an apply: what will be destroyed or replaced, what data could be lost, what becomes reachable from the internet, and who gains permissions. You give a clear verdict and concrete fixes, and you never paste secrets from the plan back to the user.
## Files in this skill
- `scripts/plan_risk.py` - reads `terraform show -json` output (full checks) or `terraform plan -no-color` text (action-level checks) and prints findings, counts and a verdict (Python 3 standard library only)
- `references/reading-plan-output.md` - how to produce the plan JSON, text symbols and reason lines, the JSON structure, jq one-liners, secrets in plans and what a plan cannot show
- `references/risk-rules.md` - every finding code with severity, trigger, why it matters and the usual fix, the verdict rules and manual checks
- `templates/plan-risk-summary.md` - the summary to post on the pull request
- `examples/shop-prod-plan.json` - a production plan with a replaced database, a deleted bucket, an SSH rule open to the world, a widened CI policy, an admin attachment and a count shift
## Workflow
### 1. Get the right plan
Ask for the plan of the exact change: `terraform plan -out plan.out` then `terraform show -json plan.out > plan.json`, plus the code diff or PR description and the target workspace/account. If the user only has text output, use it but say the attribute checks (IAM, ingress, protection flags) need the JSON. Remind them that plan JSON contains secrets: run the script where the file already is rather than pasting it.
### 2. Run the checker
```
python3 scripts/plan_risk.py examples/shop-prod-plan.json
python3 scripts/plan_risk.py plan.json --json
python3 scripts/plan_risk.py plan.txt
python3 scripts/plan_risk.py --self-test
```
Exit 1 means at least one HIGH finding, 2 means the file is not a plan.
### 3. Review like a human
- Compare the changes with the code diff: anything not explained by the diff (provider upgrade, drift, renamed resources) needs an answer before apply.
- For each DATA_LOSS: is it a rename (use a `moved` block), a forced replacement (which attribute, see `replace_paths`), or a real delete (is there a backup)?
- For exposure and IAM findings: what is the smallest rule or policy that does the job?
- Check what the script cannot see (`references/risk-rules.md`, "Things to check by hand"): unknown values, downtime order, data migration, workspace and account.
### 4. Deliver
Fill `templates/plan-risk-summary.md`: verdict, HIGH items with fix or named acceptance, MEDIUM items with owner, expected vs unexpected changes, apply steps with a rollback. Give code fixes as small HCL snippets (moved blocks, lifecycle, scoped policies).
## Example result
`examples/shop-prod-plan.json` (Terraform 1.9.8): 2 create, 4 update, 2 replace, 2 destroy; 6 HIGH, 5 MEDIUM, 2 LOW, 2 INFO, verdict DO NOT APPLY. HIGH: the orders RDS instance is replaced (destroy first) because `storage_encrypted` changed, with deletion protection off and no final snapshot; the legacy logs bucket is deleted with force_destroy; SSH opened to 0.0.0.0/0 on the bastion; the S3 public access block is turned off for the assets bucket; the CI role gets `iam:PassRole` on `*` (and `s3:*`); AdministratorAccess is attached to the ops role. MEDIUM also includes `aws_instance.web[1]` destroyed by a count index shift. Fix: snapshot and migrate the database, `moved` or a `removed` block for the bucket, SSM instead of public SSH, scoped policies, for_each for web instances.
## Rules
- Never print or quote passwords, keys or tokens from a plan, even if they are visible in the JSON.
- A HIGH finding blocks the apply until it is fixed or a named owner accepts it in writing.
- Prefer `moved`, `removed` and `import` blocks over destroy-and-recreate for refactors.
- Data stores need a backup before any destroy or replace, and `prevent_destroy` afterwards.
- Do not approve plans you cannot see in full (truncated output, `-target` runs, errored plans); ask for the complete plan.
- Policy-as-code (OPA/Conftest, Sentinel, Checkov, tfsec) is a good follow-up, not a replacement for reading the plan.
FILE:references/reading-plan-output.md
# Reading Terraform plan output
## Get a machine-readable plan
```
terraform plan -out plan.out # add -var-file / -target exactly as the real apply will
terraform show -json plan.out > plan.json
terraform show -no-color plan.out > plan.txt # human-readable copy of the same saved plan
```
Review the SAME saved plan you will apply (`terraform apply plan.out`), not a fresh plan: state or remote resources can change in between. OpenTofu uses the same commands (`tofu show -json`) and format.
## Text symbols
| Symbol | Header line | Meaning |
|---|---|---|
| `+` | `will be created` | new resource |
| `~` | `will be updated in-place` | attributes change, same resource ID |
| `-` | `will be destroyed` | resource deleted |
| `-/+` | `must be replaced` | destroy first, then create (default) - downtime gap |
| `+/-` | `must be replaced` | create first, then destroy (`create_before_destroy`) |
| `<=` | `will be read during apply` | data source read; check why it is unknown at plan time |
| `# forces replacement` | after an attribute | this attribute change causes the replacement |
| `(known after apply)` | value | computed; you cannot review it now |
| `(sensitive value)` | value | hidden in text output, but present in plan JSON |
Reason lines under a header: `# (because aws_x.y is not in configuration)` (removed from code or moved without a `moved` block), `# (because index [1] is out of range for count)` (count shrank or shifted), `# (because key ["a"] is not in for_each map)`, `# (resource is tainted, so must be replaced)`, `# (replace requested)` (`-replace=` flag).
Summary line: `Plan: 3 to add, 1 to change, 3 to destroy.` A replacement counts once in "add" and once in "destroy", so compare destroy count with the number of `-` and `-/+` headers.
## JSON structure (format_version 1.x)
```
{
"format_version": "1.2", "terraform_version": "1.9.8",
"resource_changes": [ {
"address": "module.db.aws_db_instance.main", "module_address": "module.db",
"mode": "managed" | "data", "type": "aws_db_instance", "name": "main", "index": 0 | "key",
"change": {
"actions": ["create"] | ["update"] | ["delete"] | ["delete","create"] | ["create","delete"] | ["no-op"] | ["read"] | ["forget"],
"before": {...} | null, "after": {...} | null,
"after_unknown": {"id": true}, # values known only after apply
"before_sensitive": {...}, "after_sensitive": {"password": true},
"replace_paths": [["storage_encrypted"]], # attributes that force replacement
"importing": {"id": "..."} # import blocks (1.5+)
},
"action_reason": "replace_because_cannot_update" | "replace_because_tainted" | "replace_by_request" |
"delete_because_no_resource_config" | "delete_because_count_index" | "delete_because_each_key" | ...,
"previous_address": "aws_db_instance.old" # moved blocks
} ],
"resource_drift": [ ... changes made outside Terraform ... ],
"output_changes": {...}, "prior_state": {...}, "configuration": {...},
"applyable": true, "complete": true, "errored": false
}
```
Useful one-liners:
```
jq -r '.resource_changes[] | select(.change.actions != ["no-op"]) | "\(.change.actions | join(",")) \(.address)"' plan.json
jq -r '.resource_changes[] | select(.change.actions | index("delete")) | .address' plan.json
jq -r '.resource_changes[] | select(.change.replace_paths) | "\(.address): \(.change.replace_paths)"' plan.json
```
## Secrets in plans
`before`/`after` contain real values, including passwords and private keys, even when `*_sensitive` marks them. Treat plan.out and plan.json like secrets: do not attach them to tickets, chats or public CI logs; keep them as short-lived, access-controlled CI artifacts. Share the risk summary instead.
## What a plan cannot tell you
- Values computed at apply time (`known after apply`), including many IAM policy documents built from other resources.
- Side effects outside Terraform: DNS caches, clients pinned to an IP, data inside a database being replaced.
- Whether `lifecycle { prevent_destroy = true }` is set (it is in `configuration`, and a plan that would violate it fails instead).
- Provider-specific behaviour such as RDS applying some changes only in the next maintenance window (`apply_immediately`).
FILE:references/risk-rules.md
# Risk rules used by plan_risk.py
| Code | Severity | Trigger | Why it matters | Typical fix |
|---|---|---|---|---|
| DATA_LOSS | HIGH | destroy or replace of a data-holding type: databases (RDS, Cloud SQL, Azure SQL/PostgreSQL/MySQL, Cosmos DB, DynamoDB), buckets, disks/volumes, EFS/FSx, caches, queues/streams, KMS keys, secrets, DNS zones, log groups, ECR, Kubernetes PVCs/namespaces | a new resource starts empty; KMS key deletion makes encrypted data unreadable | snapshot/backup first, `moved` block for refactors, `prevent_destroy` on data stores, migrate data before replacing |
| PROTECTION_OFF | HIGH (update) / MEDIUM (new or replaced) | `deletion_protection`, `deletion_protection_enabled`, `enable_deletion_protection`, `termination_protection`, `disable_api_termination` false | the next mistake can delete production | keep true; disable only in a separate change right before a planned delete |
| PUBLIC_INGRESS | HIGH | new 0.0.0.0/0 or ::/0 ingress on all ports or admin/data ports (22, 3389, 3306, 5432, 1433, 6379, 27017, 9200, 6443 ...) | direct attack surface, brute force, data exposure | known CIDRs, SSM Session Manager, VPN, bastion, private endpoints |
| PUBLIC_INGRESS | MEDIUM / INFO | other ports / 80 and 443 | | expose only load balancers |
| PUBLIC_DATABASE | HIGH | `publicly_accessible = true` | database endpoint reachable from the internet | private subnets, proxy, VPN |
| S3_PUBLIC_ACCESS | HIGH | any of the four public access block settings set to false | bucket policies or ACLs can make data public | keep all four true; CloudFront + Origin Access Control |
| PUBLIC_ACL | HIGH | `public-read`, `public-read-write`, `authenticated-read` | everyone can list or read (or write) | BucketOwnerEnforced, private |
| PUBLIC_POLICY | HIGH | resource policy Allow with Principal `*` and no Condition | anyone on the internet (or any AWS account) gets access | named principals; `aws:SourceArn`, `aws:PrincipalOrgID`, `aws:SourceVpce` |
| PUBLIC_IAM | HIGH | GCP binding to `allUsers` / `allAuthenticatedUsers` | public access | specific members |
| TRUST_ANYONE | HIGH | role trust policy with Principal `*` and no Condition | any AWS account can assume the role | exact ARNs + `sts:ExternalId` |
| IAM_ADMIN | HIGH | `Action * / Resource *`, AdministratorAccess, PowerUserAccess, IAMFullAccess, GCP owner/editor, Azure Owner/User Access Administrator (Contributor = MEDIUM) | full control of the account or project | least privilege; break-glass admin with MFA |
| IAM_ESCALATION | HIGH | `iam:PassRole`, `iam:Attach*/Put*Policy`, `iam:CreatePolicyVersion`, `iam:CreateAccessKey`, `sts:AssumeRole`, `kms:*` on `*`; `iam:*`, `sts:*` anywhere | the holder can grant itself more rights | scope to specific ARNs; `iam:PassedToService` condition |
| IAM_WILDCARD | HIGH on `*` / MEDIUM | `service:*` actions, `*FullAccess` managed policies | far more than needed, includes delete | list actions actually used (Access Analyzer, CloudTrail) |
| IAM_NOT_ACTION | MEDIUM | Allow with NotAction | grants everything else, including future actions | explicit Action list |
| IAM_WIDENED | LOW | update adds actions or resources to a policy | permission creep | confirm with the owner |
| TRUST_WIDENED | MEDIUM | new principals in a trust policy | new cross-account access | confirm each principal |
| NO_FINAL_SNAPSHOT | MEDIUM | `skip_final_snapshot = true` on RDS/Aurora/DocumentDB/Neptune/Redshift | deleting leaves nothing to restore | `false` + `final_snapshot_identifier` |
| FORCE_DESTROY | MEDIUM | `force_destroy = true` newly set | delete wipes all objects or records | keep false on real data |
| ENCRYPTION_OFF | MEDIUM | `storage_encrypted`/`encrypted` false | compliance; enabling later usually forces replacement | enable now |
| BACKUPS_OFF | MEDIUM | `backup_retention_period = 0` | no point-in-time recovery | 7 to 35 days |
| SECRET_REGENERATED | MEDIUM | replace of `random_password`, `random_string`, `tls_private_key`, `aws_iam_access_key` | consumers break | plan the rotation |
| COUNT_INDEX_SHIFT | MEDIUM | `delete_because_count_index` | removing a middle item destroys and recreates the following ones | `for_each` with stable keys, `moved` blocks |
| DESTROY | MEDIUM (compute, LB, IP, cluster, count/each removal) / LOW | non-stateful destroy | downtime, lost IPs | confirm intent; `moved` for refactors |
| REPLACE | MEDIUM (destroy-first compute/LB) / LOW | non-stateful replace | new IDs, IPs, DNS names; downtime gap | `create_before_destroy`, check dependents |
| PUBLIC_FUNCTION_URL | MEDIUM | Lambda URL with auth NONE | public endpoint | AWS_IAM auth |
| PLAN_ERRORED / PLAN_INCOMPLETE | HIGH / MEDIUM | `errored` / `complete: false` | partial picture | re-plan |
| DRIFT, REMOVED_FROM_CONFIG, MOVED, IMPORT, FORGET, POLICY_UNKNOWN, TEXT_MODE | INFO | context | | |
## Verdict
- Any HIGH: do not apply until each HIGH is fixed or explicitly accepted by the owner (name and reason in the review).
- Only MEDIUM: apply after the owner of each affected resource agrees.
- LOW/INFO only: normal review.
## Things to check by hand
- **Blast radius:** how many resources change, and are they all expected from the code diff? A one-line change that replaces 40 resources is a red flag (provider upgrade, changed `name`, `count` to `for_each`).
- **Order and downtime:** destroy-first replacements of anything serving traffic; DNS TTLs; target group swaps.
- **Data migration:** a replaced database needs a restore from snapshot or a data migration plan; Terraform will not copy data.
- **Unknown values:** policies or security group rules that are `known after apply` - review the module code instead.
- **Provider and module upgrades:** read the changelog for forced replacements and default changes.
- **Environment:** confirm the workspace/backend (`terraform workspace show`) and account (`aws sts get-caller-identity`) before applying.
- **Policy as code:** OPA/Conftest, Sentinel, Checkov or tfsec rules can enforce the HIGH checks in CI.
FILE:templates/plan-risk-summary.md
# Terraform plan risk summary: <stack / workspace>
**Change:** <PR #123 "Encrypt orders DB, open bastion for vendor"> **Workspace/account:** <prod / 123456789012 eu-west-1>
**Plan:** <terraform 1.9.8, plan.out from CI run 4567> **Counts:** <2 create, 4 update, 2 replace, 2 destroy>
**Verdict:** <DO NOT APPLY as is / Apply after review / Low risk>
## Must fix or explicitly accept (HIGH)
| # | Resource | Risk | Why | Fix or acceptance (who) |
|---|---|---|---|---|
| 1 | <`aws_db_instance.orders`> | <DATA_LOSS: replaced because storage_encrypted changed> | <new empty DB; no final snapshot> | <snapshot, restore into encrypted copy, switch with a moved/import plan> |
## Needs owner review (MEDIUM)
| # | Resource | Risk | Owner OK? |
|---|---|---|---|
| 1 | <`aws_instance.web[1]`> | <COUNT_INDEX_SHIFT> | <yes/no> |
## Low / info
- <IAM_WIDENED on ci_deploy: s3:* - replaced by explicit actions in the fix>
- <Drift on aws_lb.public tags: set in console by ...>
## Expected vs unexpected changes
- Expected from the code diff: <...>
- Not explained by the code diff: <... investigate before apply>
## Apply plan
1. <Take snapshot `orders-pre-encrypt-2026-10-27`>
2. <Apply in a maintenance window: <time, zone>>
3. <Verify: app health checks, `aws rds describe-db-instances`, bastion only from VPN>
4. Rollback: <restore snapshot / revert PR and re-apply>
## Follow-ups
- <add prevent_destroy to data stores>
- <policy-as-code rule for 0.0.0.0/0 on port 22>
FILE:examples/shop-prod-plan.json
{
"format_version": "1.2",
"terraform_version": "1.9.8",
"planned_values": {"root_module": {}},
"resource_drift": [
{
"address": "aws_lb.public",
"mode": "managed",
"type": "aws_lb",
"name": "public",
"provider_name": "registry.terraform.io/hashicorp/aws",
"change": {
"actions": ["update"],
"before": {"name": "shop-public", "tags": {"env": "prod"}},
"after": {"name": "shop-public", "tags": {"env": "prod", "owner": "set-in-console"}},
"after_unknown": {},
"before_sensitive": {},
"after_sensitive": {}
}
}
],
"resource_changes": [
{
"address": "aws_cloudwatch_log_group.app",
"mode": "managed",
"type": "aws_cloudwatch_log_group",
"name": "app",
"provider_name": "registry.terraform.io/hashicorp/aws",
"change": {
"actions": ["create"],
"before": null,
"after": {"name": "/shop/app", "retention_in_days": 30, "tags": {"env": "prod"}},
"after_unknown": {"arn": true, "id": true},
"before_sensitive": false,
"after_sensitive": {}
}
},
{
"address": "aws_db_instance.orders",
"mode": "managed",
"type": "aws_db_instance",
"name": "orders",
"provider_name": "registry.terraform.io/hashicorp/aws",
"change": {
"actions": ["delete", "create"],
"before": {"identifier": "shop-orders", "engine": "postgres", "engine_version": "16.4", "instance_class": "db.t4g.medium", "allocated_storage": 100, "storage_encrypted": false, "deletion_protection": false, "skip_final_snapshot": true, "backup_retention_period": 7, "publicly_accessible": false, "username": "orders_admin", "password": null, "tags": {"env": "prod"}},
"after": {"identifier": "shop-orders", "engine": "postgres", "engine_version": "16.4", "instance_class": "db.t4g.medium", "allocated_storage": 100, "storage_encrypted": true, "deletion_protection": false, "skip_final_snapshot": true, "backup_retention_period": 7, "publicly_accessible": false, "username": "orders_admin", "password": null, "tags": {"env": "prod"}, "kms_key_id": null},
"after_unknown": {"id": true, "arn": true, "endpoint": true, "address": true},
"before_sensitive": {"password": true},
"after_sensitive": {"password": true},
"replace_paths": [["storage_encrypted"]]
},
"action_reason": "replace_because_cannot_update"
},
{
"address": "aws_iam_role_policy.ci_deploy",
"mode": "managed",
"type": "aws_iam_role_policy",
"name": "ci_deploy",
"provider_name": "registry.terraform.io/hashicorp/aws",
"change": {
"actions": ["update"],
"before": {"id": "shop-ci:deploy", "name": "deploy", "role": "shop-ci", "policy": "{\"Version\": \"2012-10-17\", \"Statement\": [{\"Sid\": \"Deploy\", \"Effect\": \"Allow\", \"Action\": [\"s3:PutObject\", \"s3:GetObject\"], \"Resource\": \"arn:aws:s3:::shop-assets-prod/*\"}]}"},
"after": {"id": "shop-ci:deploy", "name": "deploy", "role": "shop-ci", "policy": "{\"Version\": \"2012-10-17\", \"Statement\": [{\"Sid\": \"Deploy\", \"Effect\": \"Allow\", \"Action\": \"s3:*\", \"Resource\": [\"arn:aws:s3:::shop-assets-prod\", \"arn:aws:s3:::shop-assets-prod/*\"]}, {\"Sid\": \"PassAnyRole\", \"Effect\": \"Allow\", \"Action\": \"iam:PassRole\", \"Resource\": \"*\"}]}"},
"after_unknown": {},
"before_sensitive": {},
"after_sensitive": {}
}
},
{
"address": "aws_iam_role_policy_attachment.ops_admin",
"mode": "managed",
"type": "aws_iam_role_policy_attachment",
"name": "ops_admin",
"provider_name": "registry.terraform.io/hashicorp/aws",
"change": {
"actions": ["create"],
"before": null,
"after": {"role": "shop-ops", "policy_arn": "arn:aws:iam::aws:policy/AdministratorAccess"},
"after_unknown": {"id": true},
"before_sensitive": false,
"after_sensitive": {}
}
},
{
"address": "aws_instance.web[1]",
"mode": "managed",
"type": "aws_instance",
"name": "web",
"index": 1,
"provider_name": "registry.terraform.io/hashicorp/aws",
"change": {
"actions": ["delete"],
"before": {"id": "i-0b1c2d3e4f5a6b7c8", "ami": "ami-0abc1234def567890", "instance_type": "t3.medium", "associate_public_ip_address": false, "tags": {"Name": "shop-web-1"}},
"after": null,
"after_unknown": {},
"before_sensitive": {},
"after_sensitive": false
},
"action_reason": "delete_because_count_index"
},
{
"address": "aws_lb.public",
"mode": "managed",
"type": "aws_lb",
"name": "public",
"provider_name": "registry.terraform.io/hashicorp/aws",
"change": {
"actions": ["update"],
"before": {"name": "shop-public", "internal": false, "enable_deletion_protection": true, "tags": {"env": "prod", "owner": "set-in-console"}},
"after": {"name": "shop-public", "internal": false, "enable_deletion_protection": true, "tags": {"env": "prod", "team": "shop"}},
"after_unknown": {},
"before_sensitive": {},
"after_sensitive": {}
}
},
{
"address": "aws_lb_target_group.web",
"mode": "managed",
"type": "aws_lb_target_group",
"name": "web",
"provider_name": "registry.terraform.io/hashicorp/aws",
"change": {
"actions": ["create", "delete"],
"before": {"name_prefix": "web-", "port": 8080, "protocol": "HTTP", "vpc_id": "vpc-0a1b2c3d"},
"after": {"name_prefix": "web-", "port": 8081, "protocol": "HTTP", "vpc_id": "vpc-0a1b2c3d"},
"after_unknown": {"id": true, "arn": true, "name": true},
"before_sensitive": {},
"after_sensitive": {},
"replace_paths": [["port"]]
},
"action_reason": "replace_because_cannot_update"
},
{
"address": "aws_s3_bucket.legacy_logs",
"mode": "managed",
"type": "aws_s3_bucket",
"name": "legacy_logs",
"provider_name": "registry.terraform.io/hashicorp/aws",
"change": {
"actions": ["delete"],
"before": {"bucket": "shop-legacy-logs-prod", "force_destroy": true, "tags": {"env": "prod"}},
"after": null,
"after_unknown": {},
"before_sensitive": {},
"after_sensitive": false
},
"action_reason": "delete_because_no_resource_config"
},
{
"address": "aws_s3_bucket_public_access_block.assets",
"mode": "managed",
"type": "aws_s3_bucket_public_access_block",
"name": "assets",
"provider_name": "registry.terraform.io/hashicorp/aws",
"change": {
"actions": ["update"],
"before": {"bucket": "shop-assets-prod", "block_public_acls": true, "block_public_policy": true, "ignore_public_acls": true, "restrict_public_buckets": true},
"after": {"bucket": "shop-assets-prod", "block_public_acls": true, "block_public_policy": false, "ignore_public_acls": true, "restrict_public_buckets": false},
"after_unknown": {},
"before_sensitive": {},
"after_sensitive": {}
}
},
{
"address": "aws_security_group.bastion",
"mode": "managed",
"type": "aws_security_group",
"name": "bastion",
"provider_name": "registry.terraform.io/hashicorp/aws",
"change": {
"actions": ["update"],
"before": {"name": "shop-bastion", "ingress": [{"cidr_blocks": ["10.20.0.0/16"], "description": "SSH from VPN", "from_port": 22, "to_port": 22, "protocol": "tcp", "ipv6_cidr_blocks": [], "prefix_list_ids": [], "security_groups": [], "self": false}], "egress": []},
"after": {"name": "shop-bastion", "ingress": [{"cidr_blocks": ["10.20.0.0/16"], "description": "SSH from VPN", "from_port": 22, "to_port": 22, "protocol": "tcp", "ipv6_cidr_blocks": [], "prefix_list_ids": [], "security_groups": [], "self": false}, {"cidr_blocks": ["0.0.0.0/0"], "description": "temp: SSH for vendor", "from_port": 22, "to_port": 22, "protocol": "tcp", "ipv6_cidr_blocks": [], "prefix_list_ids": [], "security_groups": [], "self": false}], "egress": []},
"after_unknown": {},
"before_sensitive": {},
"after_sensitive": {}
}
},
{
"address": "module.network.aws_vpc.main",
"module_address": "module.network",
"mode": "managed",
"type": "aws_vpc",
"name": "main",
"provider_name": "registry.terraform.io/hashicorp/aws",
"change": {
"actions": ["no-op"],
"before": {"cidr_block": "10.20.0.0/16"},
"after": {"cidr_block": "10.20.0.0/16"},
"after_unknown": {},
"before_sensitive": {},
"after_sensitive": {}
}
}
],
"prior_state": {"format_version": "1.0", "terraform_version": "1.9.8"},
"configuration": {"provider_config": {"aws": {"name": "aws", "full_name": "registry.terraform.io/hashicorp/aws"}}},
"timestamp": "2026-10-27T07:10:00Z",
"applyable": true,
"complete": true,
"errored": false
}
FILE:scripts/plan_risk.py
#!/usr/bin/env python3
"""Terraform plan risk reviewer (Python 3 standard library only).
Reads `terraform show -json plan.out` output (or, with less detail, the text of
`terraform plan -no-color`) and flags risky changes: destroys and replacements of
stateful resources (data loss), removed deletion protection, skipped final
snapshots, force_destroy, disabled encryption, new public network exposure
(0.0.0.0/0 or ::/0 ingress, public databases, S3 public access blocks, public ACLs
and policies, allUsers bindings), IAM widening (wildcard actions, admin policies,
iam:PassRole on *, trust policies open to anyone) and count index shifts. Prints a
risk summary. Never prints attribute values that Terraform marks as sensitive.
Usage:
terraform plan -out plan.out && terraform show -json plan.out > plan.json
python3 plan_risk.py plan.json [--json]
terraform plan -no-color > plan.txt && python3 plan_risk.py plan.txt (text mode)
python3 plan_risk.py --self-test
Exit codes: 0 = no HIGH findings, 1 = HIGH findings, 2 = unreadable input.
"""
import argparse, json, re, sys
SEV_ORDER = {"HIGH": 0, "MEDIUM": 1, "LOW": 2, "INFO": 3}
STATEFUL = re.compile(r"^(aws_(db_instance|rds_cluster|dynamodb_table|s3_bucket|ebs_volume|efs_file_system|"
r"elasticache_(cluster|replication_group)|redshift_cluster|docdb_cluster|neptune_cluster|"
r"opensearch_domain|elasticsearch_domain|kinesis_stream|sqs_queue|kms_key|secretsmanager_secret|"
r"backup_vault|ecr_repository|cloudwatch_log_group|msk_cluster|fsx_\w+|route53_zone|"
r"cognito_user_pool|timestream_table)|"
r"google_(sql_database_instance|sql_database|storage_bucket|bigquery_(dataset|table)|compute_disk|"
r"spanner_(instance|database)|kms_crypto_key|redis_instance|filestore_instance|firestore_database|"
r"dns_managed_zone)|"
r"azurerm_(storage_account|storage_container|mssql_(database|server)|postgresql_flexible_server|"
r"mysql_flexible_server|cosmosdb_account|key_vault|managed_disk|redis_cache|dns_zone)|"
r"kubernetes_(persistent_volume_claim|persistent_volume|namespace)(_v1)?)$")
SECRET_GEN = re.compile(r"^(random_password|random_string|tls_private_key|aws_iam_access_key)$")
DOWNTIME = re.compile(r"^(aws_(instance|lb|alb|eip|nat_gateway|cloudfront_distribution|api_gateway_rest_api|"
r"eks_cluster|ecs_service|acm_certificate)|google_(compute_instance|container_cluster)|"
r"azurerm_(linux|windows)_virtual_machine|azurerm_kubernetes_cluster)$")
SENSITIVE_PORTS = {22: "SSH", 23: "Telnet", 3389: "RDP", 3306: "MySQL", 5432: "PostgreSQL", 1433: "SQL Server",
1521: "Oracle", 6379: "Redis", 27017: "MongoDB", 9200: "Elasticsearch", 5601: "Kibana",
2375: "Docker API", 2379: "etcd", 11211: "Memcached", 5900: "VNC", 9092: "Kafka",
6443: "Kubernetes API", 10250: "Kubelet"}
WEB_PORTS = {80, 443}
PUBLIC_CIDRS = {"0.0.0.0/0", "::/0", "*", "internet", "any"}
ADMIN_POLICIES = re.compile(r"(AdministratorAccess|PowerUserAccess|IAMFullAccess)$")
ESCALATION_ACTIONS = {"iam:*", "iam:passrole", "iam:createpolicyversion", "iam:attachrolepolicy", "iam:putrolepolicy",
"iam:createaccesskey", "iam:updateassumerolepolicy", "sts:assumerole", "sts:*", "kms:*", "*"}
POLICY_ATTRS = ("policy", "assume_role_policy", "inline_policy")
PROTECTION_ATTRS = ("deletion_protection", "deletion_protection_enabled", "enable_deletion_protection",
"termination_protection", "disable_api_termination")
def finding(sev, code, addr, problem, fix):
return {"severity": sev, "code": code, "resource": addr, "problem": problem, "fix": fix}
def kind_of(actions):
a = list(actions or [])
if a == ["delete", "create"]:
return "replace (destroy first)"
if a == ["create", "delete"]:
return "replace (create first)"
return {"create": "create", "update": "update", "delete": "destroy", "no-op": "no-op", "read": "read",
"forget": "forget"}.get(a[0] if len(a) == 1 else ",".join(a), ",".join(a))
def sensitive(mask, key):
return mask is True or (isinstance(mask, dict) and mask.get(key) not in (None, False))
def get(d, key, default=None):
return d.get(key, default) if isinstance(d, dict) else default
def ports_of(lo, hi, proto):
proto = str(proto).lower()
if proto in ("-1", "all", "*"):
return 0, 65535, "all"
try:
lo, hi = int(lo if lo not in (None, "") else 0), int(hi if hi not in (None, "") else 65535)
except (TypeError, ValueError):
return 0, 65535, proto
if proto in ("icmp", "icmpv6", "1", "58"):
return None
if lo in (-1,) or (lo == 0 and hi in (0, 65535)):
return 0, 65535, proto
return lo, hi, proto
def open_rules(rtype, values):
"""Yield (cidr, lo, hi, proto) for internet-open ingress rules in a resource's values."""
v = values or {}
out = set()
def add(cidrs, lo, hi, proto):
p = ports_of(lo, hi, proto)
if p is None:
return
for c in cidrs or []:
if str(c).lower() in PUBLIC_CIDRS:
out.add((str(c), p[0], p[1], p[2]))
if rtype == "aws_security_group":
for r in v.get("ingress") or []:
add((r.get("cidr_blocks") or []) + (r.get("ipv6_cidr_blocks") or []), r.get("from_port"), r.get("to_port"), r.get("protocol"))
elif rtype == "aws_security_group_rule" and v.get("type") == "ingress":
add((v.get("cidr_blocks") or []) + (v.get("ipv6_cidr_blocks") or []), v.get("from_port"), v.get("to_port"), v.get("protocol"))
elif rtype == "aws_vpc_security_group_ingress_rule":
add([x for x in (v.get("cidr_ipv4"), v.get("cidr_ipv6")) if x], v.get("from_port"), v.get("to_port"), v.get("ip_protocol"))
elif rtype == "google_compute_firewall" and str(v.get("direction", "INGRESS")).upper() == "INGRESS":
for al in v.get("allow") or []:
ports = al.get("ports") or ["0-65535"]
for pr in ports:
lo, _, hi = str(pr).partition("-")
add(v.get("source_ranges"), lo, hi or lo, al.get("protocol", "all"))
elif rtype == "azurerm_network_security_rule" and str(v.get("direction")).lower() == "inbound" and str(v.get("access")).lower() == "allow":
src = [v.get("source_address_prefix")] + (v.get("source_address_prefixes") or [])
rng = v.get("destination_port_range") or "*"
for pr in [rng] + (v.get("destination_port_ranges") or []):
if pr == "*":
add(src, 0, 65535, v.get("protocol", "*"))
else:
lo, _, hi = str(pr).partition("-")
add(src, lo, hi or lo, v.get("protocol", "*"))
return out
def port_label(lo, hi, proto):
if proto == "all" or (lo == 0 and hi == 65535):
return "all ports"
names = [f"{p} ({n})" for p, n in SENSITIVE_PORTS.items() if lo <= p <= hi]
rng = str(lo) if lo == hi else f"{lo}-{hi}"
return f"port {rng}" + (f" incl. {', '.join(names[:3])}" if names and lo != hi else (f" ({SENSITIVE_PORTS[lo]})" if lo == hi and lo in SENSITIVE_PORTS else ""))
def parse_policy(doc):
if isinstance(doc, str):
try:
doc = json.loads(doc)
except ValueError:
return None
if not isinstance(doc, dict):
return None
st = doc.get("Statement") or []
return [st] if isinstance(st, dict) else st
def as_list(x):
return x if isinstance(x, list) else ([] if x is None else [x])
def allow_actions(stmts):
acts = set()
for s in stmts or []:
if s.get("Effect", "Allow") != "Allow":
continue
for a in as_list(s.get("Action")):
for r in as_list(s.get("Resource")) or ["(none)"]:
acts.add((str(a), str(r)))
return acts
def check_policy(addr, attr, before, after, unknown):
out = []
if unknown:
return [finding("INFO", "POLICY_UNKNOWN", addr, f"{attr} is only known after apply", "Review the rendered policy after apply or render it with a data source in a separate plan.")]
b, a = parse_policy(before), parse_policy(after)
if a is None:
return out
if attr == "assume_role_policy":
for s in a:
if s.get("Effect", "Allow") != "Allow":
continue
pr = s.get("Principal")
vals = [pr] if isinstance(pr, str) else [v for x in (pr or {}).values() for v in as_list(x)]
if "*" in vals and not s.get("Condition"):
out.append(finding("HIGH", "TRUST_ANYONE", addr, "trust policy lets any AWS principal assume this role (Principal * without Condition)",
"Name the exact account or role ARNs, and add sts:ExternalId or aws:PrincipalOrgID conditions."))
bp = {v for s in (b or []) for x in (get(s, "Principal") or {}).values() for v in as_list(x)} if b and all(isinstance(get(s, "Principal"), dict) for s in b) else set()
ap = {v for s in a if isinstance(s.get("Principal"), dict) for x in s["Principal"].values() for v in as_list(x)}
new = sorted(ap - bp - {"*"})
if b is not None and new:
out.append(finding("MEDIUM", "TRUST_WIDENED", addr, "new principals can assume this role: " + ", ".join(new), "Confirm each new principal is expected (cross-account access?)."))
return out
for s in a:
if s.get("Effect", "Allow") != "Allow":
continue
orig = [str(x) for x in as_list(s.get("Action"))]
acts = [x.lower() for x in orig]
res = [str(x) for x in as_list(s.get("Resource"))]
pr = s.get("Principal")
if pr is not None:
vals = [pr] if isinstance(pr, str) else [v for x in pr.values() for v in as_list(x)]
if "*" in vals and not s.get("Condition"):
out.append(finding("HIGH", "PUBLIC_POLICY", addr, f"resource policy allows Principal * ({', '.join(acts)[:80]}) without a Condition",
"Restrict Principal to known ARNs or add aws:SourceArn / aws:PrincipalOrgID / aws:SourceVpce conditions; use CloudFront OAC for public sites."))
if s.get("NotAction"):
out.append(finding("MEDIUM", "IAM_NOT_ACTION", addr, "Allow with NotAction grants everything except the listed actions", "List the allowed actions explicitly."))
if "*" in acts and "*" in res:
out.append(finding("HIGH", "IAM_ADMIN", addr, "Allow Action * on Resource * (full admin)", "Grant only the actions and resources this principal needs."))
continue
esc = sorted({o for o, x in zip(orig, acts) if x in ESCALATION_ACTIONS and x != "*" and ("*" in res or x in ("iam:*", "sts:*"))})
if esc:
out.append(finding("HIGH", "IAM_ESCALATION", addr, f"{', '.join(esc)} on {', '.join(res) or '*'} lets the holder gain more privileges",
"Scope iam:PassRole and sts:AssumeRole to specific role ARNs (and iam:PassedToService); avoid iam:* and kms:* wildcards."))
wild = sorted({o for o, x in zip(orig, acts) if x.endswith(":*") and x not in ESCALATION_ACTIONS})
if wild:
sev = "HIGH" if "*" in res else "MEDIUM"
out.append(finding(sev, "IAM_WILDCARD", addr, f"service wildcard {', '.join(wild)} on {', '.join(res)}",
"Replace with the specific actions used (check IAM Access Analyzer or CloudTrail for what is actually called)."))
if b is not None:
added = sorted({x[0] + (" on " + x[1] if x[1] not in ("*", "(none)") else " on *") for x in allow_actions(a) - allow_actions(b)})
if added:
out.append(finding("LOW", "IAM_WIDENED", addr, "policy grants new actions/resources: " + ", ".join(added[:8]) + (" ..." if len(added) > 8 else ""),
"Confirm the new permissions are needed; least privilege."))
return out
def review_change(rc):
out = []
addr, rtype = rc.get("address", "?"), rc.get("type", "")
ch = rc.get("change") or {}
actions = ch.get("actions") or []
kind = kind_of(actions)
before, after = ch.get("before") or {}, ch.get("after") or {}
unknown = ch.get("after_unknown") or {}
reason = rc.get("action_reason", "")
if rc.get("mode") == "data" or kind in ("no-op", "read"):
return kind, out
why = ""
if ch.get("replace_paths"):
why = " (forced by " + ", ".join(".".join(map(str, p)) for p in ch["replace_paths"]) + ")"
elif reason:
why = f" ({reason.replace('_', ' ')})"
stateful = bool(STATEFUL.match(rtype))
if kind == "forget":
out.append(finding("INFO", "FORGET", addr, "removed from state but not destroyed (removed block)", "Make sure another configuration or team takes ownership of it."))
if kind == "destroy" or kind.startswith("replace"):
if stateful:
extra = "; force_destroy = true, so everything in it is deleted too" if get(before, "force_destroy") is True else ""
out.append(finding("HIGH", "DATA_LOSS", addr, f"{rtype} will be {'destroyed' if kind == 'destroy' else 'replaced, ' + kind[9:-1]}{why}; its data does not carry over{extra}",
"Back up or snapshot first; if this is a rename/refactor add a `moved` block or `terraform state mv`; add lifecycle prevent_destroy for data stores."))
elif SECRET_GEN.match(rtype) and kind.startswith("replace"):
out.append(finding("MEDIUM", "SECRET_REGENERATED", addr, f"{rtype} will be regenerated{why}; everything using the old value breaks",
"Check what consumes it (database password, keys) and plan the rotation."))
elif kind == "destroy":
sev = "MEDIUM" if DOWNTIME.match(rtype) or reason in ("delete_because_count_index", "delete_because_each_key") else "LOW"
out.append(finding(sev, "DESTROY", addr, f"will be destroyed{why}",
"Confirm it is intended; for a rename/refactor use a `moved` block instead of destroy + create."))
else:
sev = "MEDIUM" if kind == "replace (destroy first)" and DOWNTIME.match(rtype) else "LOW"
out.append(finding(sev, "REPLACE", addr, f"{kind}{why}",
"Expect a new ID/IP/DNS name; use create_before_destroy where possible and check dependents."))
if reason in ("delete_because_count_index",):
out.append(finding("MEDIUM", "COUNT_INDEX_SHIFT", addr, "destroyed because a count index moved (an item was removed from the middle of a list)",
"Switch to for_each with stable keys, or add moved blocks for the shifted indexes."))
if reason == "delete_because_no_resource_config":
out.append(finding("INFO", "REMOVED_FROM_CONFIG", addr, "resource no longer in configuration", "If it moved to another module or address, add a `moved` block; to keep it but stop managing it, use a `removed` block with destroy = false."))
if kind in ("create", "update") or kind.startswith("replace"):
bm, am = ch.get("before_sensitive") or {}, ch.get("after_sensitive") or {}
for attr in PROTECTION_ATTRS:
if get(after, attr) is False and (kind != "update" or get(before, attr) is True):
out.append(finding("HIGH" if kind == "update" else "MEDIUM", "PROTECTION_OFF", addr, f"{attr} {'turned off' if kind == 'update' else 'is false'}",
f"Keep {attr} = true for production resources; turn it off only in a separate, reviewed change right before a planned delete."))
if get(after, "skip_final_snapshot") is True and rtype in ("aws_db_instance", "aws_rds_cluster", "aws_docdb_cluster", "aws_neptune_cluster", "aws_redshift_cluster"):
if kind != "update" or get(before, "skip_final_snapshot") is not True:
out.append(finding("MEDIUM", "NO_FINAL_SNAPSHOT", addr, "skip_final_snapshot = true: a delete leaves no snapshot",
"Set skip_final_snapshot = false with a final_snapshot_identifier."))
if get(after, "force_destroy") is True and (kind != "update" or get(before, "force_destroy") is not True):
out.append(finding("MEDIUM", "FORCE_DESTROY", addr, "force_destroy = true lets Terraform delete the bucket/zone with everything in it",
"Keep force_destroy = false on buckets and zones that hold real data."))
for attr in ("storage_encrypted", "encrypted", "server_side_encryption"):
if get(after, attr) is False and (kind != "update" or get(before, attr) is True):
out.append(finding("MEDIUM", "ENCRYPTION_OFF", addr, f"{attr} = false", "Enable encryption at rest (it usually forces replacement later, so do it now)."))
if get(after, "backup_retention_period") == 0 and get(before, "backup_retention_period", 1) != 0:
out.append(finding("MEDIUM", "BACKUPS_OFF", addr, "backup_retention_period = 0 disables automated backups", "Keep at least 7 days for production databases."))
if get(after, "publicly_accessible") is True and get(before, "publicly_accessible") is not True:
out.append(finding("HIGH", "PUBLIC_DATABASE", addr, "publicly_accessible = true gives the database a public endpoint",
"Keep databases private; connect through a bastion, VPN, SSM or RDS Proxy."))
if rtype == "aws_s3_bucket_public_access_block":
off = [k for k in ("block_public_acls", "block_public_policy", "ignore_public_acls", "restrict_public_buckets")
if get(after, k) is False and (kind != "update" or get(before, k) is not False)]
if off:
out.append(finding("HIGH", "S3_PUBLIC_ACCESS", addr, "S3 public access block turned off: " + ", ".join(off),
"Keep all four settings true; serve public content through CloudFront with Origin Access Control."))
if rtype in ("aws_s3_bucket_acl", "aws_s3_object") and get(after, "acl") in ("public-read", "public-read-write", "authenticated-read"):
out.append(finding("HIGH", "PUBLIC_ACL", addr, f"acl = {after['acl']}", "Use private ACLs (BucketOwnerEnforced) and CloudFront for public files."))
if rtype.startswith("google_") and "iam" in rtype:
members = as_list(get(after, "member")) + as_list(get(after, "members"))
if any(m in ("allUsers", "allAuthenticatedUsers") for m in members):
out.append(finding("HIGH", "PUBLIC_IAM", addr, "grants a role to allUsers/allAuthenticatedUsers", "Grant to specific users, groups or service accounts."))
if get(after, "role") in ("roles/owner", "roles/editor", "roles/iam.securityAdmin"):
out.append(finding("HIGH", "IAM_ADMIN", addr, f"grants {after['role']}", "Use a narrower predefined or custom role."))
if rtype == "azurerm_role_assignment" and get(after, "role_definition_name") in ("Owner", "User Access Administrator", "Contributor"):
sev = "MEDIUM" if after["role_definition_name"] == "Contributor" else "HIGH"
out.append(finding(sev, "IAM_ADMIN", addr, f"assigns {after['role_definition_name']}", "Use the narrowest built-in role at the smallest scope."))
if rtype.startswith("aws_iam_") and rtype.endswith("policy_attachment"):
arn = get(after, "policy_arn") or ""
if ADMIN_POLICIES.search(arn) and get(before, "policy_arn") != arn:
out.append(finding("HIGH", "IAM_ADMIN", addr, f"attaches {arn.split('/')[-1]}", "Attach a least-privilege policy instead; keep admin roles for break-glass use with MFA."))
elif arn.endswith("FullAccess") and get(before, "policy_arn") != arn:
out.append(finding("MEDIUM", "IAM_WILDCARD", addr, f"attaches {arn.split('/')[-1]}", "Prefer a scoped customer-managed policy."))
if rtype == "aws_lambda_function_url" and get(after, "authorization_type") == "NONE":
out.append(finding("MEDIUM", "PUBLIC_FUNCTION_URL", addr, "Lambda function URL with authorization_type NONE is public", "Use AWS_IAM auth or validate requests in the function."))
new_open = open_rules(rtype, after) - (open_rules(rtype, before) if kind == "update" else set())
for cidr, lo, hi, proto in sorted(new_open, key=lambda x: (x[1], x[2])):
label = port_label(lo, hi, proto)
if proto == "all" or (lo == 0 and hi == 65535) or any(lo <= p <= hi for p in SENSITIVE_PORTS):
sev = "HIGH"
elif lo in WEB_PORTS and hi == lo:
sev = "INFO"
else:
sev = "MEDIUM"
out.append(finding(sev, "PUBLIC_INGRESS", addr, f"new ingress from {cidr} on {label}",
"Restrict the source to known CIDRs or a load balancer security group; reach admin ports through SSM, VPN or a bastion." if sev != "INFO" else "Expected for a public web endpoint; make sure only the load balancer is exposed."))
for attr in POLICY_ATTRS:
if attr in after or get(unknown, attr):
if sensitive(am, attr):
continue
out += check_policy(addr, attr, get(before, attr), get(after, attr), get(unknown, attr) is True)
return kind, out
def review_json(plan):
if not isinstance(plan, dict) or "format_version" not in plan:
raise ValueError("not a terraform show -json document (no format_version)")
changes, findings = [], []
for rc in plan.get("resource_changes") or []:
kind, f = review_change(rc)
if kind not in ("no-op", "read") and rc.get("mode") != "data":
changes.append((kind, rc.get("address", "?")))
findings += f
if (rc.get("change") or {}).get("importing"):
findings.append(finding("INFO", "IMPORT", rc.get("address", "?"), "will be imported", "Check the plan shows no further changes after import."))
if rc.get("previous_address"):
findings.append(finding("INFO", "MOVED", rc.get("address", "?"), f"moved from {rc['previous_address']}", "No action; moved blocks avoid destroy + create."))
drift = [d.get("address", "?") for d in plan.get("resource_drift") or []]
if drift:
findings.append(finding("INFO", "DRIFT", ", ".join(drift[:5]) + (" ..." if len(drift) > 5 else ""),
f"{len(drift)} resource(s) changed outside Terraform", "Find out who changed them; the plan may revert manual fixes."))
if plan.get("errored"):
findings.append(finding("HIGH", "PLAN_ERRORED", "-", "the plan errored", "Fix the errors and re-plan before applying anything."))
elif plan.get("complete") is False:
findings.append(finding("MEDIUM", "PLAN_INCOMPLETE", "-", "plan is not complete (deferred or -target changes)", "Run a full plan after this apply."))
return changes, findings, plan.get("terraform_version", "?")
TEXT_RE = re.compile(r"^\s*# (\S+) (will be created|will be destroyed|will be updated in-place|must be replaced|will be read during apply|will no longer be managed by Terraform)")
def review_text(text):
text = re.sub(r"\x1b\[[0-9;]*m", "", text)
lines = text.splitlines()
changes, findings = [], []
i = 0
while i < len(lines):
m = TEXT_RE.match(lines[i])
if not m:
i += 1; continue
addr, verb = m.group(1), m.group(2)
rtype = re.sub(r"^(module\.[^.]+\.)*", "", addr).split(".")[0]
if addr.startswith("data.") or ".data." in addr or "read during apply" in verb:
i += 1; continue
block, j = [], i + 1
while j < len(lines) and not TEXT_RE.match(lines[j]) and not lines[j].startswith("Plan:"):
block.append(lines[j]); j += 1
first = next((l.strip() for l in block if l.strip() and not l.strip().startswith("#")), "")
reason = next((l.strip()[3:-1] for l in block[:3] if l.strip().startswith("# (")), "")
kind = {"will be created": "create", "will be destroyed": "destroy", "will be updated in-place": "update",
"will no longer be managed by Terraform": "forget"}.get(verb)
if verb == "must be replaced":
kind = "replace (create first)" if first.startswith("+/-") else "replace (destroy first)"
forced = [re.sub(r"^[~+\-/ ]+", "", l.strip()).split(" ")[0] for l in block if "# forces replacement" in l]
rc = {"address": addr, "type": rtype, "change": {"actions": {"create": ["create"], "update": ["update"], "destroy": ["delete"], "forget": ["forget"],
"replace (create first)": ["create", "delete"], "replace (destroy first)": ["delete", "create"]}[kind],
"replace_paths": [[f] for f in forced]}}
if "out of range for count" in reason or "count index" in reason:
rc["action_reason"] = "delete_because_count_index"
elif "not in for_each map" in reason:
rc["action_reason"] = "delete_because_each_key"
elif "not in configuration" in reason:
rc["action_reason"] = "delete_because_no_resource_config"
k, f = review_change(rc)
changes.append((k, addr))
findings += f
i = j
if not changes and "No changes." not in text:
raise ValueError("no resource changes found; is this terraform plan output?")
findings.append(finding("INFO", "TEXT_MODE", "-", "text plan: only actions were checked, not attribute values (IAM, ingress, protection flags)",
"Run `terraform show -json plan.out > plan.json` and review the JSON for full checks."))
return changes, findings, "version unknown (text plan)"
def summarize(changes, findings):
counts = {}
for k, _ in changes:
key = "replace" if k.startswith("replace") else k
counts[key] = counts.get(key, 0) + 1
findings.sort(key=lambda f: (SEV_ORDER[f["severity"]], f["resource"]))
sev = {s: sum(1 for f in findings if f["severity"] == s) for s in SEV_ORDER}
if sev["HIGH"]:
verdict = "DO NOT APPLY as is: resolve or explicitly accept every HIGH finding"
elif sev["MEDIUM"]:
verdict = "Apply after review: MEDIUM findings need an owner's OK"
else:
verdict = "Low risk"
return counts, sev, verdict
def render(path, version, changes, findings):
counts, sev, verdict = summarize(changes, findings)
out = [f"# Terraform plan risk review: {path}", "",
f"Terraform {version}. Changes: " + ", ".join(f"{counts.get(k, 0)} {k}" for k in ("create", "update", "replace", "destroy")) +
(f", {counts['forget']} forget" if counts.get("forget") else ""),
f"Findings: {sev['HIGH']} HIGH, {sev['MEDIUM']} MEDIUM, {sev['LOW']} LOW, {sev['INFO']} INFO",
f"Verdict: {verdict}", "", "## Findings", ""]
if findings:
out += ["| Severity | Code | Resource | Problem | What to do |", "|---|---|---|---|---|"]
for f in findings:
out.append(f"| {f['severity']} | {f['code']} | `{f['resource']}` | {f['problem']} | {f['fix']} |")
else:
out.append("No findings.")
out += ["", "## All changes", "", "| Action | Resource |", "|---|---|"]
order = {"destroy": 0, "replace (destroy first)": 1, "replace (create first)": 2, "update": 3, "create": 4, "forget": 5}
for k, a in sorted(changes, key=lambda x: (order.get(x[0], 9), x[1])):
out.append(f"| {k} | `{a}` |")
out += ["", "Plan JSON can contain secrets in plain text: do not paste it into tickets or chats; share this summary instead."]
return "\n".join(out)
def self_test():
cases = []
def t(name, cond):
cases.append((name, bool(cond)))
def codes(rc):
return {f["code"]: f["severity"] for f in review_change(rc)[1]}
def rc(rtype, actions, before=None, after=None, **kw):
d = {"address": f"{rtype}.x", "mode": "managed", "type": rtype, "change": {"actions": actions, "before": before, "after": after, **kw.pop("change", {})}}
d.update(kw)
return d
t("kind names", kind_of(["delete", "create"]) == "replace (destroy first)" and kind_of(["create", "delete"]) == "replace (create first)" and kind_of(["delete"]) == "destroy")
t("db destroy = HIGH DATA_LOSS", codes(rc("aws_db_instance", ["delete"], {"id": "a"}, None)).get("DATA_LOSS") == "HIGH")
t("bucket replace = HIGH DATA_LOSS", codes(rc("aws_s3_bucket", ["create", "delete"], {}, {})).get("DATA_LOSS") == "HIGH")
t("stateless destroy LOW", codes(rc("aws_iam_role", ["delete"], {}, None)).get("DESTROY") == "LOW")
t("instance destroy-first replace MEDIUM", codes(rc("aws_instance", ["delete", "create"], {}, {})).get("REPLACE") == "MEDIUM")
t("create-first replace LOW", codes(rc("aws_lb_target_group", ["create", "delete"], {}, {})).get("REPLACE") == "LOW")
t("replace_paths shown", "forced by engine" in review_change(rc("aws_instance", ["delete", "create"], {}, {}, change={"replace_paths": [["engine"]]}))[1][0]["problem"])
t("random_password regenerated", codes(rc("random_password", ["delete", "create"], {}, {})).get("SECRET_REGENERATED") == "MEDIUM")
t("count index shift", "COUNT_INDEX_SHIFT" in codes(rc("aws_instance", ["delete"], {}, None, action_reason="delete_because_count_index")))
t("no-op ignored", review_change(rc("aws_vpc", ["no-op"], {}, {}))[1] == [])
t("deletion_protection turned off HIGH", codes(rc("aws_db_instance", ["update"], {"deletion_protection": True}, {"deletion_protection": False})).get("PROTECTION_OFF") == "HIGH")
t("skip_final_snapshot MEDIUM", "NO_FINAL_SNAPSHOT" in codes(rc("aws_db_instance", ["create"], None, {"skip_final_snapshot": True})))
t("force_destroy MEDIUM", "FORCE_DESTROY" in codes(rc("aws_s3_bucket", ["update"], {"force_destroy": False}, {"force_destroy": True})))
t("unchanged force_destroy not re-flagged", "FORCE_DESTROY" not in codes(rc("aws_s3_bucket", ["update"], {"force_destroy": True}, {"force_destroy": True})))
t("encryption off", "ENCRYPTION_OFF" in codes(rc("aws_ebs_volume", ["create"], None, {"encrypted": False})))
t("publicly_accessible HIGH", codes(rc("aws_db_instance", ["update"], {"publicly_accessible": False}, {"publicly_accessible": True})).get("PUBLIC_DATABASE") == "HIGH")
sg_b = {"ingress": [{"cidr_blocks": ["10.0.0.0/8"], "from_port": 22, "to_port": 22, "protocol": "tcp"}]}
sg_a = {"ingress": sg_b["ingress"] + [{"cidr_blocks": ["0.0.0.0/0"], "from_port": 22, "to_port": 22, "protocol": "tcp"}]}
t("new SSH from 0.0.0.0/0 HIGH", codes(rc("aws_security_group", ["update"], sg_b, sg_a)).get("PUBLIC_INGRESS") == "HIGH")
t("existing open rule not re-flagged", "PUBLIC_INGRESS" not in codes(rc("aws_security_group", ["update"], sg_a, sg_a)))
t("443 from internet INFO", codes(rc("aws_vpc_security_group_ingress_rule", ["create"], None, {"cidr_ipv4": "0.0.0.0/0", "from_port": 443, "to_port": 443, "ip_protocol": "tcp"})).get("PUBLIC_INGRESS") == "INFO")
t("all protocols HIGH", codes(rc("aws_security_group_rule", ["create"], None, {"type": "ingress", "cidr_blocks": ["0.0.0.0/0"], "from_port": 0, "to_port": 0, "protocol": "-1"})).get("PUBLIC_INGRESS") == "HIGH")
t("ipv6 ::/0 8080 MEDIUM", codes(rc("aws_security_group_rule", ["create"], None, {"type": "ingress", "ipv6_cidr_blocks": ["::/0"], "from_port": 8080, "to_port": 8080, "protocol": "tcp"})).get("PUBLIC_INGRESS") == "MEDIUM")
t("gcp firewall 3389", codes(rc("google_compute_firewall", ["create"], None, {"direction": "INGRESS", "source_ranges": ["0.0.0.0/0"], "allow": [{"protocol": "tcp", "ports": ["3389"]}]})).get("PUBLIC_INGRESS") == "HIGH")
t("azure nsg * HIGH", codes(rc("azurerm_network_security_rule", ["create"], None, {"direction": "Inbound", "access": "Allow", "source_address_prefix": "*", "destination_port_range": "*", "protocol": "Tcp"})).get("PUBLIC_INGRESS") == "HIGH")
t("S3 public access block off", codes(rc("aws_s3_bucket_public_access_block", ["update"], {"block_public_policy": True}, {"block_public_policy": False})).get("S3_PUBLIC_ACCESS") == "HIGH")
t("public-read ACL", "PUBLIC_ACL" in codes(rc("aws_s3_bucket_acl", ["create"], None, {"acl": "public-read"})))
pol = lambda *st: json.dumps({"Version": "2012-10-17", "Statement": list(st)})
t("admin policy HIGH", codes(rc("aws_iam_policy", ["create"], None, {"policy": pol({"Effect": "Allow", "Action": "*", "Resource": "*"})})).get("IAM_ADMIN") == "HIGH")
t("PassRole on * HIGH", codes(rc("aws_iam_role_policy", ["create"], None, {"policy": pol({"Effect": "Allow", "Action": ["iam:PassRole"], "Resource": "*"})})).get("IAM_ESCALATION") == "HIGH")
t("s3:* on bucket MEDIUM", codes(rc("aws_iam_role_policy", ["create"], None, {"policy": pol({"Effect": "Allow", "Action": "s3:*", "Resource": "arn:aws:s3:::b/*"})})).get("IAM_WILDCARD") == "MEDIUM")
t("IAM_WIDENED lists new actions", "s3:DeleteObject on arn:aws:s3:::b/*" in next(f["problem"] for f in review_change(rc("aws_iam_role_policy", ["update"],
{"policy": pol({"Effect": "Allow", "Action": "s3:GetObject", "Resource": "arn:aws:s3:::b/*"})},
{"policy": pol({"Effect": "Allow", "Action": ["s3:GetObject", "s3:DeleteObject"], "Resource": "arn:aws:s3:::b/*"})}))[1] if f["code"] == "IAM_WIDENED"))
t("Deny statements ignored", "IAM_ADMIN" not in codes(rc("aws_iam_policy", ["create"], None, {"policy": pol({"Effect": "Deny", "Action": "*", "Resource": "*"})})))
t("trust anyone HIGH", codes(rc("aws_iam_role", ["create"], None, {"assume_role_policy": pol({"Effect": "Allow", "Principal": {"AWS": "*"}, "Action": "sts:AssumeRole"})})).get("TRUST_ANYONE") == "HIGH")
t("trust with condition ok", "TRUST_ANYONE" not in codes(rc("aws_iam_role", ["create"], None, {"assume_role_policy": pol({"Effect": "Allow", "Principal": {"AWS": "*"}, "Action": "sts:AssumeRole", "Condition": {"StringEquals": {"aws:PrincipalOrgID": "o-1"}}})})))
t("bucket policy Principal * HIGH", codes(rc("aws_s3_bucket_policy", ["create"], None, {"policy": pol({"Effect": "Allow", "Principal": "*", "Action": "s3:GetObject", "Resource": "arn:aws:s3:::b/*"})})).get("PUBLIC_POLICY") == "HIGH")
t("unknown policy INFO", "POLICY_UNKNOWN" in codes(rc("aws_iam_policy", ["create"], None, {}, change={"after_unknown": {"policy": True}})))
t("sensitive policy skipped", "IAM_ADMIN" not in codes(rc("aws_iam_policy", ["create"], None, {"policy": pol({"Effect": "Allow", "Action": "*", "Resource": "*"})}, change={"after_sensitive": {"policy": True}})))
t("AdministratorAccess attachment HIGH", codes(rc("aws_iam_role_policy_attachment", ["create"], None, {"policy_arn": "arn:aws:iam::aws:policy/AdministratorAccess"})).get("IAM_ADMIN") == "HIGH")
t("gcp allUsers HIGH", "PUBLIC_IAM" in codes(rc("google_storage_bucket_iam_member", ["create"], None, {"member": "allUsers", "role": "roles/storage.objectViewer"})))
t("not a plan rejected", raises(lambda: review_json({"foo": 1})))
ch, fs, _ = review_json({"format_version": "1.2", "resource_changes": [rc("aws_db_instance", ["delete"], {}, None)], "resource_drift": [{"address": "aws_lb.a"}], "errored": False, "complete": True})
t("json review with drift", ch == [("destroy", "aws_db_instance.x")] and {"DATA_LOSS", "DRIFT"} <= {f["code"] for f in fs})
txt = """ # aws_db_instance.main must be replaced
-/+ resource "aws_db_instance" "main" {
~ engine = "postgres" -> "mysql" # forces replacement
}
# aws_instance.web[1] will be destroyed
# (because index [1] is out of range for count)
- resource "aws_instance" "web" {
}
# aws_lb_target_group.a must be replaced
+/- resource "aws_lb_target_group" "a" {
}
Plan: 2 to add, 0 to change, 3 to destroy.
"""
ch, fs, _ = review_text(txt)
c = {f["code"] for f in fs}
t("text mode actions", ch == [("replace (destroy first)", "aws_db_instance.main"), ("destroy", "aws_instance.web[1]"), ("replace (create first)", "aws_lb_target_group.a")])
t("text mode findings", {"DATA_LOSS", "DESTROY", "REPLACE", "TEXT_MODE", "COUNT_INDEX_SHIFT"} <= c and "forced by engine" in next(f["problem"] for f in fs if f["code"] == "DATA_LOSS"))
t("text mode rejects junk", raises(lambda: review_text("hello")))
passed = sum(ok for _, ok in cases)
for name, ok in cases:
print(("PASS " if ok else "FAIL ") + name)
print(f"{passed}/{len(cases)} passed")
return 0 if passed == len(cases) else 1
def raises(fn):
try:
fn()
except ValueError:
return True
return False
def main():
ap = argparse.ArgumentParser(description=__doc__, formatter_class=argparse.RawDescriptionHelpFormatter)
ap.add_argument("plan", nargs="?", help="plan JSON (terraform show -json) or plan text (terraform plan -no-color)")
ap.add_argument("--json", action="store_true")
ap.add_argument("--self-test", action="store_true")
a = ap.parse_args()
if a.self_test:
return self_test()
if not a.plan:
ap.print_usage(sys.stderr); return 2
try:
raw = open(a.plan, encoding="utf-8").read()
if raw.lstrip().startswith("{"):
changes, findings, version = review_json(json.loads(raw))
else:
changes, findings, version = review_text(raw)
except (OSError, UnicodeDecodeError, ValueError) as e:
print(f"error: {e}", file=sys.stderr); return 2
counts, sev, verdict = summarize(changes, findings)
if a.json:
print(json.dumps({"terraform_version": version, "counts": counts, "severity": sev, "verdict": verdict,
"findings": findings, "changes": [{"action": k, "address": x} for k, x in changes]}, indent=2))
else:
print(render(a.plan, version, changes, findings))
return 1 if sev["HIGH"] else 0
if __name__ == "__main__":
sys.exit(main())Opinionated conventions for building reliable background job queues and workers.
# Background Jobs taste of a backend reliability engineer
- Make every job idempotent so a retry or duplicate delivery never charges a card or sends an email twice. Confidence: 0.95
- Pass IDs in the job payload and load fresh data inside the worker instead of serializing whole records. Confidence: 0.90
- Enqueue jobs in the same database transaction as the write that triggers them, using an outbox table or a Postgres-backed queue. Confidence: 0.85
- Prefer a boring, well-supported queue such as Sidekiq, BullMQ, Celery or a Postgres queue like Graphile Worker over a home-grown one. Confidence: 0.80
- Retry with exponential backoff and jitter, and cap attempts so poison jobs end up in a dead letter queue. Confidence: 0.95
- Classify errors as retryable or permanent and fail permanent ones immediately instead of burning retries. Confidence: 0.85
- Set an explicit timeout on every job and on every network call it makes. Confidence: 0.90
- Keep jobs small and short, and split long batch work into chunks that can resume from a checkpoint. Confidence: 0.85
- Use separate queues for latency-sensitive and bulk work so a backfill never delays password reset emails. Confidence: 0.90
- Rate limit jobs that call third-party APIs per provider, not per worker process. Confidence: 0.80
- Use unique job keys or locks to prevent the same scheduled job from running twice at once. Confidence: 0.85
- Run cron-style schedules from one scheduler with leader election, never from every app instance. Confidence: 0.80
- Version job payloads and keep workers able to read the previous version during deploys. Confidence: 0.80
- Handle SIGTERM gracefully: stop taking new jobs, finish or requeue the current one, then exit. Confidence: 0.90
- Log a job ID, attempt number and correlation ID on every log line from a job. Confidence: 0.85
- Alert on queue depth, oldest job age and dead letter growth, not just on worker crashes. Confidence: 0.90
- Give the dead letter queue an owner and a documented replay command. Confidence: 0.75
- Test jobs by calling the handler directly in unit tests and run one end-to-end test through the real queue in CI. Confidence: 0.80
- Avoid chaining many jobs into hidden workflows; reach for a workflow engine like Temporal when steps need orchestration. Confidence: 0.70
- Store job results and side-effect markers in the database, not only in the queue backend. Confidence: 0.75
Opinionated conventions for building maintainable Vue 3 apps with TypeScript and the Composition API.
# Vue App taste of a frontend engineer
- Start new projects with Vite and Vue 3, or Nuxt when server rendering or file-based routing is needed. Confidence: 0.90
- Write components with script setup and the Composition API, not the Options API. Confidence: 0.90
- Use TypeScript everywhere and check templates with vue-tsc in CI. Confidence: 0.90
- Type props and emits with defineProps and defineEmits generics instead of runtime-only declarations. Confidence: 0.85
- Use Pinia for shared client state and keep stores small and focused on one domain. Confidence: 0.85
- Fetch server data with TanStack Query for Vue or Nuxt useFetch instead of hand-rolled loading flags in stores. Confidence: 0.80
- Extract reusable logic into composables named useSomething that return refs and functions. Confidence: 0.90
- Reach for VueUse before writing a custom composable for common browser APIs. Confidence: 0.75
- Prefer computed over watch, and use watch only for side effects. Confidence: 0.90
- Never mutate props; emit events or use defineModel for two-way binding. Confidence: 0.95
- Always give v-for items a stable key from the data, never the index. Confidence: 0.90
- Never combine v-if and v-for on the same element. Confidence: 0.90
- Keep components under about 200 lines and split them when the template gets hard to scan. Confidence: 0.70
- Use multi-word PascalCase component names and colocate components by feature, not by type. Confidence: 0.80
- Style with scoped CSS or Tailwind, and avoid global styles beyond a small reset and design tokens. Confidence: 0.75
- Lazy load route components with dynamic imports in Vue Router. Confidence: 0.85
- Test components with Vitest and Vue Testing Library, querying by role and text. Confidence: 0.85
- Lint with ESLint and eslint-plugin-vue using the recommended rules, and format with Prettier. Confidence: 0.85
- Avoid provide and inject for app state; use it only for component library internals and deep config. Confidence: 0.70
- Sanitize any HTML before using v-html, or better, avoid v-html altogether. Confidence: 0.95
Opinionated conventions for building secure cross-platform desktop apps with Tauri and Rust.
# Tauri Desktop App taste of a cross-platform desktop developer
- Choose Tauri over Electron for new desktop apps when bundle size and memory use matter. Confidence: 0.80
- Build the frontend with Vite and TypeScript in strict mode, and keep it framework-agnostic from the Rust side. Confidence: 0.85
- Keep business logic that touches the file system, network or OS in Rust commands, and keep the web layer focused on UI. Confidence: 0.85
- Enable only the capabilities and permissions each window needs, and never ship a wildcard allowlist. Confidence: 0.95
- Set a strict Content Security Policy and never load remote content into a window that can call commands. Confidence: 0.95
- Generate TypeScript bindings for commands with tauri-specta or ts-rs so frontend and Rust types cannot drift. Confidence: 0.80
- Return structured errors from commands with thiserror and serde instead of plain strings. Confidence: 0.85
- Run slow work in async commands or background tasks and report progress through events, never blocking the main thread. Confidence: 0.90
- Store user settings with the official store plugin and secrets in the OS keychain, not in plain JSON files. Confidence: 0.90
- Use SQLite through sqlx or the SQL plugin for local data, with migrations checked into the repo. Confidence: 0.80
- Resolve paths with the path API for app data and config folders instead of hardcoding locations. Confidence: 0.90
- Ship automatic updates with the updater plugin and signed release artifacts. Confidence: 0.85
- Sign and notarize macOS builds and sign Windows installers from CI, never from a developer laptop. Confidence: 0.90
- Build every platform in GitHub Actions with the tauri-action matrix on each release tag. Confidence: 0.80
- Test the UI on WebKit, WebView2 and WebKitGTK, since rendering and APIs differ between them. Confidence: 0.85
- Respect platform conventions for menus, shortcuts and window controls instead of one custom title bar everywhere. Confidence: 0.75
- Unit test Rust commands directly and cover the main flows with WebDriver end-to-end tests. Confidence: 0.70
- Keep the dependency tree small and run cargo audit and npm audit in CI. Confidence: 0.80
- Log to a rotating file in the app log folder and give users a one-click way to export logs for bug reports. Confidence: 0.75
A 30-second, 9:16 photoreal 3D animation of four costumed cats (witch, ghost, skeleton, pumpkin) and an upright Frankenstein tiger dancing in sync in a sunny Halloween village courtyard, scripted in six timed scenes with audio cues and strict character-consistency rules. Trending on X, originally shared by @Just_sharon7: https://x.com/Just_sharon7/status/2113964901446094947
Video Style: Ultra-realistic 3D anthropomorphic animals, adorable Halloween costumes, energetic synchronized dancing, whimsical fantasy atmosphere, vibrant autumn colors, cinematic animation, realistic fur textures, smooth character movements, 9:16 vertical format, 4K quality.

SETTING:

A beautiful Halloween-themed village courtyard during a bright, sunny autumn afternoon. A magnificent Victorian haunted mansion stands in the background, decorated with glowing jack-o'-lanterns, carved pumpkins, hanging lanterns, cobwebs, spooky ornaments, and Halloween decorations. Tall maple trees with brilliant orange, golden-yellow, and crimson-red leaves surround the courtyard. Fallen autumn leaves cover the cobblestone pathway. A vivid blue sky with fluffy white clouds creates a cheerful Halloween atmosphere.

MAIN CHARACTERS:

Four adorable anthropomorphic cats and one large anthropomorphic tiger, all standing upright on their hind legs.

Witch Cat: A fluffy black-and-white cat wearing a pointed black witch hat, a purple witch dress, and a flowing purple cape.

Ghost Cat: An adorable fluffy white cat wearing a flowing white ghost costume with a cute ghost hood and tiny black bow tie.

Skeleton Cat: A fluffy black-and-white cat wearing a black skeleton jumpsuit featuring white bones and a small black Halloween hat.

Pumpkin Cat: A chubby orange tabby cat wearing a bright orange pumpkin costume with a carved jack-o'-lantern face and a small green pumpkin-stem hat.

Frankenstein Tiger: A large, realistic orange-and-black striped tiger standing upright like a human, wearing a green Frankenstein-style monster headpiece, a long dark-green Victorian coat, a purple waistcoat, and dark trousers.

All characters have realistic animal faces, expressive eyes, detailed fluffy fur, and adorable personalities.

SCENE 1 (0–5 seconds): GROUP DANCE INTRO

The camera opens with a wide cinematic shot of the Halloween courtyard.

Four adorable costumed cats stand in the foreground while the giant Frankenstein tiger stands behind them.

All characters begin dancing together to a playful, upbeat Halloween rhythm.

The cats bounce on their hind legs, swing their little paws, wiggle their bodies, and move their heads in perfect synchronization.

The Frankenstein tiger performs exaggerated, funny dance moves behind them.

The camera slowly pushes forward.

SCENE 2 (5–10 seconds): CUTE CAT CLOSE-UPS

A quick transition reveals the fluffy white ghost cat and the black skeleton cat dancing side by side.

Both cats face the camera, raise their front paws near their faces, and perform matching playful paw gestures.

Their costumes bounce naturally as they move.

The ghost cat tilts its head adorably while the skeleton cat gives a confident little pose.

Smooth camera tracking, realistic fur movement, cheerful expressions.

SCENE 3 (10–15 seconds): GROUP DANCE FROM BEHIND

The camera moves behind the dancing cats.

The witch cat's purple cape sways dramatically, the ghost cat's white costume flutters, and the skeleton cat wiggles its hips.

The cats perform synchronized side steps toward the Frankenstein tiger.

The tiger dances enthusiastically in front of the haunted mansion.

Autumn leaves scatter gently across the cobblestones.

SCENE 4 (15–20 seconds): FRANKENSTEIN TIGER SOLO

A medium close-up focuses on the giant Frankenstein tiger.

The tiger performs a hilarious solo dance, crossing its furry arms over its chest, swinging its shoulders, moving its paws rhythmically, and nodding its head.

Its long green coat sways naturally.

The tiger maintains a serious, comical facial expression while dancing.

The camera gently zooms closer, emphasizing the tiger's expressive face and detailed striped fur.

SCENE 5 (20–25 seconds): PUMPKIN CAT TAKES CENTER STAGE

The adorable chubby orange pumpkin cat steps into the center of the courtyard.

It performs a funny bouncing dance, swinging its tiny paws from side to side.

The pumpkin costume jiggles with every movement.

The other cats dance around it while the Frankenstein tiger follows the rhythm in the background.

A quick, playful camera movement emphasizes the energetic choreography.

SCENE 6 (25–30 seconds): FINAL HALLOWEEN DANCE

All five characters gather together for a final synchronized Halloween dance.

The cats perform matching paw waves, little jumps, shoulder movements, and playful head tilts.

The Frankenstein tiger stands behind them, performing exaggerated monster-style dance gestures.

The camera alternates between a wide group shot and a close-up of the tiger.

The video ends with the Frankenstein tiger crossing its furry arms confidently while the cats strike adorable Halloween poses.

CAMERA & VISUAL QUALITY:

Photorealistic 3D animal animation, realistic fluffy fur, expressive animal faces, physically accurate costume movement, cinematic daylight, vibrant autumn colors, natural shadows, detailed Victorian architecture, smooth tracking shots, playful close-ups, energetic choreography, adorable character expressions.

AUDIO:

Upbeat, playful Halloween dance music with a catchy rhythm, funny spooky sound effects, light monster growls, cheerful cat meows, and synchronized dance beats.

IMPORTANT INSTRUCTIONS:

Maintain identical character appearances, costume designs, fur patterns, and proportions throughout every scene. All animals must remain upright on two hind legs while dancing. Dance movements must be smooth, rhythmic, and synchronized. No character morphing, no extra limbs, no costume changes, no distorted faces, no flickering, no text overlays, no subtitles, and no watermarks.
A heartwarming, 9:16 Pixar-inspired 3D animated family short in seven scenes: a curious toddler in striped pajamas meets his newborn sibling in a sunlit home, plays and cuddles a teddy bear, and ends at night with mom kissing the baby's forehead, with style notes and a negative prompt for consistency. Trending on X, originally shared by @Zarnab_with_Ai: https://x.com/Zarnab_with_Ai/status/2114326486870339935
Create a beautiful, ultra-detailed 3D animated family short film featuring a cute toddler boy with fluffy golden-blond hair, big expressive blue eyes, rosy cheeks, and blue-and-white striped pajamas. He interacts lovingly with his newborn baby sibling in a cozy, sunlit modern home.

Scene 1: A warm living room with soft natural sunlight streaming through large windows. A mother gently takes care of household tasks while the curious toddler walks toward the newborn sleeping peacefully in a soft woven bassinet.

Scene 2: Close-up of the toddler carefully leaning over the bassinet, smiling sweetly at the tiny newborn wrapped in a light-blue blanket. The baby moves gently and makes adorable expressions.

Scene 3: The mother places the newborn safely in a wooden crib. The toddler stands beside the crib, looking at the baby with affection and curiosity. Capture the tender sibling bond with cinematic close-ups.

Scene 4: The toddler sits on the floor holding a baby bottle, looking innocent and adorable. Warm sunlight illuminates his face, highlighting his expressive eyes and soft blond hair.

Scene 5: The toddler plays gently with toys beside his baby sibling on a soft living-room rug while their mother watches lovingly from the sofa.

Scene 6: The toddler hugs a cute teddy bear and smiles happily. Use a close-up shot to emphasize his joyful expression and realistic animated details.

Final Scene: At night, the mother sits comfortably on a bed with both children. She lovingly cuddles the newborn while the toddler sits close beside her. End with a tender close-up of the mother kissing her baby's forehead in a peaceful, loving family moment.

Visual Style: High-end Pixar-inspired 3D animation, adorable character design, realistic fabric textures, detailed hair strands, expressive facial animation, soft global illumination, warm cinematic lighting, natural shadows, smooth camera movements, shallow depth of field, emotionally engaging storytelling, consistent character appearance across all scenes, 4K quality, vertical 9:16 aspect ratio.

Negative Prompt: Distorted faces, inconsistent character designs, extra fingers, unnatural movements, flickering, blurry textures, deformed hands, sudden outfit changes, unrealistic proportions, text, logos, and watermarks.
An authentic-looking 1890s cabinet card of three children in handmade Halloween costumes (a witch with a broom, Count Dracula, and a bedsheet ghost) posing solemnly in a Victorian studio among jack-o'-lanterns, cobwebs, a black cat and gothic candleholders, rendered as an aged sepia albumen print on an embossed mount, 3:4. Trending on X, originally shared by @minuitIA: https://x.com/minuitIA/status/2114338847655932352
Authentic Victorian-era Halloween cabinet card photograph, circa 1890, three children posing solemnly in a vintage photography studio, a young girl dressed as a Victorian witch wearing an elaborate black lace dress and pointed hat, holding an old-fashioned wooden broom, a young boy dressed as Count Dracula with an elegant dark cape and high collar, and a mysterious child dressed as a ghost beneath a flowing white sheet with two eyeholes. Surrounded by carved jack-o'-lantern pumpkins, delicate cobwebs, an antique human skeleton, a black cat and gothic candleholders. Elaborate Victorian studio backdrop, theatrical composition, haunting yet charming atmosphere, subtle gothic horror aesthetic, authentic 19th-century clothing and handmade costumes, extremely realistic faces, natural skin textures, serious expressions, aged sepia albumen print, antique photographic grain, subtle fading, scratches, worn paper edges, ornate embossed cardboard mount with decorative typography, historically accurate cabinet card photography, soft diffused studio lighting, exquisite archival details, photorealistic, no modern elements --ar 3:4
Go from knowing only the Moon to finding stars, planets, and constellations on your own: a realistic preview of tonight's sky, a beginner glossary, a before-you-go checklist, your first 30 minutes outside, a star-hopping route, planets and Moon tips, binocular basics, Milky Way and meteor planning, a kid-friendly version, phone photo tips, gear advice, and a 4-week plan.
Act as a Beginner Stargazing Guide. You help complete beginners go from "I only know the Moon" to confidently finding stars, planets, constellations, and the Milky Way on their own, with the eyes and gear they already have. You think like a patient amateur astronomer who runs public star parties: you start with naked-eye skills before equipment, you tie every suggestion to my location, date, and sky conditions, you explain every term the first time you use it, and you are honest about what is realistic to see from a city versus a dark site. You never invent exact rise times, positions, or event dates; when timing matters you tell me how to check it in a free planetarium app or an official source.

My situation:
- Location and sky: a suburb about 30 km from a large city, some light pollution to the south
- Date and time I plan to observe: a weekend evening this month, from about 9 pm to 11 pm
- Equipment I have: just my eyes, a phone, and an old pair of 8x42 binoculars
- What I already know: I can find the Moon and maybe the Big Dipper
- What I want to see: planets, a few bright constellations, the Milky Way, maybe a meteor shower
- Who is coming: my partner and a 9-year-old
- Travel range for a darker sky: up to 1 hour by car
- Weather and season: autumn, nights around 8 C
- Budget for gear: up to 150 for now

First, in one short message, ask me for anything important that is missing: my rough latitude or nearest city, whether my view is blocked in any direction (trees, buildings, streetlights), the Moon phase on my planned night if I know it, whether I wear glasses, and whether anyone in the group has trouble with cold or staying up late. Then guide me through these sections:

1. **Tonight in One Paragraph**: a short, realistic summary of what a beginner can expect to see from my location on my date, and the single best target to start with.

2. **Sky Words You Will Meet**: a short glossary with term and plain meaning: constellation, asterism, magnitude, light pollution, Bortle scale, dark adaptation, averted vision, zenith, horizon, ecliptic, planet versus star (twinkling), Milky Way core, meteor shower radiant, and field of view.

3. **Before You Go Checklist**: how to check the weather and cloud cover, the Moon phase and why a bright Moon washes out faint objects, a light pollution map, and a free planetarium app set to my location; plus what to bring (red light, warm layers, a blanket or reclining chair, hot drink, snacks, a printed or app star chart) and safety basics for a dark site.

4. **Your First 30 Minutes**: a step-by-step routine: arriving, letting eyes adapt for 20 to 30 minutes, red light only, finding north or south, measuring sky distances with an outstretched hand (finger, fist, and spread hand widths), and three easy anchor patterns for my season to start from.

5. **Star-Hopping Route**: a guided route from my anchor pattern to five to eight beginner targets visible in my season, with columns: target, type (star, planet, constellation, cluster, galaxy, nebula), how to find it from the previous one, naked eye or binoculars, and what it will really look like. Mark anything I must confirm in the app for my exact date.

6. **Planets and the Moon**: how to tell a planet from a star, how to check which planets are up tonight, what each bright planet looks like in binoculars, and which Moon phases are best for seeing craters along the terminator line.

7. **Binocular Basics**: how to focus, hold them steady (elbows on knees, leaning on a car or chair), what 8x42 means, and the best binocular targets for my season.

8. **Milky Way and Meteors**: when and where the Milky Way is visible in my season, how dark it must be, how to plan a meteor shower night (radiant, best hours, lying back, patience), and what to confirm in an official calendar.

9. **Kid-Friendly Version**: three short activities that keep a 9-year-old engaged (constellation story, satellite spotting, a simple observing log with drawings), and how long to stay before it stops being fun.

10. **Phone Photos Without Frustration**: realistic expectations for phone night mode, using a small tripod or a steady surface, a timer to avoid shake, and why the Moon is the easiest first photo.

11. **Gear Advice for My Budget**: whether to buy anything now, what to buy first (a planisphere, a red light, a phone clamp for binoculars, a small tripod) and why a cheap telescope is often a poor first purchase; when a small telescope makes sense later.

12. **A 4-Week Learning Plan**: one short evening session per week, each with a goal, two or three targets, and a simple skill to practice, ending with being able to find ten objects on my own.

Rules: label every target as easy, moderate, or hard for my sky; never present a specific time or date as fact without telling me to confirm it for my location; never suggest looking at the Sun with eyes, binoculars, or a phone without certified solar filters; respect private land, park rules, and quiet at shared dark sites; use plain language, short paragraphs, and tables where they help. End with the one target I should look for first tonight and exactly how to find it.
Describe a faulty product or an undelivered service and get a strict JSON plan: a case summary with the remedy to ask for, a timeline, an evidence checklist, deadlines to confirm officially, an escalation ladder from seller support to card disputes and consumer bodies, polite message drafts for each step, a call script, and a follow-up schedule.
1{2 "role": "Calm, organized consumer advocate who helps people get a refund, replacement, or repair for a faulty product or a service that was not delivered as promised, by building a clear evidence file and a polite, escalating plan, without exaggerating, threatening, or giving legal advice",3 "task": "Turn my purchase details, the problem, and what has happened so far into a single strict JSON plan: a case summary with the remedy I should ask for, a timeline of events, an evidence checklist with what I have and what is missing, the deadlines that may apply and must be confirmed, a step-by-step escalation ladder from the seller's own support to card or payment disputes and official consumer bodies, ready-to-send message drafts for each step, a follow-up schedule, and a short call script. Never invent laws, deadlines, policies, case numbers, or facts that I did not give.",4 "context": {5 "item_or_service": "${item:a cordless vacuum cleaner}",6 "seller": "${seller:a large online electronics store}",7 "purchase_date": "${purchase_date:5 weeks ago}",8 "price_paid": "${price:249}",9 "currency": "${currency:EUR}",10 "payment_method": "${payment:credit card}",...+120 more lines
Turn your wedding date, venues, and guest list into a YAML guest logistics plan: RSVP fields and chase plan, guest groups, hotel room blocks, arrivals and shuttle runs, a welcome pack, meal and dietary tracking, seating rules, accessibility and family needs, a communication timeline, a day-of guest flow, contingencies, and task owners.
1role: Warm, detail-minded wedding logistics coordinator who helps couples and their families get every guest invited, housed, transported, seated, fed, and informed on time, so the wedding weekend runs smoothly and nobody is left stranded or confused2task: >3 Turn my wedding details, guest list summary, and venues into a complete guest logistics plan as YAML:4 an RSVP and guest data plan, a guest group breakdown, accommodation and room block steps, travel5 and shuttle schedules, a welcome and information pack outline, meal and dietary tracking, seating6 plan rules, accessibility and family needs, a communication timeline from save-the-dates to the day7 after, a day-of guest flow, and a contingency plan for weather, delays, and no-shows.89inputs:10 wedding_date: ${wedding_date:a Saturday in mid-June}...+112 more lines
Handcrafted origami diorama: about thirty red, gold, and cream paper cranes flying in an arc over a five-tier cream paper pagoda with red-trimmed eaves on a stepped hilltop, pink folded-paper cherry trees, layered faceted paper mountains, and a large flat orange paper sun on a plain grey-beige paper sky.
A handcrafted origami paper art diorama of dozens of folded paper cranes flying in a sweeping arc over a five-tier folded-paper pagoda at sunset, in a wide landscape 16:9 composition. About thirty origami cranes in crimson red, golden yellow, and cream white rise in a gentle curve from the lower left, just beside the sun, up and across to the upper right corner, each with sharp, crisp folds and visible paper grain. In the center, the pagoda stands on a stepped paper base with a small staircase at the top of a hill, built from natural cream paper with five tiers of upturned eaves trimmed in thin red edges, tiny railings, and small windows. A small pink folded-paper cherry blossom tree sits just left of the pagoda base, and a large cherry tree with a twisted brown paper trunk and clusters of pink paper blossoms fills the right foreground. Behind them, layered faceted paper mountains in beige, warm grey, and soft pink (pink on the left) recede in overlapping ridges, with crumpled beige paper hills in the foreground. A large flat orange textured paper circle sun hangs low on the left against a plain light grey-beige paper sky. Soft studio lighting with gentle shadows between the paper layers, shallow depth of field, warm and calm handcrafted mood. No text, no people.
Photoreal long-exposure night shot: an empty yellow sea kayak in the center of a calm tropical bay, electric-blue bioluminescent trails swirling behind it toward the lower left, a dark mangrove shoreline on the left, the Milky Way arching over the upper right, and a few tiny distant lights on the horizon.
A photorealistic night photograph of a single empty yellow sea kayak floating on a calm tropical bay that glows with electric-blue bioluminescent plankton, under the Milky Way, in a wide landscape 16:9 frame. The long yellow kayak sits in the center of the frame, angled toward the upper right, with black round deck hatches, a dark open cockpit, and thin deck lines; no paddle and no person. Behind and around it, bright electric-blue glowing trails swirl and spread across the dark water toward the lower left corner, like light ribbons stirred up by its passage. A dark silhouette of a mangrove tree line runs along the left shore, its tangled roots just above the waterline, tapering into a low horizon near the center. The Milky Way arches across the upper right of the sky with soft dust lanes and a pale glow, over a dense field of tiny stars in deep navy blue. The water is glassy and dark, with faint star reflections and gentle ripples, and a few tiny warm lights twinkle on the far horizon at the right. Long-exposure astrophotography look, wide-angle lens, sharp detail, natural colors, quiet and magical mood. No people, no text.
Medieval illuminated manuscript page on aged vellum: a large blue, red, and gold initial and blocks of illegible blackletter script on the left, a gold-framed miniature of a hooded beekeeper with a smoking stick tending three straw skeps in a walled garden with an apple tree, roses, lilies, and golden bees, inside a gold vine and acanthus border with small snails.
A medieval illuminated manuscript page on aged, stained vellum showing a hooded beekeeper tending three woven straw bee skeps in a walled garden, in a wide landscape 16:9 page view. On the left, a large decorated initial letter at the top left is painted in lapis blue, vermilion red, and burnished gold with small floral patterns inside, followed by short blocks of dense, illegible blackletter-style script in dark brown ink, with the last two lines in red. On the right, a gold-framed miniature painting shows a beekeeper in a long brown hooded robe, face hidden in the hood, bending forward and holding a thin smoking stick toward three dome-shaped straw skeps with small dark entrances, standing on green grass dotted with tiny yellow flowers. Behind him rises a grey crenellated stone garden wall, an apple tree heavy with red-gold apples, pink and red roses, tall white lilies, and spikes of blue delphinium-like flowers, with small golden bees flying in the air. The whole page is surrounded by an ornate border of curling gold vines with blue and red acanthus leaves, and small painted snails sit in the bottom left corner and on the right edge. Flat gothic painting style, fine ink outlines, rich lapis blue, vermilion, and gold palette, gently worn edges. No legible text, no modern elements.
Build an image-ready and motion-ready brief for one hero shot of brick windmills along a straight, calm Dutch polder canal at sunrise: windmills, canal reflections, banks and rowboat, landscape depth, light, fixed details, a motion map, and two prompt seeds: a 16:9 still image and an image-to-video animation.
Act as a cinematic landscape designer who writes image-ready and motion-ready scene briefs. Help me design one hero shot of traditional brick windmills standing along a straight, calm Dutch polder canal at sunrise. The shot will first be generated as a still image and then animated into a short video that uses that image as its first frame. Your brief must make the still image rich in elements that can move naturally (windmill sails turning slowly, mirror reflections shimmering on the canal, reeds swaying at the water's edge, low morning mist over the meadows, the soft sunrise glow) while keeping the composition calm, readable, and easy to animate.

My starting choices:
- Windmills: five round tapered brick windmills with dark caps and wooden lattice sails, standing in a row along one bank
- Canal: a long straight canal with still, mirror-like water receding to a vanishing point
- Banks: grass and reeds on both sides, a narrow dirt path along a grassy dike on the opposite bank
- Foreground detail: a small dark wooden rowboat moored at the water's edge
- Landscape: flat green meadows with low mist and a distant line of trees
- Time and light: sunrise, soft pink, lilac, and gold sky with a warm glow near the horizon
- Visual style: photoreal landscape photography, natural colors
- Mood words: peaceful, quiet, timeless, fresh

First ask me, in one short message, for anything missing: the camera position I prefer (low at the water's edge, standing height on the bank, or slightly elevated), which bank the windmills should stand on, how close the nearest windmill should be, where the sunrise glow should sit, how much mist I want, and anything to avoid (people, cyclists, boats in motion, cars, modern wind turbines, power lines, signs, text, logos, or copying a specific real photograph).

Then produce the brief with these sections:

1. **Scene Overview**: two or three sentences describing the place, the time, the light, and the feeling of the moment. Describe an imagined polder scene in the spirit of the Netherlands, not a copy of a specific photograph or a named landmark.

2. **Windmills**: how many windmills, which bank they stand on, the size of the nearest one in the frame, their brick bodies, caps, small windows, lattice sails and the angle of the sails, the wooden tail or brace structure, and how the low light falls on them.

3. **Canal and Reflections**: the line of the canal toward the vanishing point, how still the water is, which shapes are mirrored, and how the sky colors appear in the water.

4. **Banks and Foreground**: the reeds and grass on each bank, the dike path, the moored rowboat and its rope, and the texture of the closest plants.

5. **Landscape and Depth**: the depth layers from the foreground boat and reeds to the nearest windmill, the receding windmills, the meadows, and the distant tree line, and how mist softens each layer.

6. **Light and Sky**: the position of the sunrise glow, the sky gradient from lilac to pink to gold, the shape of the thin clouds, and how soft the shadows are.

7. **Fixed Visual Details**: a numbered list of 8 to 10 details that must stay identical in the still image and in the video (number and bank of the windmills, nearest windmill position and sail angle, canal line, rowboat position, dike path, horizon line, glow position, cloud layout, camera position, framing).

8. **Motion Map**: a table of every element that can move in the video, with columns: element, type of motion, direction, speed (very slow, slow, medium), and how strongly it should move. Include the sails of each windmill, the reflections, the reeds, the mist, the light, the rowboat, and the camera move. Keep total motion subtle and physically plausible, with one wind direction and all sails turning the same way.

9. **Prompt Seed A - Hero Still Image**: a ready-to-paste image prompt under 170 words for a wide landscape 16:9 frame, with the windmills, the canal, and the sunrise in the first sentence, ending with: no people, no text, no logos.

10. **Prompt Seed B - Image-to-Video Animation**: a ready-to-paste video prompt under 120 words that starts from the hero still as the first frame, describes the sails turning slowly, the reflections shimmering, the reeds swaying, one very slow push-in along the canal for about 6 seconds, and says to keep the windmills, canal, banks, boat, and framing exactly as in the image with no new objects.

Rules: no people, animals that must move convincingly, vehicles, or modern turbines; no text, signs, or logos; no fast camera moves or cuts; and no motion that breaks physics (sails rotate around their hub without changing shape, buildings never move, reflections follow the objects above them, the light does not jump). Use short paragraphs and lists.
Photoreal sunrise landscape: five brick windmills with dark caps and lattice sails in a row along the left bank of a straight, mirror-calm polder canal, the nearest one large on the left with a wooden tail brace, a small wooden rowboat moored lower left, a grassy dike path with reeds on the right, low mist over the meadow, and a pink, lilac, and gold sky. Step 2 of the Dutch Windmill Canal workflow.
Five traditional brick windmills stand in a row along the left bank of a long, straight, calm Dutch polder canal at sunrise, seen from a low viewpoint at the water's edge, in a wide landscape 16:9 frame. The nearest windmill is large in the left third: a round, tapered brown brick body with small windows, a dark cap, and four wooden lattice sails in a tilted X shape, with a long wooden tail and brace poles slanting down to the ground on its left side. The other four windmills recede along the same left bank toward a vanishing point near the center, each smaller and softer in the mist. The canal runs straight into the distance with mirror-like reflections of the windmills and the sky. In the lower left, a small dark wooden rowboat is moored among green reeds, tied with a rope. On the right bank, a grassy dike with tall reeds along the water and a narrow dirt path runs into the distance, beside a flat meadow with low morning mist and a faint distant tree line. The sky glows soft lilac, pink, and gold with thin streaky clouds, brightest near the horizon just right of center. Photoreal landscape photography, wide angle, natural colors, peaceful mood. No people, no text, no logos.
Animate the step 2 Dutch windmill canal image as the first frame into a calm 6-second shot: the nearest windmill's lattice sails turn clearly while the distant sails turn too, the camera pushes slowly along the canal, reflections shimmer, reeds sway, the moored rowboat stays still, and the soft pink and gold sunrise light holds. Step 3 of the Dutch Windmill Canal workflow.
Start from the step 2 image "Five Brick Windmills Along a Misty Dutch Canal at Sunrise" as the exact first frame, and animate it into a calm 6-second cinematic shot. Keep the five brick windmills on the left bank, the large nearest windmill in the left third with its wooden tail brace, the straight canal, the moored rowboat in the lower left, the grassy dike path and reeds on the right bank, the misty meadow, the horizon line, and the composition exactly as in the image. In a gentle breeze, the lattice sails of the nearest windmill turn slowly and clearly around their hub, and the sails of the distant windmills turn too, all in the same direction. The camera makes a very slow, steady push-in along the canal toward the vanishing point. The mirror reflections on the canal shimmer softly, the reeds along both banks sway gently, and the rowboat stays still at its mooring. The light stays a soft pink and gold sunrise glow. Natural, realistic motion, no cuts, no people, no new buildings or objects, no text. Soft sound of a light breeze, creaking sails, and distant birdsong.
Reviews bash and POSIX sh scripts before they run in CI, cron or production. Flags missing strict mode, rm -rf on variables that may be empty, curl piped to a shell, eval, unquoted expansions, unchecked cd, parsing ls, chmod 777, hardcoded secrets, predictable /tmp files, ssh eating a read loop, masked exit codes and bashisms under /bin/sh, then returns a fixed script. Includes a stdlib Python linter with --self-test.
---
name: shell-script-safety-reviewer
description: Reviews bash and POSIX sh scripts before they run in CI, cron or production. Flags missing strict mode, rm -rf on variables that may be empty, curl piped to a shell, eval, unquoted expansions, unchecked cd, parsing ls, chmod 777, hardcoded secrets, predictable /tmp files, ssh eating a read loop, masked exit codes and bashisms under /bin/sh, then returns a fixed script. Includes a stdlib Python linter with --self-test.
---

# Shell Script Safety Reviewer

You review shell scripts the way a careful SRE would before letting them run unattended: deploy scripts, cron jobs, CI steps, installers and Docker entrypoints. You find the lines that can delete the wrong data, leak a secret, run untrusted code or fail silently, explain each one in plain words, and hand back a corrected script that still does the same job.

## Files in this skill

- `scripts/shell_lint.py` - line-based linter for bash and POSIX sh that understands quotes, comments, heredocs, [[ ]], (( )), assignments and case words; prints a findings table with fixes, or JSON (Python 3 standard library only)
- `references/shell-pitfalls.md` - every rule the linter checks: what goes wrong, a minimal failing example and the fix
- `references/safe-patterns.md` - a strict-mode header, safe temp files and cleanup, safe loops over files, argument parsing, secrets, downloads and logging
- `templates/shell-review.md` - the review to hand back
- `examples/deploy.sh` - a realistic deploy script with 20 findings (3 HIGH)
- `examples/deploy-fixed.sh` - the same script after review; lints clean and passes ShellCheck

## Workflow

### 1. Get context
Ask what runs the script (CI, cron, systemd, a human), which shell and OS (bash 5 on Ubuntu, sh on Alpine/busybox, macOS bash 3.2), who can control its inputs (arguments, environment, file names, network data) and whether it runs as root. Ask for the whole script, not a fragment: strict mode and traps live at the top.

### 2. Run the linter
```
python3 scripts/shell_lint.py examples/deploy.sh
python3 scripts/shell_lint.py deploy.sh entrypoint.sh --min-severity MEDIUM
python3 scripts/shell_lint.py install.sh --json --ignore BACKTICKS
python3 scripts/shell_lint.py --self-test
```
Exit 1 means at least one HIGH finding, 2 means a file could not be read. Silence a deliberate line with `# shell-lint: disable=CODE`. If ShellCheck is available, run it too (`shellcheck -f gcc script.sh`) and merge the results; the linter adds checks ShellCheck does not do (secrets, curl | sh, chmod 777, fixed /tmp names, disabled TLS).

### 3. Review by hand
The linter is a first pass. Read the script top to bottom and check what a regex cannot (see `references/shell-pitfalls.md`):
- Which inputs are untrusted, and do they reach rm, eval, ssh, sql or a path?
- Does every destructive step run only after its preconditions (right directory, non-empty variable, confirmed target host)?
- Is it idempotent: can it run twice, or resume after failing halfway?
- Are errors visible: does a failure in a pipe, subshell or function stop the script and leave a clear message?
- Does it clean up temp files, locks and background jobs on exit and on Ctrl+C?

### 4. Fix and deliver
Fill `templates/shell-review.md`: summary verdict, findings table (severity, line, problem, fix), the full fixed script, a diff of the important changes, and how to test it safely (dry run, `bash -n`, a throwaway directory or container, `set -x`). Keep the script's behavior; call out every behavior change.

## Example result
`examples/deploy.sh`: 20 findings, 3 HIGH. A Slack token is hardcoded (HARDCODED_SECRET, rotate it), an installer is piped from curl into sudo bash (CURL_PIPE_SHELL), and `rm -rf $WEB_ROOT/*` wipes `/*` if WEB_ROOT is ever empty (RM_EMPTY_VAR). There is no `set -e`, so a failed `cd $BUILD_DIR` would run the rm and cp in the wrong directory; `ssh` inside the `while read host` loop eats hosts.txt, so only the first host restarts (SSH_STDIN_LOOP); `local count=$(...)` hides failures. `examples/deploy-fixed.sh` fixes all of them and lints clean.

## Rules

- Rank by impact: data loss, code execution and secrets first, then silent failures, then style.
- Quote by default; explain the one place where splitting is intended and use an array there.
- Never suggest `set -e` as the only fix: also check pipes (pipefail), subshells, `local x=$(...)` and `if cmd` contexts where errexit is off.
- Rotate any secret found in a script, even if the repo is private, and say so.
- Prefer the POSIX form when the shebang is /bin/sh; otherwise make the shebang say bash.
- Do not run a reviewed script against real systems to "test" it; use bash -n, a container or a dry-run flag.
FILE:references/shell-pitfalls.md
# Shell pitfalls checked by shell_lint.py

Severity: HIGH = can delete data, run untrusted code or leak a secret. MEDIUM = wrong result or silent failure under realistic input. LOW = fragile or legacy style.

## HIGH

### RM_EMPTY_VAR / RM_ROOT
`rm -rf $DIR/*` becomes `rm -rf /*` when DIR is empty or unset (typo, missing argument, failed command substitution). Steam's Linux client shipped exactly this bug in 2015.
```bash
rm -rf -- "?DIR is empty"/*      # aborts with a message if DIR is empty
```
`set -u` alone does not help when the variable is set to an empty string.

### CURL_PIPE_SHELL
`curl https://x/install.sh | bash` runs whatever the server (or anyone in the middle) sends, and a dropped connection can run half a script. Download to a file, check a pinned SHA-256 or a signature, read it, then run it.

### EVAL_VAR
`eval "$cmd"` executes any `;`, `$(...)` or backticks inside the data. Build commands as arrays: `cmd=(rsync -a -- "$src" "$dst"); "cmd[@]"`. For dispatch, use `case`.

### HARDCODED_SECRET
A literal token, password or key in a script ends up in git history, CI logs (`set -x`) and `ps` output. Read it from the environment or a secret manager and fail early: `TOKEN="?"`. Rotate the exposed value; deleting the line does not remove it from history.

## MEDIUM

### NO_STRICT_MODE / NO_PIPEFAIL
Without `set -e` a failed command is ignored and the next one runs anyway. Without `pipefail`, `build | tee log` succeeds when build fails. Use `set -euo pipefail` in bash and `set -eu` in POSIX sh. Know the gaps: errexit is ignored inside `if`, `while`, `&&`/`||` lists and functions called from them, and `local x=$(cmd)` (see below).

### UNQUOTED_VAR
Unquoted `$var` and `$(cmd)` are split on IFS (spaces, tabs, newlines) and each piece is glob-expanded. `cp $src $dst` with `src="My File.txt"` copies two wrong files; `rm $f` with `f='*'` removes everything. Quote every expansion; use `"$@"` for all arguments and `"arr[@]"` for arrays. Safe without quotes: right side of `x=$y`, inside `[[ ]]` (except the right side of `==`/`=~` where it becomes a pattern), inside `(( ))`, and `case $x in`.

### CD_UNCHECKED
If `cd build` fails, the rest runs in the current directory: `cd build; rm -rf *`. Use `cd -- "$dir" || exit 1` or strict mode. In loops, use a subshell: `(cd -- "$d" && make)`.

### LS_PARSING
`for f in $(ls *.log)` breaks on spaces and newlines and runs the glob twice. Use the glob directly: `for f in ./*.log; do [ -e "$f" ] || continue; ...; done`, or `find . -name '*.log' -print0 | while IFS= read -r -d '' f; do ...; done`.

### CHMOD_777
World-writable files and directories let any local user or compromised service replace code or data. Use 755/644, 700/600 for private data, or `u=rwX,g=rX,o=`.

### PREDICTABLE_TMP / NO_TRAP_CLEANUP (LOW)
A fixed `/tmp/app.log` can be pre-created as a symlink by another user (you then overwrite their target as root) and collides between parallel runs. Use `mktemp`/`mktemp -d` and remove it with `trap '...' EXIT`.

### LOCAL_MASKS_STATUS
`local out=$(cmd)` returns the status of `local` (0), so `set -e` and `$?` never see cmd fail. The same goes for `export` and `readonly`. Declare first, assign on the next line.

### SSH_STDIN_LOOP
`while read host; do ssh "$host" cmd; done < hosts.txt` stops after the first host because ssh reads the rest of stdin. Use `ssh -n` or `< /dev/null`. The same applies to ffmpeg, docker exec -i and anything else that reads stdin.

### TLS_DISABLED
`curl -k`, `wget --no-check-certificate` and `StrictHostKeyChecking=no` turn off the check that you are talking to the right server. Fix the CA bundle, pin the host key in known_hosts, or use `StrictHostKeyChecking=accept-new` only for first contact on trusted networks.

### BASHISM_IN_SH
Under `#!/bin/sh` (dash on Debian/Ubuntu, busybox on Alpine) these fail: `[[ ]]`, `==` in `[ ]`, `function f`, arrays, `source`, `<<<`, `&>`, `$'...'`. Switch the shebang to bash or use `[ ]`, `=`, `.`, and positional parameters.

## LOW

- NO_SHEBANG: the caller's shell runs it; behavior differs between bash, zsh and sh.
- READ_WITHOUT_R: `read` without `-r` eats backslashes; without `IFS=` it trims leading and trailing spaces.
- BACKTICKS: hard to nest and quote; use `$(...)`.

## Not covered by the linter (check by hand)
- Untrusted input reaching sql, ssh or paths (injection, `../` traversal); a leading `-` in file names (use `--`).
- Race conditions on lock files; use `flock`.
- Missing `wait` for background jobs, and orphaned jobs on exit.
- Locale and tool differences (GNU vs BSD sed -i, date -d, readlink -f on macOS).
- Logging secrets with `set -x`; turn xtrace off around secret handling.
FILE:references/safe-patterns.md
# Safe patterns for bash and sh scripts

## Header
```bash
#!/usr/bin/env bash
# What it does, how to call it, what it needs (env vars, tools).
set -euo pipefail
IFS=$'\n\t'                      # optional: no splitting on spaces
readonly SCRIPT_DIR="$(cd -- "$(dirname -- "BASH_SOURCE[0]")" && pwd)"
```
POSIX sh: `set -eu` (pipefail exists in dash 0.5.11+ and busybox, but not everywhere).

## Fail with a message
```bash
die() { printf 'error: %s\n' "$*" >&2; exit 1; }
command -v jq >/dev/null 2>&1 || die "jq is required"
[ -d "$TARGET" ] || die "no such directory: $TARGET"
```

## Arguments
```bash
usage() { echo "usage: $0 [-n] <release>" >&2; exit 2; }
dry_run=0
while getopts ":n" opt; do
  case $opt in
    n) dry_run=1 ;;
    *) usage ;;
  esac
done
shift $((OPTIND - 1))
release="-"; [ -n "$release" ] || usage
```

## Temp files and cleanup
```bash
tmpdir="$(mktemp -d)"
cleanup() { rm -rf -- "$tmpdir"; }
trap cleanup EXIT
trap 'exit 130' INT TERM          # EXIT trap still runs
```

## Destructive steps
```bash
target="?WEB_ROOT is empty"
case $target in /|/usr|/etc|"$HOME") die "refusing to clean $target" ;; esac
run() { if [ "$dry_run" -eq 1 ]; then echo "+ $*"; else "$@"; fi; }
run rm -rf -- "$target"/*
```

## Loops over files and lines
```bash
for f in "$dir"/*.csv; do [ -e "$f" ] || continue; process "$f"; done
find "$dir" -type f -name '*.log' -print0 | while IFS= read -r -d '' f; do gzip -- "$f"; done
while IFS= read -r line || [ -n "$line" ]; do echo "$line"; done < input.txt   # last line without newline
```

## Commands as data
```bash
args=(--archive --delete -- "$src/" "$dst/")
[ "$dry_run" -eq 1 ] && args=(--dry-run "args[@]")
rsync "args[@]"
```

## Secrets
- Read from the environment or a file with 600 permissions: `token="$(<"$CRED_FILE")"`.
- Pass to tools via stdin or env, not command-line arguments (visible in `ps`): `curl -H @- <<<"Authorization: Bearer $token"`.
- `set +x` around secret handling.

## Downloads
```bash
curl -fsSL --retry 3 -o "$tmpdir/tool.tgz" "$URL"
echo "$SHA256  $tmpdir/tool.tgz" | sha256sum -c -
```
`-f` makes HTTP errors fail instead of saving the error page.

## Locking and idempotency
```bash
exec 9>/var/lock/deploy.lock
flock -n 9 || die "another deploy is running"
mkdir -p -- "$dir"                 # no error if it exists
ln -sfn -- "$release_dir" current  # atomic switch of a symlink
```

## Logging
```bash
log() { printf '%s %s\n' "$(date -u +%FT%TZ)" "$*" >&2; }
```
Send logs to stderr so stdout stays clean for data.

## Testing a script safely
1. `bash -n script.sh` (syntax only), `shellcheck script.sh`, `python3 scripts/shell_lint.py script.sh`.
2. Run with a dry-run flag, then in a throwaway container: `docker run --rm -v "$PWD":/w -w /w bash:5 bash script.sh`.
3. Trace once with `bash -x script.sh` (secrets off).
FILE:templates/shell-review.md
# Shell script review: <script name>

**Runs from:** <cron on web-01 as root / GitHub Actions ubuntu-24.04 / Docker entrypoint (Alpine, busybox sh)>
**Shell:** <bash 5.2 / sh (dash)>   **Untrusted inputs:** <$1 release tag, hosts.txt, file names in uploads/>
**Verdict:** <BLOCK: 3 HIGH findings / OK with fixes / OK>
**Summary:** <one or two sentences: the worst risk and what the fix changes>

## Findings
| # | Severity | Code | Line | Problem | Fix |
|---|---|---|---|---|---|
| 1 | <HIGH> | <RM_EMPTY_VAR> | <15> | <rm -rf $WEB_ROOT/* deletes /* if WEB_ROOT is empty> | <rm -rf -- "?"/*> |

## Manual review notes
- <inputs that reach rm/ssh/sql/paths, and how they are validated>
- <idempotency: what happens if it runs twice or stops halfway>
- <cleanup on exit and on Ctrl+C>

## Fixed script
```bash
<full corrected script>
```

## Key changes
```diff
- rm -rf $WEB_ROOT/*
+ rm -rf -- "?"/*
```

## Behavior changes
- <now exits on the first failed command; previously continued>

## How to test safely
1. `bash -n <script>` and `python3 scripts/shell_lint.py <script>` (expect 0 HIGH)
2. `shellcheck <script>` if available
3. Dry run or a throwaway container: `<command>`
4. <rotate the exposed secret: where and who>
FILE:examples/deploy.sh
#!/bin/bash
# Deploy the web app build to /srv/www and restart the service.
# Usage: deploy.sh <release-tag>

RELEASE=$1
BUILD_DIR=/srv/builds/$RELEASE
WEB_ROOT=/srv/www
SLACK_TOKEN="xoxb-0000-EXAMPLE-not-real"

curl -fsSL https://get.example-tools.dev/install.sh | sudo bash

cd $BUILD_DIR
echo "Deploying $RELEASE" > /tmp/deploy.log

rm -rf $WEB_ROOT/*
cp -r dist/* $WEB_ROOT/

for f in $(ls $BUILD_DIR/migrations); do
  psql -f $BUILD_DIR/migrations/$f app_db
done

chmod -R 777 $WEB_ROOT/uploads

while read host; do
  ssh -o StrictHostKeyChecking=no deploy@$host "sudo systemctl restart web"
done < hosts.txt

cleanup() {
  local count=$(ls /srv/builds | wc -l)
  echo "Builds on disk: $count"
}
cleanup

curl -s -X POST -H "Authorization: Bearer $SLACK_TOKEN" \
  -d "text=Deployed `date`" https://slack.com/api/chat.postMessage
FILE:examples/deploy-fixed.sh
#!/usr/bin/env bash
# Deploy the web app build to /srv/www and restart the service.
# Usage: SLACK_TOKEN=... deploy.sh <release-tag>
set -euo pipefail

RELEASE="?usage: deploy.sh <release-tag>"
BUILD_DIR="/srv/builds/RELEASE"
WEB_ROOT="/srv/www"
SLACK_TOKEN="?set SLACK_TOKEN in the environment"

# Installer is pinned and checked instead of curl | bash.
installer="$(mktemp)"
log="$(mktemp)"
trap 'rm -f -- "$installer" "$log"' EXIT
curl -fsSL -o "$installer" https://get.example-tools.dev/install-1.4.2.sh
echo "3b1f0c9e2d4a5b6c7d8e9f00112233445566778899aabbccddeeff0011223344  $installer" | sha256sum -c -
sudo bash "$installer"

cd -- "$BUILD_DIR"
echo "Deploying RELEASE" > "$log"

rm -rf -- "?"/*
cp -r dist/. "$WEB_ROOT/"

for f in "$BUILD_DIR"/migrations/*.sql; do
  [ -e "$f" ] || continue
  psql -v ON_ERROR_STOP=1 -f "$f" app_db
done

chmod -R u=rwX,g=rX,o= "$WEB_ROOT/uploads"

while IFS= read -r host; do
  ssh -n -o StrictHostKeyChecking=yes "deploy@host" "sudo systemctl restart web"
done < hosts.txt

report_builds() {
  local count
  count="$(find /srv/builds -mindepth 1 -maxdepth 1 -type d | wc -l)"
  echo "Builds on disk: count"
}
report_builds

curl -fsS -X POST -H "Authorization: Bearer SLACK_TOKEN" \
  --data-urlencode "text=Deployed RELEASE at $(date -u +%FT%TZ)" https://slack.com/api/chat.postMessage
FILE:scripts/shell_lint.py
#!/usr/bin/env python3
"""Shell script safety linter (Python 3 standard library only).

Reads a bash or POSIX sh script and flags the mistakes that cause data loss, security
holes or silent failures: no strict mode, rm -rf on a variable that may be empty,
curl | sh, eval on variables, unquoted expansions (word splitting and globbing),
unchecked cd, parsing ls, chmod 777, hardcoded secrets, predictable /tmp files,
mktemp without a cleanup trap, read without -r, ssh eating a while-read loop's input,
local/export masking a failed command substitution, TLS or host-key checks turned
off, backticks and bashisms in /bin/sh.

It is a fast first pass, not a full parser: heredoc bodies are skipped, quotes,
comments, [[ ]], (( )), assignments and case words are understood, and every finding
names the line and a concrete fix. Silence a finding on one line with a trailing
comment "# shell-lint: disable=CODE[,CODE]".

Usage:
  python3 shell_lint.py script.sh [more.sh ...] [--json] [--min-severity MEDIUM]
                        [--ignore CODE,CODE]
  python3 shell_lint.py --self-test
Exit codes: 0 = no HIGH findings, 1 = at least one HIGH finding, 2 = unreadable input.
"""
import argparse, json, re, sys

SEV_ORDER = {"HIGH": 0, "MEDIUM": 1, "LOW": 2, "INFO": 3}
SECRET_NAME = re.compile(r"[A-Z0-9_]*(PASSWORD|PASSWD|TOKEN|SECRET|API_?KEY|ACCESS_KEY|PRIVATE_KEY)[A-Z0-9_]*")
FIXES = {
    "NO_SHEBANG": "Add '#!/usr/bin/env bash' (or '#!/bin/sh' for POSIX) as line 1 so the right shell runs it.",
    "NO_STRICT_MODE": "Add 'set -euo pipefail' after the shebang (POSIX sh: 'set -eu') so failures stop the script.",
    "NO_PIPEFAIL": "Add 'set -o pipefail' so 'cmd | tee log' fails when cmd fails.",
    "RM_EMPTY_VAR": "Guard the variable: rm -rf -- \"?VAR is empty/\"... and quote it; never build rm paths from unchecked input.",
    "RM_ROOT": "Never rm the filesystem root or /*; point at a specific directory.",
    "CURL_PIPE_SHELL": "Download to a file, verify a checksum or signature, read it, then run it.",
    "EVAL_VAR": "Avoid eval; use arrays for commands (cmd=(ls -l \"$dir\"); \"cmd[@]\") or a case statement.",
    "UNQUOTED_VAR": "Quote expansions: \"$var\", \"arr[@]\", \"$(cmd)\" to stop word splitting and globbing.",
    "CD_UNCHECKED": "Use 'cd \"$dir\" || exit 1' (or enable set -e) so later commands do not run in the wrong directory.",
    "LS_PARSING": "Use a glob (for f in ./*.log) or find -print0 | while IFS= read -r -d '' f instead of parsing ls/find output.",
    "BACKTICKS": "Use $(...) instead of backticks; it nests and quotes predictably.",
    "CHMOD_777": "Grant only what is needed (755 for dirs/executables, 644 for files, 600 for secrets).",
    "HARDCODED_SECRET": "Read the secret from the environment or a secret manager (\"?\"), rotate the exposed value.",
    "PREDICTABLE_TMP": "Use tmp=$(mktemp) or tmpdir=$(mktemp -d) instead of a fixed /tmp name (symlink and race attacks).",
    "NO_TRAP_CLEANUP": "Add trap 'rm -rf -- \"$tmpdir\"' EXIT right after mktemp.",
    "READ_WITHOUT_R": "Use 'read -r' (and IFS= read -r line) so backslashes and leading spaces survive.",
    "LOCAL_MASKS_STATUS": "Split it: 'local out; out=$(cmd)' so set -e and $? see the command's failure.",
    "TLS_DISABLED": "Remove -k/--insecure/--no-check-certificate/StrictHostKeyChecking=no; fix the CA bundle or pin the host key.",
    "SSH_STDIN_LOOP": "Use 'ssh -n' (or ssh ... < /dev/null) inside while-read loops; otherwise ssh eats the rest of the input.",
    "BASHISM_IN_SH": "Either change the shebang to bash or use the POSIX form ([ ], =, . file, no arrays).",
}


class Finding:
    def __init__(self, sev, code, line, snippet, problem):
        self.sev, self.code, self.line, self.snippet, self.problem = sev, code, line, snippet, problem

    def as_dict(self):
        return {"severity": self.sev, "code": self.code, "line": self.line,
                "snippet": self.snippet, "problem": self.problem, "fix": FIXES.get(self.code, "")}


def strip_comment(line):
    """Remove an unquoted comment. '#' starts a comment only at the start of a word."""
    state, i = None, 0
    while i < len(line):
        c = line[i]
        if state is None:
            if c == "\\":
                i += 2; continue
            if c in "'\"`":
                state = c
            elif c == "#" and (i == 0 or line[i - 1] in " \t;|&("):
                return line[:i].rstrip()
        elif state == "'":
            if c == "'":
                state = None
        else:
            if c == "\\":
                i += 2; continue
            if c == state:
                state = None
        i += 1
    return line


def logical_lines(text):
    """Yield (line_no, code_without_comment, raw_line, disabled_codes); heredoc bodies skipped."""
    lines = text.split("\n")
    pending = []  # heredoc terminators waiting, in order
    out = []
    for no, raw in enumerate(lines, 1):
        if pending:
            delim, dash = pending[0]
            body = raw.lstrip("\t") if dash else raw
            if body == delim:
                pending.pop(0)
            continue
        m = re.search(r"#\s*shell-lint:\s*disable=([A-Z_,\s]+)", raw)
        disabled = {c.strip() for c in m.group(1).split(",")} if m else set()
        code = strip_comment(raw)
        for hm in re.finditer(r"<<(-?)\s*(['\"]?)([A-Za-z_][A-Za-z0-9_]*)\2", code):
            if code[hm.start():hm.start() + 3] == "<<<":
                continue
            pending.append((hm.group(3), hm.group(1) == "-"))
        out.append((no, code, raw, disabled))
    return out


def match_paren(s, i):
    """s[i] == '(' ; return index of the matching ')' respecting quotes, or len(s)."""
    depth, state, j = 0, None, i
    while j < len(s):
        c = s[j]
        if state is None:
            if c == "\\":
                j += 2; continue
            if c in "'\"":
                state = c
            elif c == "(":
                depth += 1
            elif c == ")":
                depth -= 1
                if depth == 0:
                    return j
        elif c == state:
            state = None
        elif c == "\\" and state == '"':
            j += 1
        j += 1
    return len(s)


def unquoted_expansions(code):
    """Return names of $var / ... / $(...) / $@ expansions that are not inside quotes
    and not in a context where splitting cannot happen ([[ ]], (( )), assignments, case word)."""
    found = []
    stripped = code.strip()
    if re.match(r"case\s", stripped):
        return found
    state, i, dbl_brackets, arith = None, 0, 0, 0
    n = len(code)

    def word_start(k):
        while k > 0 and code[k - 1] not in " \t;|&(":
            k -= 1
        return k

    while i < n:
        c = code[i]
        if state == "'":
            if c == "'":
                state = None
            i += 1; continue
        if c == "\\":
            i += 2; continue
        if state is None and c == "'":
            state = "'"; i += 1; continue
        if c == '"':
            state = None if state == '"' else '"'
            i += 1; continue
        if state is None and code.startswith("[[", i) and (i == 0 or code[i - 1] in " \t;&|!("):
            dbl_brackets += 1; i += 2; continue
        if state is None and code.startswith("]]", i) and dbl_brackets:
            dbl_brackets -= 1; i += 2; continue
        if state is None and code.startswith("((", i) and (i == 0 or code[i - 1] in " \t;&|!"):
            end = match_paren(code, i)
            i = end + 1; continue
        if c == "`":
            end = code.find("`", i + 1)
            i = (end if end != -1 else n) + 1; continue
        if c == "$" and i + 1 < n:
            nxt = code[i + 1]
            if code.startswith("$((", i):
                end = match_paren(code, i + 1)
                i = end + 1; continue
            if nxt == "(":
                end = match_paren(code, i + 1)
                inner = code[i + 2:end]
                found.extend(unquoted_expansions(inner))
                if state is None and not dbl_brackets and not arith:
                    ws = word_start(i)
                    if not re.match(r"[A-Za-z_][A-Za-z0-9_]*(\[[^\]]*\])?\+?=", code[ws:i + 1]):
                        found.append("$(" + inner.strip()[:20] + ")")
                i = end + 1; continue
            m = re.match(r"\$(\{[^}]*\}|[A-Za-z_][A-Za-z0-9_]*|[@*]|[0-9])", code[i:])
            if m:
                tok = m.group(0)
                if state is None and not dbl_brackets:
                    ws = word_start(i)
                    is_assign = re.match(r"[A-Za-z_][A-Za-z0-9_]*(\[[^\]]*\])?\+?=", code[ws:i + 1])
                    if not is_assign and not tok.startswith("found.append(tok)
                i += len(tok); continue
        i += 1
    return found


def commands(code):
    """Split a line into simple commands on ; && || | (outside quotes)."""
    parts, cur, state, i = [], "", None, 0
    while i < len(code):
        c = code[i]
        if state is None and c in "'\"":
            state = c
        elif state and c == state:
            state = None
        if state is None and c in ";|&":
            parts.append(cur); cur = ""
            while i + 1 < len(code) and code[i + 1] in ";|&":
                i += 1
            i += 1; continue
        cur += c; i += 1
    parts.append(cur)
    return [p.strip() for p in parts if p.strip()]


def lint(text, name="script"):
    findings = []
    lines = logical_lines(text)
    first = text.split("\n", 1)[0]
    shebang = first if first.startswith("#!") else ""
    is_posix_sh = bool(re.search(r"(^#!\s*/bin/sh\b|/env\s+sh\b|/bin/dash\b)", shebang))
    all_code = "\n".join(c for _, c, _, _ in lines)
    strict_e = bool(re.search(r"(^|\n)\s*set\s+(-[a-zA-Z]*e[a-zA-Z]*\b|-o\s+errexit)", all_code)) or bool(re.search(r"\s-[a-z]*e", shebang))
    pipefail = "pipefail" in all_code
    uses_pipes = "|" in all_code.replace("||", "")
    uses_mktemp = "mktemp" in all_code
    has_trap = bool(re.search(r"(^|\n)\s*trap\s", all_code))

    def add(sev, code, no, snippet, problem, disabled=frozenset()):
        if code not in disabled:
            findings.append(Finding(sev, code, no, snippet.strip()[:80], problem))

    if not shebang:
        add("LOW", "NO_SHEBANG", 1, first, "no shebang line; the caller's shell decides how this runs")
    if not strict_e:
        add("MEDIUM", "NO_STRICT_MODE", 1, shebang or first, "no 'set -e' (errexit): a failed command does not stop the script")
    elif uses_pipes and not pipefail and not is_posix_sh:
        add("LOW", "NO_PIPEFAIL", 1, shebang, "pipes are used but pipefail is off: only the last command's status counts")
    if uses_mktemp and not has_trap:
        no = next((n for n, c, _, _ in lines if "mktemp" in c), 1)
        add("LOW", "NO_TRAP_CLEANUP", no, next(c for n, c, _, _ in lines if n == no), "mktemp is used but nothing removes the temp file on exit or error")

    read_loop = 0
    for no, code, raw, dis in lines:
        if not code.strip():
            continue
        if re.search(r"(^|[;&|\s])while\b.*\bread\b", code):
            read_loop += 1
        if read_loop and re.search(r"(^|[;&|\s])ssh\s", code) and not re.search(r"\bssh\s+(-\w+\s+)*-\w*n\b|<\s*/dev/null", code):
            add("MEDIUM", "SSH_STDIN_LOOP", no, code, "ssh inside a while-read loop reads the loop's stdin, so the loop stops after the first item", dis)
        if read_loop and re.search(r"(^|[;&|\s])done\b", code):
            read_loop -= 1
        # curl | sh
        if re.search(r"\b(curl|wget)\b[^|]*\|\s*(sudo\s+(-\S+\s+)*)?(ba|z|da|k)?sh\b", code):
            add("HIGH", "CURL_PIPE_SHELL", no, code, "remote script piped straight into a shell: no review, no integrity check, partial downloads run", dis)
        if re.search(r"\b(curl\b[^|;]*\s(-k|--insecure)\b|wget\b[^|;]*--no-check-certificate|StrictHostKeyChecking=no)", code):
            add("MEDIUM", "TLS_DISABLED", no, code, "certificate or host-key verification is turned off (man-in-the-middle risk)", dis)
        if re.search(r"(^|[;&|(\s])eval\s+.*\$", code):
            add("HIGH", "EVAL_VAR", no, code, "eval on a string built from variables runs any shell code an attacker or odd filename puts in it", dis)
        if re.search(r"\bchmod\s+(-[A-Za-z]+\s+)*0?777\b|\bchmod\s+(-[A-Za-z]+\s+)*[augo]*\+rwx\b", code) and re.search(r"777|a\+rwx|o\+rwx", code):
            add("MEDIUM", "CHMOD_777", no, code, "world-writable permissions let any local user change the files", dis)
        if "`" in code:
            add("LOW", "BACKTICKS", no, code, "legacy backtick command substitution", dis)
        m = re.match(r"\s*(export\s+|readonly\s+|local\s+|declare\s+(-\w+\s+)*)?(" + SECRET_NAME.pattern + r")=(['\"]?)([^$'\"\s][^'\"\s]{3,)", code)
        if m:
            val = m.group(6)
            masked = val[:2] + "*" * max(3, len(val) - 4) + val[-2:]
            add("HIGH", "HARDCODED_SECRET", no, code.replace(val, masked), f"{m.group(3)} has a literal value in the script (ends up in git, logs and ps output)", dis)
        if re.match(r"\s*(local|export|declare|readonly)\s+(-\w+\s+)*[A-Za-z_][A-Za-z0-9_]*=\"?\$\(", code):
            add("MEDIUM", "LOCAL_MASKS_STATUS", no, code, "the builtin's exit status (0) hides a failure of the command substitution, even under set -e", dis)
        if re.search(r"(^|[^\w.-])/tmp/[A-Za-z0-9_.${}-]+", code) and "mktemp" not in code:
            add("MEDIUM", "PREDICTABLE_TMP", no, code, "fixed /tmp path: another user can pre-create or symlink it, and parallel runs collide", dis)
        if re.search(r"\bfor\s+\w+\s+in\s+(\$\(|`)\s*(ls|find)\b", code) or re.search(r"\bls\b[^|]*\|\s*(while|xargs)\b", code):
            add("MEDIUM", "LS_PARSING", no, code, "parsing ls/find output breaks on spaces, newlines and glob characters in filenames", dis)
        for cmd in commands(code):
            words = cmd.split()
            if not words:
                continue
            w0 = words[0]
            while w0 in ("sudo", "command", "builtin", "exec", "!", "while", "until", "if", "then",
                         "do", "else", "elif", "{", "(") and len(words) > 1:
                words = words[1:]; w0 = words[0]
            if w0 == "rm":
                args = words[1:]
                rec = any(re.match(r"-[a-zA-Z]*[rR]", a) or a == "--recursive" for a in args)
                if any(a.strip("'\"") in ("/", "/*") for a in args):
                    add("HIGH", "RM_ROOT", no, cmd, "rm targets / or /*", dis)
                for a in args:
                    if a.startswith("-") and a != "--":
                        continue
                    if "$" in a and not re.search(r"\$\{[A-Za-z_][A-Za-z0-9_]*:\?", a):
                        a_clean = a.strip("'\"")
                        if re.match(r"\$\{?[A-Za-z_][A-Za-z0-9_]*\}?(/|\"?$)", a_clean) or rec:
                            add("HIGH" if rec else "MEDIUM", "RM_EMPTY_VAR", no, cmd,
                                f"rm{' -r' if rec else ''} on {a}: if the variable is empty or unset this deletes the wrong path (e.g. '/')", dis)
                            break
            if w0 == "cd" and not strict_e:
                if not re.search(re.escape(cmd) + r"\s*(\|\||&&)", code) and not re.search(r"(\|\||&&)\s*" + re.escape(cmd), code):
                    add("MEDIUM", "CD_UNCHECKED", no, cmd, "cd may fail and the following commands then run in the wrong directory", dis)
            if w0 == "read":
                opts = [a for a in words[1:] if a.startswith("-")]
                if not any("r" in o for o in opts):
                    add("LOW", "READ_WITHOUT_R", no, cmd, "read without -r mangles backslashes", dis)
        exps = unquoted_expansions(code)
        if exps:
            uniq = list(dict.fromkeys(exps))
            shown = ", ".join(uniq[:4]) + (" ..." if len(uniq) > 4 else "")
            only_echo = re.match(r"\s*(echo|printf)\s+[^|>]*$", code) and not any(e in ("$@", "$*") for e in uniq)
            if only_echo:
                add("LOW", "UNQUOTED_VAR", no, code, "unquoted " + shown + " in echo/printf: spacing collapses and * expands", dis)
            else:
                add("MEDIUM", "UNQUOTED_VAR", no, code, "unquoted " + shown + ": word splitting and glob expansion", dis)
        if is_posix_sh:
            bash = []
            if re.search(r"(^|[\s;&|!])\[\[\s", code): bash.append("[[ ]]")
            if re.search(r"(^|[\s;&|])\[\s[^]]*\s==\s", code): bash.append("== in [ ]")
            if re.match(r"\s*function\s+\w+", code): bash.append("function keyword")
            if re.search(r"\b[A-Za-z_]\w*=\(", code): bash.append("array")
            if re.match(r"\s*source\s", code): bash.append("source")
            if "<<<" in code: bash.append("here-string")
            if re.search(r"&>", code): bash.append("&>")
            if re.search(r"\$'", code): bash.append("$'...'")
            if bash:
                add("MEDIUM", "BASHISM_IN_SH", no, code, "bash-only syntax under #!/bin/sh (" + ", ".join(bash) + "); dash and busybox sh will fail", dis)
    findings.sort(key=lambda f: (SEV_ORDER[f.sev], f.line, f.code))
    return findings


def render_md(name, findings):
    counts = {s: sum(1 for f in findings if f.sev == s) for s in SEV_ORDER}
    out = [f"# Shell lint: {name}", "",
           f"Findings: {len(findings)} (HIGH {counts['HIGH']}, MEDIUM {counts['MEDIUM']}, LOW {counts['LOW']})", ""]
    if not findings:
        out.append("No findings.")
        return "\n".join(out)
    out += ["| Severity | Code | Line | Snippet | Problem |", "|---|---|---|---|---|"]
    for f in findings:
        snip = f.snippet.replace("|", "\\|").replace("`", "'")
        out.append(f"| {f.sev} | {f.code} | {f.line} | `{snip}` | {f.problem.replace('|', '/')} |")
    out += ["", "## Fixes", ""]
    for code in dict.fromkeys(f.code for f in findings):
        out.append(f"- {code}: {FIXES[code]}")
    return "\n".join(out)


# ---------------------------------------------------------------- self-test
def _codes(src):
    return [f.code for f in lint(src)]


def self_test():
    S = "#!/usr/bin/env bash\nset -euo pipefail\n"
    cases = [
        ("clean script has no findings", S + 'dir="$1"\ncp -- "$dir/a" "$dir/b"\n', lambda c: c == []),
        ("missing shebang", 'set -eu\necho "hi"\n', lambda c: "NO_SHEBANG" in c),
        ("missing strict mode", "#!/bin/bash\necho ok\n", lambda c: "NO_STRICT_MODE" in c),
        ("set -e without pipefail and a pipe", "#!/bin/bash\nset -e\nmake | tee log\n", lambda c: "NO_PIPEFAIL" in c),
        ("set -o errexit counts as strict", "#!/bin/bash\nset -o errexit\nset -o pipefail\necho ok\n", lambda c: c == []),
        ("rm -rf $VAR/ is HIGH", S + 'rm -rf "$BUILD_DIR"/\n', lambda c: "RM_EMPTY_VAR" in c),
        ("rm -rf ? is fine", S + 'rm -rf -- "?/"\n', lambda c: "RM_EMPTY_VAR" not in c),
        ("rm -rf / is RM_ROOT", S + "rm -rf /\n", lambda c: "RM_ROOT" in c),
        ("curl | bash", S + "curl -fsSL https://x.example/install.sh | sudo bash\n", lambda c: "CURL_PIPE_SHELL" in c),
        ("curl to file is fine", S + 'curl -fsSLo install.sh "$URL"\n', lambda c: "CURL_PIPE_SHELL" not in c),
        ("eval with variable", S + 'eval "$cmd"\n', lambda c: "EVAL_VAR" in c),
        ("unquoted var in command", S + "cp $src $dst\n", lambda c: "UNQUOTED_VAR" in c),
        ("quoted var is fine", S + 'cp "$src" "$dst"\n', lambda c: "UNQUOTED_VAR" not in c),
        ("assignment rhs is fine", S + "x=$y\nn=$(date +%s)\n", lambda c: "UNQUOTED_VAR" not in c),
        ("[[ ]] is fine", S + "if [[ $a == b ]]; then :; fi\n", lambda c: "UNQUOTED_VAR" not in c),
        ("arith is fine", S + "n=$(( $a + 1 ))\n(( count > $max ))\n", lambda c: "UNQUOTED_VAR" not in c),
        ("#arr is fine", S + 'printf "%s\\n" #arr[@]\n', lambda c: "UNQUOTED_VAR" not in c),
        ("unquoted $@", S + "run $@\n", lambda c: "UNQUOTED_VAR" in c),
        ("unquoted cmd substitution", S + "rm -- $(cat list)\n", lambda c: "UNQUOTED_VAR" in c),
        ("var inside quoted $( ) still checked", S + 'x="$(basename $path)"\n', lambda c: "UNQUOTED_VAR" in c),
        ("single quotes protect", S + "echo '$HOME is literal'\n", lambda c: "UNQUOTED_VAR" not in c),
        ("comment ignored", S + "# rm -rf $DIR/ and curl x | sh\n", lambda c: c == []),
        ("heredoc body skipped", S + "cat <<'EOF'\nrm -rf $X/\ncurl a | sh\nEOF\n", lambda c: c == []),
        ("cd unchecked without set -e", "#!/bin/bash\ncd /srv/app\n", lambda c: "CD_UNCHECKED" in c),
        ("cd || exit is fine", "#!/bin/bash\ncd /srv/app || exit 1\n", lambda c: "CD_UNCHECKED" not in c),
        ("for in $(ls)", S + "for f in $(ls *.log); do :; done\n", lambda c: "LS_PARSING" in c),
        ("backticks", S + "d=`date`\n", lambda c: "BACKTICKS" in c),
        ("chmod 777", S + "chmod -R 777 /srv/app\n", lambda c: "CHMOD_777" in c),
        ("hardcoded token, value masked", S + 'export API_TOKEN="sk_live_abcdef123456"\n',
         lambda c: "HARDCODED_SECRET" in c),
        ("secret from env is fine", S + 'API_TOKEN="?"\n', lambda c: "HARDCODED_SECRET" not in c),
        ("predictable tmp", S + 'echo "x" > /tmp/deploy.lock\n', lambda c: "PREDICTABLE_TMP" in c),
        ("mktemp without trap", S + "tmp=$(mktemp)\n", lambda c: "NO_TRAP_CLEANUP" in c),
        ("mktemp with trap fine", S + "tmp=$(mktemp)\ntrap 'rm -f -- \"$tmp\"' EXIT\n", lambda c: "NO_TRAP_CLEANUP" not in c),
        ("read without -r", S + 'while read line; do :; done < "$f"\n', lambda c: "READ_WITHOUT_R" in c),
        ("local masks status", S + "f() {\n  local out=$(git rev-parse HEAD)\n}\n", lambda c: "LOCAL_MASKS_STATUS" in c),
        ("curl -k", S + 'curl -k "$URL" -o x\n', lambda c: "TLS_DISABLED" in c),
        ("bashisms under /bin/sh", "#!/bin/sh\nset -eu\nif [[ -n \"$x\" ]]; then source ./env; fi\n",
         lambda c: "BASHISM_IN_SH" in c),
        ("bash allows [[ ]]", S + 'if [[ -n "$x" ]]; then source ./env; fi\n', lambda c: "BASHISM_IN_SH" not in c),
        ("disable comment", S + "cp $a $b  # shell-lint: disable=UNQUOTED_VAR\n", lambda c: "UNQUOTED_VAR" not in c),
        ("ssh in while-read loop", S + 'while IFS= read -r h; do\n  ssh "$h" uptime\ndone < hosts\n', lambda c: "SSH_STDIN_LOOP" in c),
        ("ssh -n in loop is fine", S + 'while IFS= read -r h; do\n  ssh -n "$h" uptime\ndone < hosts\n', lambda c: "SSH_STDIN_LOOP" not in c),
        ("case word fine", S + 'case $1 in\n  a) echo "a" ;;\nesac\n', lambda c: "UNQUOTED_VAR" not in c),
    ]
    passed = 0
    for name, src, check in cases:
        got = _codes(src)
        ok = check(got)
        passed += ok
        print(("PASS " if ok else "FAIL ") + name + ("" if ok else f"  -> {got}"))
    # masking check and exit code check
    f = [x for x in lint(S + 'export API_TOKEN="sk_live_abcdef123456"\n') if x.code == "HARDCODED_SECRET"][0]
    ok = "abcdef123456" not in f.snippet
    passed += ok; print(("PASS " if ok else "FAIL ") + "secret value masked in output")
    ok = render_md("t", []).endswith("No findings.")
    passed += ok; print(("PASS " if ok else "FAIL ") + "empty report")
    total = len(cases) + 2
    print(f"{passed}/{total} passed")
    return 0 if passed == total else 1


def main():
    ap = argparse.ArgumentParser(description="Shell script safety linter (stdlib only)")
    ap.add_argument("files", nargs="*")
    ap.add_argument("--json", action="store_true")
    ap.add_argument("--min-severity", default="LOW", choices=list(SEV_ORDER))
    ap.add_argument("--ignore", default="", help="comma-separated codes to skip")
    ap.add_argument("--self-test", action="store_true")
    a = ap.parse_args()
    if a.self_test:
        return self_test()
    if not a.files:
        ap.error("give at least one script or --self-test")
    ignore = {c.strip() for c in a.ignore.split(",") if c.strip()}
    worst, reports, js = 0, [], {}
    for path in a.files:
        try:
            with open(path, encoding="utf-8") as fh:
                text = fh.read()
        except (OSError, UnicodeDecodeError) as e:
            print(f"error: cannot read {path}: {e}", file=sys.stderr)
            return 2
        fs = [f for f in lint(text, path) if f.code not in ignore and SEV_ORDER[f.sev] <= SEV_ORDER[a.min_severity]]
        if any(f.sev == "HIGH" for f in fs):
            worst = 1
        js[path] = [f.as_dict() for f in fs]
        reports.append(render_md(path, fs))
    print(json.dumps(js, indent=2) if a.json else "\n\n".join(reports))
    return worst


if __name__ == "__main__":
    sys.exit(main())
Compares two CSV exports of the same records (old vs new, billing vs ledger, source vs warehouse) by key after normalizing headers, delimiters, currency formats, accounting negatives, dates and case. Reports added, removed and duplicate keys, key format drift, changed values per column with tolerances, possible re-keys and a control-total bridge, then writes a reconciliation report. Includes a stdlib Python checker with --self-test.
---
name: csv-diff-and-reconciliation-checker
description: Compares two CSV exports of the same records (old vs new, billing vs ledger, source vs warehouse) by key after normalizing headers, delimiters, currency formats, accounting negatives, dates and case. Reports added, removed and duplicate keys, key format drift, changed values per column with tolerances, possible re-keys and a control-total bridge, then writes a reconciliation report. Includes a stdlib Python checker with --self-test.
---

# CSV Diff and Reconciliation Checker

You help analysts, finance teams and data engineers answer "do these two files agree, and if not, exactly why?". You match rows by a business key, ignore differences that are only formatting, and turn the real differences into a short list of causes with the amounts that each one explains, so the totals tie out to the cent.

## Files in this skill

- `scripts/csv_recon.py` - matches two CSVs by key (single or composite), normalizes values, lists schema differences, duplicate and blank keys, added, removed and changed rows, key format drift and possible re-keys, and builds a control-total bridge (Python 3 standard library only)
- `references/matching-and-normalization.md` - choosing a key, header and value normalization, number and date formats, tolerances, and what each finding code means
- `references/reconciliation-playbook.md` - common causes of breaks (timing, duplicates, sign conventions, rounding, filters, encoding) and how to prove each one
- `templates/reconciliation-report.md` - the report to hand back
- `examples/billing-export-sept.csv` - September invoices from a billing system (14 rows, comma-separated)
- `examples/ledger-export-sept.csv` - the same month from the general ledger (15 rows, semicolons, $1,200.00 amounts, US dates, renamed and extra columns)

## Workflow

### 1. Understand the two files
Ask what each file is, which system and filters produced it (date range, status, entity, currency), which side is the source of truth, what the key is, and which differences matter (amounts to the cent, statuses, dates). Ask for row counts and totals the user already expects. Look at the first lines of both files before running anything.

### 2. Run the checker
```
python3 scripts/csv_recon.py examples/billing-export-sept.csv examples/ledger-export-sept.csv --key invoice_id --map customer=customer_name --tol amount=0.01 --sum amount --ignore-case --dates invoice_date
python3 scripts/csv_recon.py orders_old.csv orders_new.csv --key order_id,line_no --ignore updated_at --out-csv diff.csv
python3 scripts/csv_recon.py a.csv b.csv --key id --json
python3 scripts/csv_recon.py --self-test
```
Headers that differ only by case or spacing match automatically; renamed columns need `--map old=new`. Exit 0 means the files reconcile, 1 means differences, 2 means bad input (missing file or key column).

### 3. Explain every difference
Work down the findings (see `references/reconciliation-playbook.md`): duplicates and blank keys first (they distort everything else), then added and removed rows (timing, filters, re-keys), then changed values grouped by column and by pattern (same delta, sign flip, digits swapped, rounding). Use the bridge: old total + added - removed + changes - duplicates = new total, with nothing unexplained. Check a sample of rows by hand in both source systems.

### 4. Deliver
Fill `templates/reconciliation-report.md`: scope and inputs, result, summary counts, the bridge, each break with cause, amount, owner and fix, and what to change so next month reconciles automatically (stable keys, same filters, export formats). Attach `--out-csv` output for the people who fix the rows.

## Example result
Billing vs ledger for September: 14 vs 15 rows, 13 matched (INV-1009 matched to `inv-1009` as KEY_FORMAT_DRIFT), 11 unchanged. Breaks: INV-1011 posted twice in the ledger (HIGH DUPLICATE_KEY, +880.00), INV-1004 450.00 vs 405.00 (digits swapped, -45.00), INV-1012 open in billing but Paid in the ledger, INV-1007 missing and INV-1015 added with the same customer and amount (POSSIBLE_REKEY: posted in October under a new number). $ signs, thousands separators, (150.00) negatives, US dates and status case are formatting only; the INV-1003 rounding (1033.335 vs 1033.34) is inside the 0.01 tolerance. Bridge: 9545.965 + 310.00 - 310.00 - 44.995 + 880.00 = 10380.97, unexplained 0.

## Rules

- Never compare by row position; agree on a key first and check it is unique on both sides.
- Separate formatting noise from real differences and say which normalizations you applied.
- Every break gets a cause, an amount and an owner; "timing" is a cause only if you name the period it lands in.
- Do not net differences against each other to make totals tie; list them.
- Keep tolerances explicit and small (rounding only), never large enough to hide a real error.
- Treat customer and personal data in the files as confidential; share only what the report needs.
FILE:references/matching-and-normalization.md
# Matching and normalization

## Choosing the key
- Use a business key that both systems carry: invoice number, order id + line number, transaction id. Composite keys: `--key order_id,line_no`.
- Check uniqueness on both sides before anything else. Duplicates mean either a real double posting or a key that is not unique (e.g. invoice_id without line number).
- Avoid keys that change between systems: row numbers, surrogate database ids, names, timestamps.
- If there is no shared key, build one (date + amount + reference) and expect some ambiguous matches; review them by hand.

## Header matching
- Exact name first, then case/space/underscore/hyphen-insensitive (`Invoice ID` = `invoice_id`), reported as HEADER_FORMAT.
- Renamed columns: `--map customer=customer_name`. Columns only on one side are reported and not compared.
- A UTF-8 byte order mark (BOM) at the start of the file is removed; otherwise the first header would not match.

## Delimiters and encoding
- Comma, semicolon, tab and pipe are detected. European Excel exports often use `;` with `,` as decimal separator; this checker expects `.` decimals, so convert those first (or export again with `.`).
- Read files as UTF-8. If you see `é` instead of `é`, the file is Windows-1252: convert with `iconv -f cp1252 -t utf-8`.

## Value normalization (applied to every compared cell)
| Raw | Treated as |
|---|---|
| leading/trailing spaces, repeated inner spaces | trimmed, single space |
| `1,234.50`, `$1,234.50`, `1234.5`, `1234.50 USD` | number 1234.5 |
| `(150.00)`, `150.00-`, `-$150.00` | number -150 |
| `12.5%` | number 12.5 (not 0.125) |
| empty, `null`, `None`, `N/A`, `NA`, `-` | empty |
| `Paid` vs `paid` | different, unless `--ignore-case` |
| `09/01/2026`, `2026/09/01`, `01.09.2026` | 2026-09-01 for columns in `--dates` (US month-first unless `--dayfirst`) |

Numbers are compared as decimals, not floats, so `0.1 + 0.2` problems do not appear. Leading zeros in numeric-looking codes (`00123` vs `123`) compare equal as numbers; if that is wrong for a code column, add it to `--ignore` and compare it separately.

## Tolerances
- `--tol amount=0.01` per column, or `--tol 0.01` for every numeric column.
- Use the smallest unit of the currency for rounding differences; never use a tolerance to hide a known error.
- Values inside the tolerance are counted as FORMAT_ONLY and still appear in the bridge as changes.

## Finding codes
| Code | Severity | Meaning |
|---|---|---|
| DUPLICATE_KEY | HIGH | the same key appears more than once on one side; only the first row is compared |
| MISSING_KEY | HIGH | rows with a blank key; they cannot be matched |
| TOTAL_UNEXPLAINED | HIGH | the bridge does not tie (non-numeric cells, blank keys) |
| COLUMN_ONLY_IN_OLD / NEW | MEDIUM | schema difference; map it if it was renamed |
| ROWS_ADDED / ROWS_REMOVED | MEDIUM | keys on one side only |
| VALUE_CHANGED | MEDIUM | per column, rows whose normalized values differ |
| RAGGED_ROWS | MEDIUM | rows with more or fewer cells than the header (bad quoting, embedded delimiters) |
| NON_NUMERIC | MEDIUM | cells in a --sum column that are not numbers |
| HEADER_FORMAT | LOW | columns matched only after ignoring case and spacing |
| KEY_FORMAT_DRIFT | LOW | keys equal after ignoring case, spaces, separators and leading zeros; compared as one row |
| POSSIBLE_REKEY | LOW | a removed and an added row with the same non-key, non-date values |
| FORMAT_ONLY, DELIMITER, TOTAL_DIFF | INFO | context: equal after normalization, different delimiters, totals moved |

## The control-total bridge
```
OLD total
+ amounts of rows only in NEW
- amounts of rows only in OLD
+ (NEW - OLD) on matched rows
- extra duplicate or blank-key rows in OLD
+ extra duplicate or blank-key rows in NEW
= NEW total            (unexplained must be 0)
```
FILE:references/reconciliation-playbook.md
# Reconciliation playbook: causes of breaks and how to prove them

Work in this order: duplicates and blank keys, then rows on one side only, then changed values, then totals.

## Duplicates
- **Double posting** (same key, same values twice): a retry, an import run twice, a manual re-entry. Prove: identical rows, often the same created timestamp or batch id. Fix: reverse one posting; add an idempotency key to the import.
- **Non-unique key** (same key, different values): the key needs another column (line number, currency, entity). Re-run with a composite key.

## Rows on one side only
- **Timing / cut-off**: the record exists in both systems but in different periods (invoice dated 30 Sep, posted 1 Oct). Prove: find it in the next or previous period export. Typical sign: POSSIBLE_REKEY with a date just across the boundary.
- **Different filters**: one export excludes drafts, voids, test accounts, zero amounts, another entity or currency. Prove: compare the export queries or report settings; count the excluded statuses.
- **Re-keyed records**: credit note and re-issue, migrated ids, prefix changes (INV- vs IN-). Prove: same customer, amount and date with a new key.
- **Failed sync**: the record never reached the target. Prove: integration logs, error queue, last successful sync time.
- **Key format**: case, spaces, leading zeros, separators (KEY_FORMAT_DRIFT). Fix at the source; normalize keys in the export.

## Changed values
| Pattern | Likely cause |
|---|---|
| delta is a multiple of 9 (450 -> 405, 1,234 -> 1,324) | transposed digits on manual entry |
| exact sign flip | debit/credit convention, credit notes stored as positive with a type column |
| delta equals tax or fee rate x amount | one side gross, the other net |
| delta of 0.01 to 0.05 | rounding per line vs on the total; half-up vs banker's rounding |
| amount / rate | currency conversion, different rate date |
| date off by one day | time zone (UTC vs local) on timestamps near midnight |
| status differs | sync lag, or the systems use different state machines (paid vs settled) |
| text differs only in accents or odd characters | encoding (UTF-8 vs Windows-1252) |

## Totals
- Tie the bridge to zero before reporting. A non-zero unexplained amount means blank keys, non-numeric cells or a column that mixes currencies.
- Report totals per currency; never add USD and EUR.
- Check the totals against the system's own report (trial balance, payout report), not just against the export.

## Proving a cause
For each break: show the row(s) on both sides, the cause, the amount, and evidence (log line, export setting, the row in the next period). Mark each as: fix in source A, fix in source B, timing (will clear), or accepted difference.

## Preventing next month's breaks
- Same filters and period definition (time zone, inclusive end date) on both exports.
- Stable, unique keys carried end to end; no manual re-keying.
- Export amounts as plain numbers with `.` decimals and a separate currency column; dates as ISO 8601.
- Run the checker on a schedule and alert on HIGH findings or unexplained totals.
FILE:templates/reconciliation-report.md
# Reconciliation: <OLD source> vs <NEW source>, <period>

**Inputs:** <billing-export-sept.csv (14 rows, exported 2026-10-02 by ...)>, <ledger-export-sept.csv (15 rows)>
**Key:** <invoice_id>   **Compared columns:** <customer, amount, currency, status, invoice_date>
**Normalization:** <$ and thousands separators removed, (x) = -x, status case ignored, US dates read as dates, tolerance amount 0.01>
**Result:** <RECONCILES / DIFFERENCES FOUND: 4 breaks, net +835.005, unexplained 0>

## Summary
| Rows OLD | Rows NEW | Matched | Unchanged | Changed | Added | Removed | Duplicates |
|---|---|---|---|---|---|---|---|
| <14> | <15> | <13> | <11> | <2> | <1> | <1> | <1> |

## Control total bridge (<amount>, <USD>)
| Step | Amount |
|---|---|
| OLD total | <9,545.97> |
| + rows only in NEW | <310.00> |
| - rows only in OLD | <310.00> |
| + changes on matched rows | <-45.00> |
| + duplicates in NEW | <880.00> |
| = NEW total | <10,380.97> |
| Unexplained | <0.00> |

## Breaks
| # | Key(s) | Type | OLD | NEW | Amount | Cause (evidence) | Owner | Action |
|---|---|---|---|---|---|---|---|---|
| 1 | <INV-1011> | <Duplicate> | <880.00 x1> | <880.00 x2> | <+880.00> | <posted twice by import retry (batch 7731)> | <GL team> | <reverse second posting> |

## Formatting-only differences (no action)
- <amount formats, status case, date formats, header names>

## Recommendations
- <same filters and period definition on both exports>
- <add an idempotency key to the ledger import>

## Attachments
- <diff.csv from --out-csv (status, key, column, old, new, delta)>
FILE:examples/billing-export-sept.csv
invoice_id,customer,amount,currency,status,invoice_date
INV-1001,Northwind Traders,1200.00,USD,paid,2026-09-01
INV-1002,Blue Harbor Cafe,89.90,USD,paid,2026-09-02
INV-1003,Atlas Fitness,1033.335,USD,paid,2026-09-03
INV-1004,Greenleaf Dental,450.00,USD,paid,2026-09-05
INV-1005,Orbit Labs,2500.00,USD,paid,2026-09-08
INV-1006,Maple & Co,74.50,USD,refunded,2026-09-09
INV-1007,Copperline Studio,310.00,USD,paid,2026-09-11
INV-1008,Riverbend School,640.00,USD,paid,2026-09-12
INV-1009,Juniper Vet Clinic,195.00,USD,paid,2026-09-15
INV-1010,Northwind Traders,1200.00,USD,paid,2026-09-18
INV-1011,Summit Roofing,880.00,USD,paid,2026-09-22
INV-1012,Blue Harbor Cafe,89.90,USD,open,2026-09-25
INV-1013,Orbit Labs,-150.00,USD,credit,2026-09-26
INV-1014,Atlas Fitness,1033.33,USD,paid,2026-09-30
FILE:examples/ledger-export-sept.csv
Invoice ID;customer_name;Amount;Currency;Status;Invoice Date;gl_account
INV-1001;Northwind Traders;$1,200.00;USD;Paid;09/01/2026;4000
INV-1002;Blue Harbor Cafe;$89.90;USD;Paid;09/02/2026;4000
INV-1003;Atlas Fitness;$1,033.34;USD;Paid;09/03/2026;4000
INV-1004;Greenleaf Dental;$405.00;USD;Paid;09/05/2026;4000
INV-1005;Orbit Labs;$2,500.00;USD;Paid;09/08/2026;4000
INV-1006;Maple & Co;$74.50;USD;Refunded;09/09/2026;4000
INV-1008;Riverbend School;$640.00;USD;Paid;09/12/2026;4000
inv-1009;Juniper Vet Clinic;$195.00;USD;Paid;09/15/2026;4000
INV-1010;Northwind Traders;$1,200.00;USD;Paid;09/18/2026;4000
INV-1011;Summit Roofing;$880.00;USD;Paid;09/22/2026;4000
INV-1011;Summit Roofing;$880.00;USD;Paid;09/22/2026;4000
INV-1012;Blue Harbor Cafe;$89.90;USD;Paid;09/25/2026;4000
INV-1013;Orbit Labs;($150.00);USD;Credit;09/26/2026;4090
INV-1014;Atlas Fitness;$1,033.33;USD;Paid;09/30/2026;4000
INV-1015;Copperline Studio;$310.00;USD;Paid;10/01/2026;4000
FILE:scripts/csv_recon.py
#!/usr/bin/env python3
"""CSV diff and reconciliation checker (Python 3 standard library only).

Compares two CSV exports of the same records (old vs new, system A vs system B) by a
key, after normalizing the noise that makes naive diffs useless: spaces, header case,
thousands separators, currency signs, accounting negatives "(12.50)", number
formatting, optional text case and date formats. Reports schema differences, missing
or duplicate keys, added and removed rows, changed values per column (with numeric
tolerances), keys that only differ by format (case, leading zeros, spaces) and a
control-total bridge for amount columns: old total + added - removed + changes = new.

Usage:
  python3 csv_recon.py OLD.csv NEW.csv --key id [--key2 line] [--map old_col=new_col]
        [--ignore col,col] [--tol amount=0.01] [--sum amount] [--ignore-case]
        [--dates col,col] [--dayfirst] [--limit 20] [--out-csv diff.csv] [--json]
  python3 csv_recon.py --self-test
Exit codes: 0 = files reconcile (no differences after normalization and tolerance),
1 = differences found, 2 = bad input (missing file, missing key column).
"""
import argparse, csv, datetime, io, json, re, sys
from decimal import Decimal, InvalidOperation

SEV_ORDER = {"HIGH": 0, "MEDIUM": 1, "LOW": 2, "INFO": 3}
NUM_RE = re.compile(r"^[+-]?(\d+(\.\d*)?|\.\d+)([eE][+-]?\d+)?$")
DATE_FORMATS = ["%Y-%m-%d", "%Y/%m/%d", "%Y%m%d", "%d.%m.%Y", "%Y-%m-%dT%H:%M:%S", "%Y-%m-%d %H:%M:%S"]


class InputError(Exception):
    pass


def norm_header(h):
    return re.sub(r"[\s_\-]+", "_", h.strip().lstrip("\ufeff").lower())


def read_csv(text, name):
    text = text.lstrip("\ufeff")
    if not text.strip():
        raise InputError(f"{name} is empty")
    sample = text[:4096]
    try:
        dialect = csv.Sniffer().sniff(sample, delimiters=",;\t|")
    except csv.Error:
        dialect = csv.excel
    rows = list(csv.reader(io.StringIO(text), dialect))
    rows = [r for r in rows if any(c.strip() for c in r)]
    header = [h.strip() for h in rows[0]]
    body = []
    for i, r in enumerate(rows[1:], 2):
        if len(r) != len(header):
            body.append((i, dict(zip(header, r + [""] * (len(header) - len(r)))), len(r)))
        else:
            body.append((i, dict(zip(header, r)), len(r)))
    return header, body, getattr(dialect, "delimiter", ",")


def parse_number(s):
    """Return Decimal for '1,234.50', '$1,234.50', '(12.00)', '-5', '12.5%' (as 12.5), else None."""
    t = s.strip().replace("\u00a0", "").replace(" ", "")
    if not t:
        return None
    neg = False
    if t.startswith("(") and t.endswith(")"):
        neg, t = True, t[1:-1]
    if t.endswith("-") and NUM_RE.match(t[:-1].lstrip("$")):
        neg, t = True, t[:-1]
    t = re.sub(r"^([+-]?)(USD|EUR|GBP|[$\u20ac\u00a3])", r"\1", t)
    t = re.sub(r"(USD|EUR|GBP|[$\u20ac\u00a3])$", "", t)
    t = t.rstrip("%")
    if re.match(r"^[+-]?\d{1,3}(,\d{3})+(\.\d+)?$", t):
        t = t.replace(",", "")
    if not NUM_RE.match(t):
        return None
    try:
        d = Decimal(t)
    except InvalidOperation:
        return None
    return -d if neg else d


def parse_date(s, dayfirst):
    t = s.strip()
    fmts = DATE_FORMATS + (["%d/%m/%Y"] if dayfirst else ["%m/%d/%Y"])
    for f in fmts:
        try:
            return datetime.datetime.strptime(t, f).date().isoformat() if "%H" not in f else datetime.datetime.strptime(t, f).isoformat()
        except ValueError:
            pass
    return None


def normalize(value, col, opts):
    v = value.strip()
    if col in opts["dates"]:
        d = parse_date(v, opts["dayfirst"])
        if d:
            return ("date", d)
    n = parse_number(v)
    if n is not None:
        return ("num", n)
    if v.lower() in ("", "null", "none", "n/a", "na", "-"):
        return ("empty", "")
    v = re.sub(r"\s+", " ", v)
    return ("text", v.lower() if opts["ignore_case"] else v)


def same(a, b, col, opts):
    if a[0] == "num" and b[0] == "num":
        tol = opts["tol"].get(col, opts["tol"].get("*", Decimal(0)))
        return abs(a[1] - b[1]) <= tol
    return a == b


def key_variant(k):
    """Format-insensitive form of a key: case, spaces, separators and leading zeros."""
    t = re.sub(r"[\s\-_./]", "", k.lower())
    return re.sub(r"(?<!\d)0+(?=\d)", "", t)


def reconcile(old_text, new_text, keys, opts):
    oh, ob, odelim = read_csv(old_text, "OLD")
    nh, nb, ndelim = read_csv(new_text, "NEW")
    findings = []

    def add(sev, code, detail, count=1):
        findings.append({"severity": sev, "code": code, "detail": detail, "count": count})

    # column matching: explicit map, then exact, then normalized header
    cmap, fuzzy = {}, []
    n_by_norm = {norm_header(h): h for h in nh}
    for h in oh:
        if h in opts["map"]:
            target = opts["map"][h]
            if target not in nh:
                raise InputError(f"--map target column '{target}' not in NEW")
            cmap[h] = target
        elif h in nh:
            cmap[h] = h
        elif norm_header(h) in n_by_norm:
            cmap[h] = n_by_norm[norm_header(h)]
            fuzzy.append(f"{h} = {cmap[h]}")
    if fuzzy:
        add("LOW", "HEADER_FORMAT", f"{len(fuzzy)} column(s) matched by case/spacing only: " + "; ".join(fuzzy), len(fuzzy))
    only_old = [h for h in oh if h not in cmap]
    only_new = [h for h in nh if h not in cmap.values()]
    for h in only_old:
        add("MEDIUM", "COLUMN_ONLY_IN_OLD", f"'{h}' has no match in NEW (use --map {h}=<new name> if it was renamed)")
    for h in only_new:
        add("MEDIUM", "COLUMN_ONLY_IN_NEW", f"'{h}' has no match in OLD")
    for k in keys:
        if k not in oh:
            raise InputError(f"key column '{k}' not in OLD header {oh}")
        if cmap.get(k) not in nh:
            raise InputError(f"key column '{k}' has no match in NEW header {nh}")
    if odelim != ndelim:
        add("INFO", "DELIMITER", f"OLD uses '{odelim}', NEW uses '{ndelim}'")

    def index(body, side, colnames):
        idx, dups, blanks, ragged = {}, {}, 0, 0
        for line, row, ncells in body:
            if ncells != (len(oh) if side == "OLD" else len(nh)):
                ragged += 1
            kv = tuple(row.get(c, "").strip() for c in colnames)
            if not all(kv):
                blanks += 1
                continue
            if kv in idx:
                dups.setdefault(kv, [idx[kv][0]]).append(line)
            else:
                idx[kv] = (line, row)
        return idx, dups, blanks, ragged

    oidx, odups, oblank, orag = index(ob, "OLD", keys)
    nidx, ndups, nblank, nrag = index(nb, "NEW", [cmap[k] for k in keys])
    for side, dups in (("OLD", odups), ("NEW", ndups)):
        for kv, lines in dups.items():
            add("HIGH", "DUPLICATE_KEY", f"{side} key {'/'.join(kv)} on lines {', '.join(map(str, lines))} (only the first is compared)")
    for side, n in (("OLD", oblank), ("NEW", nblank)):
        if n:
            add("HIGH", "MISSING_KEY", f"{side} has {n} row(s) with a blank key (not compared)", n)
    for side, n in (("OLD", orag), ("NEW", nrag)):
        if n:
            add("MEDIUM", "RAGGED_ROWS", f"{side} has {n} row(s) with a different number of cells than the header", n)

    removed = [k for k in oidx if k not in nidx]
    added = [k for k in nidx if k not in oidx]
    # keys that only differ by format
    drift = []
    add_by_variant = {}
    for k in added:
        add_by_variant.setdefault(tuple(key_variant(x) for x in k), k)
    for k in list(removed):
        v = tuple(key_variant(x) for x in k)
        if v in add_by_variant:
            nk = add_by_variant.pop(v)
            drift.append((k, nk))
            removed.remove(k); added.remove(nk)
    for ok, nk in drift:
        add("LOW", "KEY_FORMAT_DRIFT", f"OLD key {'/'.join(ok)} = NEW key {'/'.join(nk)} after ignoring case, spaces, separators and leading zeros (compared as one row)")
    if removed:
        add("MEDIUM", "ROWS_REMOVED", f"{len(removed)} key(s) in OLD only: " + ", ".join('/'.join(k) for k in removed[:opts['limit']]), len(removed))
    if added:
        add("MEDIUM", "ROWS_ADDED", f"{len(added)} key(s) in NEW only: " + ", ".join('/'.join(k) for k in added[:opts['limit']]), len(added))

    compare_cols = [h for h in oh if h in cmap and h not in keys and h not in opts["ignore"]]
    pairs = [(k, k) for k in oidx if k in nidx] + drift
    changes, per_col, unchanged, fmt_only = [], {c: 0 for c in compare_cols}, 0, {c: 0 for c in compare_cols}
    for ok, nk in pairs:
        orow, nrow = oidx[ok][1], nidx[nk][1]
        row_changed = False
        for c in compare_cols:
            a_raw, b_raw = orow.get(c, ""), nrow.get(cmap[c], "")
            a, b = normalize(a_raw, c, opts), normalize(b_raw, c, opts)
            if same(a, b, c, opts):
                if a_raw.strip() != b_raw.strip():
                    fmt_only[c] += 1
                continue
            row_changed = True
            per_col[c] += 1
            delta = (b[1] - a[1]) if a[0] == "num" and b[0] == "num" else None
            changes.append({"key": "/".join(ok), "column": c, "old": a_raw, "new": b_raw,
                            "delta": str(delta) if delta is not None else ""})
        unchanged += not row_changed
    # removed and added rows that look like the same record under a new key or period
    nondate = [c for c in compare_cols if c not in opts["dates"]]
    used = set()
    for rk in removed:
        orow = oidx[rk][1]
        for ak in added:
            if ak in used or not nondate:
                continue
            nrow = nidx[ak][1]
            hits = sum(same(normalize(orow.get(c, ""), c, opts), normalize(nrow.get(cmap[c], ""), c, opts), c, opts) for c in nondate)
            if hits == len(nondate):
                used.add(ak)
                add("LOW", "POSSIBLE_REKEY", f"removed {'/'.join(rk)} and added {'/'.join(ak)} have the same values in {', '.join(nondate)} (re-keyed, re-posted or moved to another period?)")
                break
    for c, n in per_col.items():
        if n:
            add("MEDIUM", "VALUE_CHANGED", f"'{c}' differs in {n} row(s)", n)
    for c, n in fmt_only.items():
        if n:
            add("INFO", "FORMAT_ONLY", f"'{c}' equal after normalization in {n} row(s) (formatting, case or within tolerance)", n)

    bridges = []
    for col in opts["sum"]:
        if col not in oh or cmap.get(col) not in nh:
            raise InputError(f"--sum column '{col}' missing in OLD or NEW")
        def total(body, c):
            t, bad = Decimal(0), 0
            for _, row, _ in body:
                n = parse_number(row.get(c, ""))
                if n is None:
                    bad += bool(row.get(c, "").strip())
                else:
                    t += n
            return t, bad
        ot, obad = total(ob, col)
        nt, nbad = total(nb, cmap[col])
        def val(row, c):
            return parse_number(row.get(c, "")) or Decimal(0)
        s_add = sum((val(nidx[k][1], cmap[col]) for k in added), Decimal(0))
        s_rem = sum((val(oidx[k][1], col) for k in removed), Decimal(0))
        s_chg = sum((val(nidx[nk][1], cmap[col]) - val(oidx[ok][1], col) for ok, nk in pairs), Decimal(0))
        s_dup_o = sum((val(r, col) for _, r, _ in ob), Decimal(0)) - sum((val(r, col) for _, r in oidx.values()), Decimal(0))
        s_dup_n = sum((val(r, cmap[col]) for _, r, _ in nb), Decimal(0)) - sum((val(r, cmap[col]) for _, r in nidx.values()), Decimal(0))
        explained = ot + s_add - s_rem + s_chg - s_dup_o + s_dup_n
        unexplained = nt - explained
        bridges.append({"column": col, "old_total": str(ot), "added": str(s_add), "removed": str(s_rem),
                        "changed": str(s_chg), "duplicates_old": str(s_dup_o), "duplicates_new": str(s_dup_n),
                        "new_total": str(nt), "unexplained": str(unexplained), "non_numeric_old": obad, "non_numeric_new": nbad})
        if nt != ot:
            add("INFO", "TOTAL_DIFF", f"'{col}' total {ot} -> {nt} (diff {nt - ot}); see bridge")
        if unexplained != 0:
            add("HIGH", "TOTAL_UNEXPLAINED", f"'{col}' bridge leaves {unexplained} unexplained (blank keys or non-numeric cells?)")
        if obad or nbad:
            add("MEDIUM", "NON_NUMERIC", f"'{col}' has {obad} non-numeric cell(s) in OLD and {nbad} in NEW (left out of totals)", obad + nbad)

    findings.sort(key=lambda f: (SEV_ORDER[f["severity"]], f["code"]))
    summary = {"old_rows": len(ob), "new_rows": len(nb), "matched": len(pairs), "unchanged": unchanged,
               "changed_rows": len(pairs) - unchanged, "added": len(added), "removed": len(removed),
               "compared_columns": compare_cols, "column_map": {k: v for k, v in cmap.items() if k != v}}
    differs = any(f["severity"] in ("HIGH", "MEDIUM") for f in findings)
    return {"summary": summary, "findings": findings, "changes": changes, "bridges": bridges,
            "added_keys": ["/".join(k) for k in added], "removed_keys": ["/".join(k) for k in removed],
            "reconciles": not differs}


def render_md(res, old_name, new_name, limit):
    s = res["summary"]
    out = [f"# CSV reconciliation: {old_name} vs {new_name}", "",
           f"**Result:** {'RECONCILES' if res['reconciles'] else 'DIFFERENCES FOUND'}", "",
           "| Rows OLD | Rows NEW | Matched | Unchanged | Changed | Added | Removed |", "|---|---|---|---|---|---|---|",
           f"| {s['old_rows']} | {s['new_rows']} | {s['matched']} | {s['unchanged']} | {s['changed_rows']} | {s['added']} | {s['removed']} |", ""]
    if s["column_map"]:
        out.append("Column map: " + ", ".join(f"{k} -> {v}" for k, v in s["column_map"].items()))
        out.append("")
    out += ["## Findings", ""]
    if res["findings"]:
        out += ["| Severity | Code | Detail |", "|---|---|---|"]
        out += [f"| {f['severity']} | {f['code']} | {f['detail']} |" for f in res["findings"]]
    else:
        out.append("No findings.")
    if res["changes"]:
        out += ["", f"## Changed values (first {min(limit, len(res['changes']))} of {len(res['changes'])})", "",
                "| Key | Column | OLD | NEW | Delta |", "|---|---|---|---|---|"]
        out += [f"| {c['key']} | {c['column']} | {c['old']} | {c['new']} | {c['delta']} |" for c in res["changes"][:limit]]
    for b in res["bridges"]:
        out += ["", f"## Control total bridge: {b['column']}", "", "| Step | Amount |", "|---|---|",
                f"| OLD total | {b['old_total']} |", f"| + rows added | {b['added']} |", f"| - rows removed | {b['removed']} |",
                f"| + changes on matched rows | {b['changed']} |", f"| - duplicate/blank-key rows in OLD | {b['duplicates_old']} |",
                f"| + duplicate/blank-key rows in NEW | {b['duplicates_new']} |", f"| = NEW total | {b['new_total']} |",
                f"| Unexplained | {b['unexplained']} |"]
    return "\n".join(out)


def parse_args(argv):
    ap = argparse.ArgumentParser(description="CSV diff and reconciliation checker (stdlib only)")
    ap.add_argument("old", nargs="?"); ap.add_argument("new", nargs="?")
    ap.add_argument("--key", help="key column(s) in OLD, comma-separated")
    ap.add_argument("--map", action="append", default=[], help="old_col=new_col (repeatable)")
    ap.add_argument("--ignore", default="", help="columns to skip, comma-separated")
    ap.add_argument("--tol", action="append", default=[], help="col=0.01 or 0.01 for all numeric columns")
    ap.add_argument("--sum", default="", help="amount columns for the control-total bridge")
    ap.add_argument("--ignore-case", action="store_true")
    ap.add_argument("--dates", default="", help="date columns to compare as dates")
    ap.add_argument("--dayfirst", action="store_true", help="read 03/04/2026 as 3 April")
    ap.add_argument("--limit", type=int, default=20)
    ap.add_argument("--out-csv"); ap.add_argument("--json", action="store_true")
    ap.add_argument("--self-test", action="store_true")
    return ap, ap.parse_args(argv)


def build_opts(a):
    tol = {}
    for t in a.tol:
        if "=" in t:
            c, v = t.split("=", 1); tol[c.strip()] = Decimal(v)
        else:
            tol["*"] = Decimal(t)
    mp = {}
    for m in a.map:
        if "=" not in m:
            raise InputError(f"--map needs old=new, got '{m}'")
        o, n = m.split("=", 1); mp[o.strip()] = n.strip()
    split = lambda s: [x.strip() for x in s.split(",") if x.strip()]
    return {"tol": tol, "map": mp, "ignore": set(split(a.ignore)), "sum": split(a.sum),
            "ignore_case": a.ignore_case, "dates": set(split(a.dates)), "dayfirst": a.dayfirst, "limit": a.limit}


# ---------------------------------------------------------------- self-test
def self_test():
    D = Decimal
    O = "id,customer,amount,status,date\nA1,Ann,100.00,paid,2026-09-01\nA2,Bob,50,open,2026-09-02\nA3,Cy,10,paid,2026-09-03\n"
    def run(old, new, keys=("id",), **kw):
        opts = {"tol": {}, "map": {}, "ignore": set(), "sum": [], "ignore_case": False, "dates": set(), "dayfirst": False, "limit": 20}
        opts.update(kw)
        return reconcile(old, new, list(keys), opts)
    codes = lambda r: [f["code"] for f in r["findings"]]
    cases = [
        ("number 1,234.50", lambda: parse_number("1,234.50") == D("1234.50")),
        ("currency $1,234.50", lambda: parse_number("$1,234.50") == D("1234.50")),
        ("accounting (12.00)", lambda: parse_number("(12.00)") == D("-12.00")),
        ("trailing minus 5-", lambda: parse_number("5-") == D("-5")),
        ("percent 12.5%", lambda: parse_number("12.5%") == D("12.5")),
        ("text is not a number", lambda: parse_number("INV-12") is None and parse_number("1,23") is None),
        ("EUR suffix", lambda: parse_number("99.90 EUR") == D("99.90")),
        ("date formats", lambda: parse_date("2026-09-01", False) == parse_date("09/01/2026", False) == parse_date("01.09.2026", False)),
        ("dayfirst", lambda: parse_date("03/04/2026", True) == "2026-04-03"),
        ("key variant", lambda: key_variant("INV-0012") == key_variant("inv12")),
        ("identical files reconcile", lambda: run(O, O)["reconciles"] and codes(run(O, O)) == []),
        ("semicolon + formatting only", lambda: run(O, O.replace(",", ";").replace("100.00", "100").replace("50;", "50.0;"))["reconciles"]),
        ("added and removed", lambda: (lambda r: r["summary"]["added"] == 1 and r["summary"]["removed"] == 1)(
            run(O, O.replace("A3,Cy", "A4,Cy")))),
        ("value change counted", lambda: (lambda r: r["summary"]["changed_rows"] == 1 and "VALUE_CHANGED" in codes(r))(
            run(O, O.replace("50,open", "55,open")))),
        ("tolerance hides rounding", lambda: run(O, O.replace("100.00", "100.004"), tol={"amount": D("0.01")})["reconciles"]),
        ("tolerance does not hide real diff", lambda: not run(O, O.replace("100.00", "100.02"), tol={"amount": D("0.01")})["reconciles"]),
        ("ignore case", lambda: run(O, O.replace("paid", "PAID"), ignore_case=True)["reconciles"] and not run(O, O.replace("paid", "PAID"))["reconciles"]),
        ("dates compared as dates", lambda: run(O, O.replace("2026-09-01", "09/01/2026"), dates={"date"})["reconciles"]),
        ("duplicate key HIGH", lambda: "DUPLICATE_KEY" in codes(run(O, O + "A2,Bob,50,open,2026-09-02\n"))),
        ("blank key HIGH", lambda: "MISSING_KEY" in codes(run(O, O + ",Zed,5,open,2026-09-09\n"))),
        ("column only in new", lambda: "COLUMN_ONLY_IN_NEW" in codes(run(O, O.replace("date\n", "date,region\n", 1)))),
        ("header case matched", lambda: (lambda r: "HEADER_FORMAT" in codes(r) and r["reconciles"])(run(O, O.replace("customer", "Customer")))),
        ("rename via map", lambda: run(O, O.replace("customer", "client"), map={"customer": "client"})["reconciles"]),
        ("key format drift", lambda: (lambda r: "KEY_FORMAT_DRIFT" in codes(r) and r["summary"]["added"] == 0)(run(O, O.replace("A3,", "a03,")))),
        ("possible rekey", lambda: "POSSIBLE_REKEY" in codes(run(O, O.replace("A3,Cy,10,paid,2026-09-03", "A9,Cy,10,paid,2026-10-01"), dates={"date"}))),
        ("ragged rows", lambda: "RAGGED_ROWS" in codes(run(O, O + "A5,Dee,5\n"))),
        ("sign before currency", lambda: parse_number("-$5.00") == parse_number("$-5.00") == D("-5.00")),
        ("composite key", lambda: run("o,l,v\n1,1,a\n1,2,b\n", "o,l,v\n1,2,b\n1,1,a\n", keys=("o", "l"))["reconciles"]),
        ("bridge explains totals", lambda: (lambda b: D(b["unexplained"]) == 0 and b["old_total"] == "160.00" and b["new_total"] == "175.00")(
            run(O, O.replace("A3,Cy,10", "A4,Cy,20").replace("50,open", "55,open"), sum=["amount"])["bridges"][0])),
        ("bridge with duplicate", lambda: D(run(O, O + "A2,Bob,50,open,2026-09-02\n", sum=["amount"])["bridges"][0]["unexplained"]) == 0),
        ("missing key column error", lambda: _raises(lambda: run(O, O, keys=("nope",)))),
        ("empty file error", lambda: _raises(lambda: run("", O))),
        ("BOM stripped", lambda: run("\ufeff" + O, O)["reconciles"]),
        ("render has result line", lambda: "RECONCILES" in render_md(run(O, O), "a", "b", 5)),
    ]
    passed = 0
    for name, fn in cases:
        try:
            ok = bool(fn())
        except Exception as e:  # noqa: BLE001 - report in test output
            ok = False; name += f" (raised {e!r})"
        passed += ok
        print(("PASS " if ok else "FAIL ") + name)
    print(f"{passed}/{len(cases)} passed")
    return 0 if passed == len(cases) else 1


def _raises(fn):
    try:
        fn()
    except InputError:
        return True
    return False


def main(argv=None):
    ap, a = parse_args(argv if argv is not None else sys.argv[1:])
    if a.self_test:
        return self_test()
    if not (a.old and a.new and a.key):
        ap.error("need OLD NEW --key (or --self-test)")
    try:
        opts = build_opts(a)
        with open(a.old, encoding="utf-8-sig", newline="") as f1, open(a.new, encoding="utf-8-sig", newline="") as f2:
            old_text, new_text = f1.read(), f2.read()
        res = reconcile(old_text, new_text, [k.strip() for k in a.key.split(",")], opts)
    except (OSError, UnicodeDecodeError, InputError, InvalidOperation) as e:
        print(f"error: {e}", file=sys.stderr)
        return 2
    if a.out_csv:
        with open(a.out_csv, "w", newline="", encoding="utf-8") as fh:
            w = csv.writer(fh)
            w.writerow(["status", "key", "column", "old", "new", "delta"])
            for k in res["removed_keys"]:
                w.writerow(["removed", k, "", "", "", ""])
            for k in res["added_keys"]:
                w.writerow(["added", k, "", "", "", ""])
            for c in res["changes"]:
                w.writerow(["changed", c["key"], c["column"], c["old"], c["new"], c["delta"]])
    print(json.dumps(res, indent=2, default=str) if a.json else render_md(res, a.old, a.new, a.limit))
    return 0 if res["reconciles"] else 1


if __name__ == "__main__":
sys.exit(main())Plans where every batch-cooked portion lives after a meal prep session: which stay in the fridge, which go in the freezer on prep day, when to move each to the fridge to thaw, and what goes on the labels, using conservative USDA fridge and freezer times. Flags meals planned past the use-by date, foods that do not freeze, shortfalls, leftovers and a full fridge. Includes a stdlib Python planner with --self-test.
---
name: meal-prep-storage-and-use-by-planner
description: Plans where every batch-cooked portion lives after a meal prep session: which stay in the fridge, which go in the freezer on prep day, when to move each to the fridge to thaw, and what goes on the labels, using conservative USDA fridge and freezer times. Flags meals planned past the use-by date, foods that do not freeze, shortfalls, leftovers and a full fridge. Includes a stdlib Python planner with --self-test.
---

# Meal Prep Storage and Use-By Planner

You help people who batch-cook on one day eat safely all week. Given what they cooked and when they plan to eat it, you decide which portions stay in the fridge and which go straight into the freezer, schedule the thawing, and write the labels, so nothing on Friday's menu is past its fridge window and nothing is wasted.

## Files in this skill

- `scripts/prep_storage.py` - reads the batch (item, category, portions, cooked date) and the eating plan, splits portions between fridge and freezer, schedules thawing, writes labels and a day-by-day plan, and flags problems (Python 3 standard library only)
- `references/storage-times.md` - fridge and freezer times for 15 food categories with sources, and how to treat foods not on the list
- `references/cooling-thawing-reheating.md` - cooling within 2 hours, containers and labels, safe thawing, reheating and cooking temperatures, rice and other special cases
- `templates/prep-week-plan.md` - the plan to hand back (storage table, day by day, labels, notes)
- `examples/sunday-batch.csv` - a Sunday prep session: 7 items, 31 portions
- `examples/week-plan.csv` - Monday to Saturday meals that use them

## Workflow

### 1. Collect the batch and the plan
Ask what they cooked or prepped, how many portions of each, the cooking date, and which day and meal each portion is for. Map every item to a category (`python3 scripts/prep_storage.py --categories`); when unsure, pick the shorter-lived one. Ask about fridge space (how many containers fit) and whether anything was left out of the fridge for more than 2 hours (that food is not planned, it is discarded).

### 2. Run the planner
```
python3 scripts/prep_storage.py examples/sunday-batch.csv examples/week-plan.csv --fridge-capacity 16
python3 scripts/prep_storage.py batch.csv plan.csv --json
python3 scripts/prep_storage.py --categories
python3 scripts/prep_storage.py --self-test
```
Day 0 is the cooking day. Portions planned within the fridge window stay in the fridge; later ones are frozen on prep day and moved to the fridge the evening before. Use the optional `fridge_days` and `freezer_months` columns for foods not in the table (`freezer_months` 0 = do not freeze). Exit 1 means a HIGH finding (a portion would be eaten past its use-by date or before it is cooked), 2 means bad input.

### 3. Fix the plan
Resolve every finding (see `references/storage-times.md`):
- PAST_USE_BY: move that meal earlier, swap it with a freezable item, or make that food fresh mid-week.
- SHORTFALL: cook more or swap the meal; SURPLUS_NO_FREEZE: eat it earlier or cook less next time.
- FRIDGE_FULL: freeze more portions on prep day, combine portions, or prep twice a week.
Re-run until there are no HIGH findings.

### 4. Deliver
Fill `templates/prep-week-plan.md`: storage table, prep-day actions (cool, portion, label, fridge or freezer), the day-by-day list including evening "move to fridge" reminders, labels to write, and the safety notes from `references/cooling-thawing-reheating.md` that apply to this batch.

## Example result
Sunday 2026-11-01 batch: chicken burrito bowls, rice and turkey chili keep 3 fridge portions each (eat by Thursday 11-05); 2 bowls, 2 rice and 3 chili go in the freezer on Sunday, moved to the fridge Thursday and Friday evenings. The raw marinated salmon (2-day window) is frozen raw on Sunday, moved to the fridge Tuesday evening, and cooked Wednesday to 145 F / 63 C. Egg salad on Friday is day 5 and egg salad does not freeze well: HIGH PAST_USE_BY, so move that lunch to Wednesday or Thursday or make it fresh. Two hard-boiled eggs have no plan (eat by Sunday 11-08), one chili portion is a freezer spare, and 22 containers do not fit a 16-container shelf on Sunday.

## Rules

- Use the conservative end of every range and say so; when in doubt, throw it out.
- Count the cooking day as day 0; a 4-day food cooked Sunday is eaten by Thursday.
- Freezer times are for quality, not safety; fridge times are for safety. Never extend fridge times because food "looks fine".
- Thaw in the fridge, cold water or microwave, never on the counter; eat thawed cooked food within 3-4 days and do not count fridge days already used before freezing as fresh.
- Raw items get a cook-by date and a safe internal temperature, not a reheat note.
- This is general food-safety guidance, not medical advice; for pregnancy, infants, older adults or weakened immunity, follow stricter local guidance.
FILE:references/storage-times.md
# Fridge and freezer storage times

Values used by `scripts/prep_storage.py`. Fridge at 40 F / 4 C or colder, freezer at 0 F / -18 C. Day 0 is the day the food was cooked (or, for raw items, prepped/marinated after purchase).

Sources: USDA FSIS / FoodSafety.gov "Cold Food Storage Chart" and the USDA FoodKeeper app. Where a range is given, the planner uses the shorter fridge time.

| Category | Examples | Fridge (chart) | Used | Freezer (quality) | Used |
|---|---|---|---|---|---|
| cooked_meat | roast beef, pulled pork, meatballs, cooked mince | 3-4 days | 4 | 2-6 months | 3 |
| cooked_poultry | shredded chicken, turkey breast, chicken thighs | 3-4 days | 4 | 2-6 months | 3 |
| soup_stew | soups, stews, chili, curries, dal | 3-4 days | 4 | 2-3 months | 3 |
| casserole | lasagna, enchiladas, bakes, shepherd's pie | 3-4 days | 4 | 2-3 months | 3 |
| cooked_grains | rice, pasta, quinoa, couscous | 3-5 days | 4 | 1-2 months | 2 |
| cooked_vegetables | roasted or steamed vegetables, cooked beans | 3-4 days | 4 | about 2 months | 2 |
| cooked_fish | baked salmon, cooked shrimp | 3-4 days | 3 | about 3 months | 3 |
| pizza | pizza, savory pies, quiche slices | 3-4 days | 4 | 1-2 months | 2 |
| deli_salad | egg, chicken, tuna, ham, pasta salads | 3-5 days | 4 | does not freeze well | - |
| hard_boiled_eggs | peeled or unpeeled | 1 week | 7 | do not freeze | - |
| cut_raw_vegetables | carrot sticks, chopped onion, peppers | about 3-5 days (quality) | 4 | blanch first; not planned | - |
| raw_ground_meat | ground beef, turkey, pork, marinated mince | 1-2 days | 2 | 3-4 months | 3 |
| raw_poultry | chicken pieces, marinated thighs | 1-2 days | 2 | 9 months (pieces) | 9 |
| raw_steak_chops | steaks, chops, roasts | 3-5 days | 4 | 4-12 months | 4 |
| raw_fish | salmon fillets, white fish | 1-2 days | 2 | 2-3 months (fatty), 6-8 (lean) | 2 |

## Foods that do not freeze well
Mayonnaise-based salads, hard-boiled egg whites (rubbery), raw salad greens, cucumbers, cream sauces that split, fried coatings (soggy), cooked pasta in a thin sauce (mushy). Freeze sauce and pasta separately when possible.

## Mixed dishes
Use the shortest-lived ingredient: a rice bowl with fish is cooked_fish (3 days), not cooked_grains (4). Sauces and dressings stored separately follow their own label; opened store-bought sauces follow the jar.

## Foods not on the list
Add `fridge_days` and `freezer_months` columns in BATCH.csv from FoodKeeper or the product label. If no source is available, use 3 fridge days and do not freeze.

## Day counting
- Cooked Sunday, 4 days: Monday (1), Tuesday (2), Wednesday (3), Thursday (4) is the last day.
- Food frozen on prep day and thawed in the fridge: eat within 3-4 days of thawing (the planner schedules the move for the evening before).
- Food frozen on day 3 has only about 1 fridge day left after thawing; freeze early, ideally on the cooking day.

## Refreezing
Food thawed in the fridge can be refrozen without cooking (quality drops). Food thawed in cold water or the microwave must be cooked before refreezing.
FILE:references/cooling-thawing-reheating.md
# Cooling, packing, thawing and reheating

## Cooling after cooking (the 2-hour rule)
- Get cooked food into the fridge or freezer within 2 hours of cooking (1 hour if the room is above 90 F / 32 C).
- Bacteria grow fastest between 40 F and 140 F (4-60 C). Large pots cool too slowly: divide into shallow containers (about 2 in / 5 cm deep) or cool the pot in an ice bath, stirring.
- Hot food can go straight into the fridge; leave lids slightly open until it stops steaming, and do not stack hot containers.
- Rice and other starches: cool and refrigerate quickly. Spores of Bacillus cereus survive cooking and make toxins when rice sits warm; reheating does not destroy the toxin.

## Packing and labels
- One portion per container makes the plan work: you only thaw what you eat.
- Freezer: freezer bags pressed flat (fast freezing and thawing), or rigid containers with 1/2 in headspace for liquids.
- Label every container: item, cooked date, "eat by" (fridge) or "best by" (freezer), reheat or cook instruction. Masking tape and a marker are enough.
- Keep raw items on the bottom shelf, below ready-to-eat food.

## Thawing
| Method | How | After thawing |
|---|---|---|
| Fridge (best) | move the evening before; large or dense items need 24 h per 5 lb / 2.3 kg | cooked food within 3-4 days; raw ground meat, poultry, fish within 1-2 days |
| Cold water | sealed bag in cold water, change water every 30 min | cook or reheat immediately |
| Microwave | defrost setting | cook or reheat immediately |
| Counter | never | - |
Soups and stews can be reheated straight from frozen in a pot.

## Reheating and cooking temperatures (internal)
| Food | Temperature |
|---|---|
| Leftovers and casseroles, reheated | 165 F / 74 C |
| Soups, sauces, gravies | bring to a rolling boil |
| Poultry, raw | 165 F / 74 C |
| Ground beef, pork, lamb, raw | 160 F / 71 C |
| Steaks, chops, roasts, raw | 145 F / 63 C plus a 3 minute rest |
| Fish, raw | 145 F / 63 C or until it flakes and is opaque |
Microwave: cover, stir halfway, let stand 1-2 minutes, and check the center with a thermometer.

## Packed lunches
Use an insulated bag with an ice pack; reheat at work to steaming hot. Food left at room temperature more than 2 hours is discarded, not returned to the fridge.

## Signs are not a test
Spoilage bacteria (smell, slime) and pathogens (illness) are different; food can look and smell fine and still be unsafe. Follow the dates, not the nose.

## Who should be stricter
Pregnant people, infants, older adults and anyone with a weakened immune system: eat leftovers sooner, reheat to steaming hot, avoid deli salads after day 2, and follow local health guidance.
FILE:templates/prep-week-plan.md
# Meal prep plan: week of <2026-11-02>

**Prep day:** <Sunday 2026-11-01>   **People:** <2 adults>   **Fridge space:** <16 containers>
**Status:** <OK / 1 meal moved to avoid PAST_USE_BY>

## Storage plan
| Item | Category | Portions | Fridge | Freezer | Eat by (fridge) | Best by (freezer) |
|---|---|---|---|---|---|---|
| <Turkey chili> | <soup_stew> | <6> | <3> | <3> | <Thu 11-05> | <2027-02-01> |

## Prep-day checklist
- [ ] Cool everything in shallow containers; fridge or freezer within 2 hours
- [ ] Portion: one portion per container
- [ ] Freeze: <chili x3, burrito bowls x2, rice x2, salmon x2 (raw, flat)>
- [ ] Fridge: <...>
- [ ] Label every container (item, cooked date, eat by / best by, reheat or cook to)

## Day by day
| Day | Breakfast | Lunch | Dinner | Evening: move to fridge |
|---|---|---|---|---|
| <Mon 11-02> | <hard-boiled eggs x2> | <burrito bowl + rice> | <turkey chili x2> | <-> |

## Labels
| Container | Label text |
|---|---|
| <Turkey chili (fridge)> | <TURKEY CHILI - cooked Sun 11/01 - eat by Thu 11/05 - reheat to 165 F> |

## Changes made
- <Egg salad lunch moved from Fri to Wed (day 5 is past the 4-day limit)>

## Spares and leftovers
- <1 chili portion in the freezer, best by 2027-02-01>

## Safety notes for this batch
- <rice: cool fast, reheat once, steaming hot>
- <salmon: thaw in the fridge Tue evening, cook Wed to 145 F / 63 C>
FILE:examples/sunday-batch.csv
item,category,portions,cooked_on
Chicken burrito bowl,cooked_poultry,5,2026-11-01
Cilantro lime rice,cooked_grains,5,2026-11-01
Turkey chili,soup_stew,6,2026-11-01
Egg salad,deli_salad,3,2026-11-01
Hard-boiled eggs,hard_boiled_eggs,6,2026-11-01
Roasted vegetables,cooked_vegetables,4,2026-11-01
Miso salmon (raw marinated),raw_fish,2,2026-11-01
FILE:examples/week-plan.csv
date,meal,item,portions
2026-11-02,breakfast,Hard-boiled eggs,2
2026-11-02,lunch,Chicken burrito bowl,1
2026-11-02,lunch,Cilantro lime rice,1
2026-11-02,dinner,Turkey chili,2
2026-11-03,lunch,Egg salad,1
2026-11-03,dinner,Chicken burrito bowl,1
2026-11-03,dinner,Cilantro lime rice,1
2026-11-04,breakfast,Hard-boiled eggs,2
2026-11-04,lunch,Turkey chili,1
2026-11-04,dinner,Miso salmon (raw marinated),2
2026-11-04,dinner,Roasted vegetables,2
2026-11-05,lunch,Chicken burrito bowl,1
2026-11-05,lunch,Cilantro lime rice,1
2026-11-05,dinner,Roasted vegetables,2
2026-11-06,lunch,Egg salad,2
2026-11-06,dinner,Chicken burrito bowl,2
2026-11-06,dinner,Cilantro lime rice,2
2026-11-07,lunch,Turkey chili,2
FILE:scripts/prep_storage.py
#!/usr/bin/env python3
"""Meal prep storage and use-by planner (Python 3 standard library only).

Takes a batch-cooking session (what was cooked, how many portions, when) and the
week's eating plan, and decides for every portion whether it stays in the fridge or
goes into the freezer on prep day, when to move frozen portions to the fridge to thaw,
and what to write on each label. Flags portions planned after their fridge window that
cannot be frozen, plans that need more portions than were cooked, portions planned
before they are cooked, leftovers with no plan, and a fridge that holds more
containers than it has room for.

Fridge and freezer times are conservative values from the USDA/FoodSafety.gov cold
storage chart and the FoodKeeper app (see references/storage-times.md). Day 0 is the
cooking day; a 4-day item cooked on Sunday must be eaten by Thursday. Freezer times
are for quality: food kept frozen at 0 F / -18 C stays safe, it just gets worse.

Usage:
  python3 prep_storage.py BATCH.csv PLAN.csv [--fridge-capacity 12] [--json]
  python3 prep_storage.py --categories
  python3 prep_storage.py --self-test
BATCH.csv columns: item,category,portions,cooked_on[,fridge_days,freezer_months]
PLAN.csv  columns: date,meal,item,portions   (dates as YYYY-MM-DD)
Exit codes: 0 = plan is safe, 1 = at least one HIGH finding, 2 = bad input.
"""
import argparse, csv, datetime as dt, io, json, sys

SEV_ORDER = {"HIGH": 0, "MEDIUM": 1, "LOW": 2, "INFO": 3}
MEAL_ORDER = {"prep": 0, "breakfast": 1, "lunch": 2, "snack": 3, "dinner": 4, "evening": 5}
SERVE_COLD = {"deli_salad", "hard_boiled_eggs", "cut_raw_vegetables"}
# safe minimum internal temperatures for raw categories (cook on the planned day)
COOK_TEMP = {"raw_ground_meat": "160 F / 71 C", "raw_poultry": "165 F / 74 C",
             "raw_steak_chops": "145 F / 63 C plus 3 min rest", "raw_fish": "145 F / 63 C"}
# category: (fridge_days, freezer_months or None if it does not freeze well, note)
CATEGORIES = {
    "cooked_meat":       (4, 3, "cooked beef, pork, lamb; chart 3-4 days / 2-6 months"),
    "cooked_poultry":    (4, 3, "cooked chicken, turkey; chart 3-4 days / 2-6 months"),
    "soup_stew":         (4, 3, "soups, stews, chili, curries; chart 3-4 days / 2-3 months"),
    "casserole":         (4, 3, "casseroles, lasagna, bakes; 3-4 days / 2-3 months"),
    "cooked_grains":     (4, 2, "cooked rice, pasta, quinoa; cool fast; 3-5 days / 1-2 months"),
    "cooked_vegetables": (4, 2, "roasted or steamed vegetables, cooked beans; 3-4 days used"),
    "cooked_fish":       (3, 3, "cooked fish and seafood; 3-4 days, 3 used"),
    "pizza":             (4, 2, "pizza, savory pies; chart 3-4 days / 1-2 months"),
    "deli_salad":        (4, None, "egg, chicken, tuna, pasta salads; chart 3-5 days, does not freeze well"),
    "hard_boiled_eggs":  (7, None, "hard-cooked eggs; chart 1 week, do not freeze"),
    "cut_raw_vegetables": (4, None, "washed and cut raw vegetables; quality guide 3-5 days; blanch before freezing"),
    "raw_ground_meat":   (2, 3, "raw ground meat or marinated mince; chart 1-2 days / 3-4 months"),
    "raw_poultry":       (2, 9, "raw chicken or turkey pieces, marinated; chart 1-2 days / 9 months"),
    "raw_steak_chops":   (4, 4, "raw steaks, chops, roasts; chart 3-5 days / 4-12 months"),
    "raw_fish":          (2, 2, "raw fish; chart 1-2 days / 2-3 months fatty, 6-8 months lean"),
}


class InputError(Exception):
    pass


def parse_date(s, where):
    try:
        return dt.date.fromisoformat(s.strip())
    except ValueError:
        raise InputError(f"{where}: date '{s}' is not YYYY-MM-DD")


def parse_int(s, where, minimum=0):
    try:
        v = int(str(s).strip())
    except ValueError:
        raise InputError(f"{where}: '{s}' is not a whole number")
    if v < minimum:
        raise InputError(f"{where}: {v} must be at least {minimum}")
    return v


def read_rows(text, required, name):
    rows = list(csv.DictReader(io.StringIO(text.lstrip("\ufeff"))))
    if not rows:
        raise InputError(f"{name} has no rows")
    missing = [c for c in required if c not in rows[0]]
    if missing:
        raise InputError(f"{name} is missing column(s): {', '.join(missing)}")
    return [{k.strip(): (v or "").strip() for k, v in r.items() if k} for r in rows if any((v or "").strip() for v in r.values())]


def load_batch(text):
    items = {}
    for i, r in enumerate(read_rows(text, ["item", "category", "portions", "cooked_on"], "BATCH"), 2):
        where = f"BATCH line {i}"
        cat = r["category"].lower()
        if cat not in CATEGORIES and not r.get("fridge_days"):
            raise InputError(f"{where}: unknown category '{r['category']}' (see --categories, or give fridge_days/freezer_months)")
        fd, fm, note = CATEGORIES.get(cat, (None, None, "custom"))
        if r.get("fridge_days"):
            fd = parse_int(r["fridge_days"], where, 1)
        if r.get("freezer_months") is not None and r.get("freezer_months") != "":
            fm = parse_int(r["freezer_months"], where, 0) or None
        name = r["item"]
        if name.lower() in items:
            raise InputError(f"{where}: item '{name}' listed twice; give each batch its own name")
        items[name.lower()] = {"item": name, "category": cat, "portions": parse_int(r["portions"], where, 1),
                               "cooked_on": parse_date(r["cooked_on"], where), "fridge_days": fd,
                               "freezer_months": fm, "note": note}
    return items


def load_plan(text, items):
    plan = []
    for i, r in enumerate(read_rows(text, ["date", "meal", "item", "portions"], "PLAN"), 2):
        where = f"PLAN line {i}"
        key = r["item"].lower()
        if key not in items:
            raise InputError(f"{where}: item '{r['item']}' is not in BATCH")
        plan.append({"date": parse_date(r["date"], where), "meal": r["meal"], "item": key,
                     "portions": parse_int(r["portions"], where, 1)})
    plan.sort(key=lambda p: p["date"])
    return plan


def add_months(d, months):
    y, m = divmod(d.month - 1 + months, 12)
    y, m = d.year + y, m + 1
    last = (dt.date(y + (m == 12), m % 12 + 1, 1) - dt.timedelta(days=1)).day
    return dt.date(y, m, min(d.day, last))


def plan_storage(items, plan, fridge_capacity=None):
    findings, timeline, labels = [], {}, []

    def add(sev, code, item, detail):
        findings.append({"severity": sev, "code": code, "item": item, "detail": detail})

    def ev(day, slot, text):
        timeline.setdefault(day, []).append((MEAL_ORDER.get(slot.lower(), 3), text))

    summary = {}
    for key, it in items.items():
        cooked, fd, fm = it["cooked_on"], it["fridge_days"], it["freezer_months"]
        eat_by = cooked + dt.timedelta(days=fd)
        best_by = add_months(cooked, fm) if fm else None
        left = it["portions"]
        fridge_n = freeze_n = 0
        uses = [p for p in plan if p["item"] == key]
        raw = it["category"] in COOK_TEMP
        how = (f"cook to {COOK_TEMP[it['category']]}" if raw else
               "serve cold" if it["category"] in SERVE_COLD else "reheat to 165 F / 74 C")
        for p in uses:
            n = min(p["portions"], left)
            short = p["portions"] - n
            if short:
                add("MEDIUM", "SHORTFALL", it["item"], f"{p['date']} {p['meal']} needs {p['portions']} portion(s), only {n} left; cook more or swap the meal")
            if n == 0:
                continue
            left -= n
            if p["date"] < cooked:
                add("HIGH", "BEFORE_COOKED", it["item"], f"{p['date']} {p['meal']} is before the cooking day {cooked}")
                continue
            if p["date"] <= eat_by:
                fridge_n += n
                ev(p["date"], p["meal"], f"{p['meal']}: {it['item']} x{n} (fridge; {how})")
            elif fm:
                freeze_n += n
                thaw = p["date"] - dt.timedelta(days=1)
                ev(p["date"], p["meal"], f"{p['meal']}: {it['item']} x{n} (thawed; {how})")
                ev(thaw, "evening", f"evening: move {it['item']} x{n} from freezer to fridge for {p['date']} {p['meal']}")
                if best_by and p["date"] > best_by:
                    add("LOW", "PAST_FREEZER_QUALITY", it["item"], f"{p['date']} is after the best-quality date {best_by} (safe, but drier and blander)")
            else:
                fridge_n += n
                add("HIGH", "PAST_USE_BY", it["item"],
                    f"{p['date']} {p['meal']} is {(p['date'] - cooked).days} days after cooking; fridge limit is {fd} days (eat by {eat_by}) and it does not freeze well. Move the meal earlier or cook it fresh.")
        if left:
            if fm:
                freeze_n += left
                add("INFO", "SURPLUS_FROZEN", it["item"], f"{left} unplanned portion(s) go in the freezer on {cooked}; best by {best_by}")
            else:
                add("MEDIUM", "SURPLUS_NO_FREEZE", it["item"], f"{left} unplanned portion(s) do not freeze well: eat by {eat_by} or cook less next time")
                fridge_n += left
        if freeze_n:
            ev(cooked, "prep", f"freeze {it['item']} x{freeze_n} " + ("raw, flat in freezer bags" if raw else "once cooled (fridge or freezer within 2 hours of cooking)"))
        if fridge_n:
            ev(cooked, "prep", f"fridge {it['item']} x{fridge_n} ({'cook' if raw else 'eat'} by {eat_by})")
        labels.append({"item": it["item"], "cooked_on": str(cooked),
                       "fridge": f"x{fridge_n}, eat by {eat_by}" if fridge_n else "-",
                       "freezer": f"x{freeze_n}, best by {best_by}" if freeze_n else "-"})
        summary[it["item"]] = {"category": it["category"], "portions": it["portions"], "fridge": fridge_n,
                               "freezer": freeze_n, "eat_by": str(eat_by), "best_by": str(best_by) if best_by else None,
                               "fridge_days": fd, "freezer_months": fm}

    if fridge_capacity:
        days = sorted(set([it["cooked_on"] for it in items.values()] + [p["date"] for p in plan]))
        if days:
            d = days[0]
            worst = (0, None)
            while d <= days[-1]:
                count = _fridge_count(items, plan, summary, d)
                if count > worst[0]:
                    worst = (count, d)
                d += dt.timedelta(days=1)
            if worst[0] > fridge_capacity:
                add("MEDIUM", "FRIDGE_FULL", "-", f"{worst[0]} containers in the fridge on {worst[1]}, capacity {fridge_capacity}: freeze more on prep day or use bigger containers")
    findings.sort(key=lambda f: (SEV_ORDER[f["severity"]], f["item"], f["code"]))
    return {"summary": summary, "timeline": {str(k): [t for _, t in sorted(v, key=lambda x: x[0])] for k, v in sorted(timeline.items())},
            "labels": labels, "findings": findings}


def _fridge_count(items, plan, summary, day):
    """Containers in the fridge at the end of `day` (one portion = one container)."""
    total = 0
    for key, it in items.items():
        if day < it["cooked_on"]:
            continue
        eat_by = it["cooked_on"] + dt.timedelta(days=it["fridge_days"])
        fridge_left = summary[it["item"]]["fridge"]
        for p in plan:
            if p["item"] == key and p["date"] <= day and it["cooked_on"] <= p["date"] <= eat_by:
                fridge_left -= p["portions"]
        if day <= eat_by:
            total += max(fridge_left, 0)
        for p in plan:  # thawing portions moved in the evening before
            if p["item"] == key and p["date"] > eat_by and p["date"] - dt.timedelta(days=1) == day and it["freezer_months"]:
                total += p["portions"]
    return total


def render_md(res):
    out = ["# Meal prep storage plan", "", "| Item | Category | Portions | Fridge | Freezer | Eat by (fridge) | Best by (freezer) |",
           "|---|---|---|---|---|---|---|"]
    for name, s in res["summary"].items():
        out.append(f"| {name} | {s['category']} | {s['portions']} | {s['fridge']} | {s['freezer']} | {s['eat_by']} | {s['best_by'] or 'do not freeze'} |")
    out += ["", "## Day by day", ""]
    for day, evs in res["timeline"].items():
        d = dt.date.fromisoformat(day)
        out.append(f"- **{d.strftime('%a')} {day}**: " + "; ".join(evs))
    out += ["", "## Labels", "", "| Item | Cooked | Fridge | Freezer |", "|---|---|---|---|"]
    out += [f"| {l['item']} | {l['cooked_on']} | {l['fridge']} | {l['freezer']} |" for l in res["labels"]]
    out += ["", "## Findings", ""]
    if res["findings"]:
        out += ["| Severity | Code | Item | Detail |", "|---|---|---|---|"]
        out += [f"| {f['severity']} | {f['code']} | {f['item']} | {f['detail']} |" for f in res["findings"]]
    else:
        out.append("No problems: every planned portion is eaten inside its fridge window or thawed from the freezer.")
    out += ["", "Cool food within 2 hours in shallow containers, keep the fridge at 40 F / 4 C or colder and the freezer at 0 F / -18 C. When in doubt, throw it out."]
    return "\n".join(out)


# ---------------------------------------------------------------- self-test
def self_test():
    B = "item,category,portions,cooked_on\nChili,soup_stew,5,2026-11-01\nEgg salad,deli_salad,3,2026-11-01\nRice,cooked_grains,4,2026-11-01\n"
    P = ("date,meal,item,portions\n2026-11-02,lunch,Chili,1\n2026-11-03,lunch,Chili,1\n2026-11-06,dinner,Chili,2\n"
         "2026-11-02,lunch,Egg salad,1\n2026-11-04,lunch,Egg salad,1\n2026-11-03,dinner,Rice,2\n")
    def run(b=B, p=P, cap=None):
        items = load_batch(b)
        return plan_storage(items, load_plan(p, items), cap)
    codes = lambda r: [f["code"] for f in r["findings"]]
    cases = [
        ("categories table sane", lambda: all(v[0] >= 1 for v in CATEGORIES.values())),
        ("add_months end of month", lambda: add_months(dt.date(2026, 1, 31), 1) == dt.date(2026, 2, 28)),
        ("add_months over year", lambda: add_months(dt.date(2026, 11, 15), 3) == dt.date(2027, 2, 15)),
        ("fridge window day 0 = cooking day", lambda: run()["summary"]["Chili"]["eat_by"] == "2026-11-05"),
        ("chili day 5 goes to freezer", lambda: run()["summary"]["Chili"]["freezer"] == 3),
        ("chili days 1-2 stay in fridge", lambda: run()["summary"]["Chili"]["fridge"] == 2),
        ("thaw move the evening before", lambda: any("move Chili x2" in e for e in run()["timeline"]["2026-11-05"])),
        ("surplus chili frozen INFO", lambda: "SURPLUS_FROZEN" in codes(run())),
        ("egg salad inside window ok", lambda: "PAST_USE_BY" not in codes(run())),
        ("egg salad day 5 is PAST_USE_BY", lambda: "PAST_USE_BY" in codes(run(p=P.replace("2026-11-04,lunch,Egg", "2026-11-06,lunch,Egg")))),
        ("egg salad surplus no freeze", lambda: "SURPLUS_NO_FREEZE" in codes(run())),
        ("shortfall", lambda: "SHORTFALL" in codes(run(p=P + "2026-11-04,dinner,Rice,3\n"))),
        ("before cooked", lambda: "BEFORE_COOKED" in codes(run(p=P + "2026-10-31,dinner,Rice,1\n"))),
        ("past freezer quality", lambda: "PAST_FREEZER_QUALITY" in codes(run(p=P + "2027-03-01,dinner,Rice,1\n"))),
        ("override fridge_days column", lambda: run(b="item,category,portions,cooked_on,fridge_days,freezer_months\nSoup,custom,2,2026-11-01,2,0\n",
                                                   p="date,meal,item,portions\n2026-11-04,lunch,Soup,1\n")["findings"][0]["code"] == "PAST_USE_BY"),
        ("unknown category error", lambda: _raises(lambda: run(b="item,category,portions,cooked_on\nX,mystery,1,2026-11-01\n", p="date,meal,item,portions\n"))),
        ("bad date error", lambda: _raises(lambda: run(p="date,meal,item,portions\n11/02/2026,lunch,Chili,1\n"))),
        ("unknown plan item error", lambda: _raises(lambda: run(p="date,meal,item,portions\n2026-11-02,lunch,Tacos,1\n"))),
        ("zero portions error", lambda: _raises(lambda: run(b="item,category,portions,cooked_on\nChili,soup_stew,0,2026-11-01\n"))),
        ("duplicate batch item error", lambda: _raises(lambda: run(b=B + "chili,soup_stew,2,2026-11-01\n"))),
        ("missing column error", lambda: _raises(lambda: run(b="item,portions\nChili,2\n"))),
        ("case-insensitive item names", lambda: run(p=P.replace("lunch,Chili", "lunch,chili"))["summary"]["Chili"]["fridge"] == 2),
        ("fridge capacity exceeded", lambda: "FRIDGE_FULL" in codes(run(cap=4))),
        ("fridge capacity ok", lambda: "FRIDGE_FULL" not in codes(run(cap=20))),
        ("raw poultry 2 days", lambda: "PAST_USE_BY" not in codes(run(b="item,category,portions,cooked_on\nThighs,raw_poultry,2,2026-11-01\n",
                                                                   p="date,meal,item,portions\n2026-11-05,dinner,Thighs,2\n"))
                                     and run(b="item,category,portions,cooked_on\nThighs,raw_poultry,2,2026-11-01\n",
                                             p="date,meal,item,portions\n2026-11-05,dinner,Thighs,2\n")["summary"]["Thighs"]["freezer"] == 2),
        ("raw fish says cook, not reheat", lambda: any("cook to 145 F" in e for e in run(b="item,category,portions,cooked_on\nSalmon,raw_fish,1,2026-11-01\n",
                                                   p="date,meal,item,portions\n2026-11-04,dinner,Salmon,1\n")["timeline"]["2026-11-04"])),
        ("egg salad served cold", lambda: any("Egg salad x1 (fridge; serve cold)" in e for e in run()["timeline"]["2026-11-02"])),
        ("timeline sorted by meal", lambda: run(p="date,meal,item,portions\n2026-11-02,dinner,Rice,1\n2026-11-02,lunch,Chili,1\n")["timeline"]["2026-11-02"][0].startswith("lunch")),
        ("render mentions 2 hours", lambda: "2 hours" in render_md(run())),
    ]
    passed = 0
    for name, fn in cases:
        try:
            ok = bool(fn())
        except Exception as e:  # noqa: BLE001
            ok = False; name += f" (raised {e!r})"
        passed += ok
        print(("PASS " if ok else "FAIL ") + name)
    print(f"{passed}/{len(cases)} passed")
    return 0 if passed == len(cases) else 1


def _raises(fn):
    try:
        fn()
    except InputError:
        return True
    return False


def main():
    ap = argparse.ArgumentParser(description="Meal prep storage and use-by planner (stdlib only)")
    ap.add_argument("batch", nargs="?"); ap.add_argument("plan", nargs="?")
    ap.add_argument("--fridge-capacity", type=int, help="max containers your fridge shelf can hold")
    ap.add_argument("--json", action="store_true")
    ap.add_argument("--categories", action="store_true", help="list categories and storage times")
    ap.add_argument("--self-test", action="store_true")
    a = ap.parse_args()
    if a.self_test:
        return self_test()
    if a.categories:
        print("| Category | Fridge days | Freezer months | Covers |\n|---|---|---|---|")
        for k, (fd, fm, note) in CATEGORIES.items():
            print(f"| {k} | {fd} | {fm if fm else 'do not freeze'} | {note} |")
        return 0
    if not (a.batch and a.plan):
        ap.error("need BATCH.csv PLAN.csv (or --self-test / --categories)")
    try:
        with open(a.batch, encoding="utf-8") as f1, open(a.plan, encoding="utf-8") as f2:
            items = load_batch(f1.read())
            plan = load_plan(f2.read(), items)
        res = plan_storage(items, plan, a.fridge_capacity)
    except (OSError, UnicodeDecodeError, InputError) as e:
        print(f"error: {e}", file=sys.stderr)
        return 2
    print(json.dumps(res, indent=2) if a.json else render_md(res))
    return 1 if any(f["severity"] == "HIGH" for f in res["findings"]) else 0


if __name__ == "__main__":
    sys.exit(main())
